# TopK Documentation
> Hybrid search, multi-vector search, document parsing, question answering, and more in one API.
## Overview
### Introduction
URL: https://docs.topk.io/introduction
TopK is a **hybrid retrieval engine** built on object storage for **10x lower cost** and **massive scale**. It supports dense/sparse vector search, multi-vector retrieval, powerful filtering, custom ranking, and managed inference in one API.
#### Get Started
**Prerequisites**
- TopK account ([Sign up here](https://console.topk.io/login))
- TopK API key ([Get an API key here](https://console.topk.io/api-key))
##### Hybrid Search
Simple example to get you started with TopK. Check out our [guides](/guides) for more complex examples.
#### Integrations
Full Python SDK reference.
Full TypeScript/JavaScript SDK reference.
The command-line interface for TopK.
#### Security & Compliance
TopK is **SOC 2 Type I** certified. Visit the [trust center](https://trust.topk.io) for full details.
All data is encrypted in transit and at rest.
Role-based access control with full auditability.
Deploy inside your own VPC for complete isolation and data residency. [Contact us](https://topk.io/contact) for more details.
#### Learn More
Learn about TopK's architecture and how it works.
Discover core concepts and how they work together.
### Architecture
URL: https://docs.topk.io/architecture
Our public API routes to different data plane regions hosted in different geographies and cloud providers (see the full list of available [regions](/regions) here). Depending on the request type, we route requests to different write/read/inference services internally to ensure predictable performance and high availability. All data is persisted on object storage (our only durable storage) with read-through caching in memory and on NVMe SSDs.
Inference layer handles document processing and embedding generation. We run a mix of off-the-shelf inference engines and models with our proprietary models and a custom inference runtime optimized for multi-modal and multi-vector retrieval.
{/* High Level Architecture Diagram */}
#### Data Flow
TopK is a multi-tenant service, which means that each tenant shares the same physical infrastructure with other tenants in the same region. This allows us to offer lower costs and better burst capacity. For enterprise customers that require full isolation and data residency, we offer dedicated single-tenant regions or cloud-prem deployments in customer-managed VPC.
{/* Data Flow Diagram */}
We decouple services that handle read path operations (query planning and execution) from services that handle write path operations (ingestion, indexing, and compaction) to separate node pools. This helps us scale resources cost-effectively and improves performance by reducing contention on the same physical infrastructure. Each collection has its own prefix on object storage, which isolates its data and helps us scale I/O request concurrency.
#### Write Path
##### Write-Ahead Log (WAL)
Write requests are durably persisted in a write-ahead log (WAL) which is backed by object storage. Entries in the WAL use logical log sequence numbers (LSN) to guarantee strict ordering and serializability. Once a write request returns successfully, data is guaranteed to be durably persisted to object storage. We employ dynamic batching to improve write throughput (~70MB/s or ~30,000+ vectors/sec) at the cost of higher write latency (~300ms p99 \<1MB).
##### Compactor (LSM-tree)
The write-ahead log is an append-only data structure with an unbounded number of entries. To optimize query performance and reduce storage costs, we periodically flush new WAL entries into more read-optimized format. The read-optimized files are stored as sorted runs inside a log-structured merge tree (LSM-tree). This tree is then periodically compacted to minimize read amplification, remove updated or deleted data, and minimize storage space.
Since all data is persisted on object storage with massive I/O throughput, we developed a scalable compaction planner and executor that allows us to flush new WAL entries and merge existing segments in parallel on a distributed set of nodes.
#### Read Path
{/* Data Flow Diagram */}
##### Router
The router service is the front door for all read requests. It handles validation, query planning and optimization, consistent routing to optimize cache hit rates, and acts as a coordinator for distributed query execution. This decoupling allows us to horizontally scale compute resources and serve billion-scale collections with low latency and high throughput.
##### Executor
The executor service has two primary responsibilities: (1) executing (partial) query plans computed by the router and (2) caching data in memory and on NVMe SSDs. Every executor node is semi-ephemeral and fungible. In practice, this means that the persistent on-disk cache state survives restarts and deployments to minimize disruptions during rollouts. At the same time, we can lose an executor node without losing data or availability since the router will automatically redistribute requests to other executor nodes that will pull the required data from object storage.
##### Cache Hierarchy
Our query engine and storage format are designed from the ground up for multi-tier cache hierarchy. All data is persisted on object storage which is our primary/only durable storage. Executor nodes then cache a subset of this data required for query execution in memory and on locally attached NVMe SSDs to minimize latency and maximize throughput.
Cache placement and I/O requests are handled by our I/O runtime (based on `io_uring`) optimized to efficiently utilize the massive read throughput of object storage and NVMe SSDs.
#### Query Engine (`reactor`)
{/* Plan diagram */}
`reactor` is our proprietary query engine that enables us to combine different retrieval types, filter predicates, and scoring expressions in a single query. Conceptually, it's similar to other pull-based query engines (e.g. DataFusion) with heavy optimizations for zero-copy execution, search-specific SIMD kernels, quantization, vectorized filtering, pruning, and more. Additionally, it supports distributed query executions which allows us to reuse the same logical/physical operators in router and executor services.
#### File Format (`.bob`)
`.bob` is our proprietary columnar file format designed from the ground up for search on object storage. It supports zero-copy and zero-decode I/O with type-specific containers for compressed dense and sparse vectors, tensors, inverted indices, and more.
#### CMU DB: TopK Talk
Check out our talk at the Carnegie Mellon University Database Group where we dive deeper into the TopK architecture, `reactor`, `.bob`, and more.
### Concepts
URL: https://docs.topk.io/concepts
#### Collection
Collection is a low-level abstraction for storing JSON-like documents with indexed fields. Collections have an opt-in [schema](/collections/manage#schema) that defines required and optional fields, field data types, and field indexes. Every document stored in a collection must have an `_id` field as a unique primary key.
#### Indexes
Documents inside a collection can have multiple indexed fields defined in the collection schema. Field indexes enable efficient retrieval of documents based on [dense and sparse](/collections/manage#vector-index) vector embeddings, [multi-vector](/collections/manage#multi-vector-index) embeddings (late interaction), [keywords](/collections/manage#keyword-index) (BM25), [semantic similarity](/collections/manage#semantic-index), and their combinations.
The ability to store and search multiple indexed fields per document minimizes storage overhead, makes filtering more efficient, and gives users flexibility at query time without having to re-ingest their data or maintain multiple indexes.
#### Filtering
Filtering allows queries to select only documents that match a specific condition. Filter expressions can be simple ([comparison](/collections/query#comparison-operators)) or complex ([AND](/collections/query#and)/[OR](/collections/query#or) operators, [ANY](/collections/query#any)/[ALL](/collections/query#all) operators, [regex](/collections/query#regexp_match) patterns, and [more](/collections/query#filtering)). Additionally, you can use computed fields (for example, similarity score) to filter documents in the result set.
Filters are always applied before sorting and aggregation (top-k) to guarantee that the final results contain every document matching the filter, even if there is just one. We also guarantee that recall stays the same (or improves) when using higly selective filters.
#### Custom Scoring
Similarity is not the same as relevance. Custom scoring expressions enable relevance tuning (for example, [boosting](/collections/query#boost) more recent documents) inside the query without having to over-fetch results and re-score them in the application layer. You can combine computed fields (similarity score, recency score, etc.) with any metadata fields (for example, source quality) inside your scoring expression to define your ranking.
Scoring expressions are always computed before sorting and aggregation to guarantee that the final results contain the most relevant documents according to your ranking logic.
#### Compute-Storage Separation
All data in TopK is durably stored in object storage. Read/write compute nodes are statless which means that any node can immediately take over serving requests in case of a node failure. This decoupled architecture enables cost-effective scaling and high availability without having to run consensus-based replication (Raft or Paxos) inside the cluster.
#### Read-Write Separation
Different applications have different read/write patterns and latency requirements. We designed our system with decoupled read and write paths to minimize the impact of write/indexing/compaction operations on query performance. This enables sustained high-throughput writes without query latency spikes caused by background compaction or indexing contenting for resources on the same node.
#### Multi-tenancy
TopK supports massively multi-tenant use cases with partitioned collections. Each partition within a collection is
fully isolated which ensures that documents from different tenants are not visible to each other. This design also enables
TopK to scale write throughput and read throughput horizontally with the number of partitions (tenants) in a collection.
Partitioned collections behave like regular collections, supporting all [index types](/collections/manage#indexes) and full [query capabilities](/collections/query).
##### Storing documents for a specific tenant
To store documents for a specific tenant, provide the tenant ID as `partition_name` alongside the `collection_name`
when creating the collection client. Partitions are created implicity on the first write.
```python Python
client.collection("books", "tenant-1234").upsert([
{"_id": "doc-1", "title": "The Great Gatsby", "author": "F. Scott Fitzgerald"},
{"_id": "doc-2", "title": "To Kill a Mockingbird", "author": "Harper Lee"},
])
```
```typescript Javascript
await client.collection("books", "tenant-1234").upsert([
{ _id: "doc-1", title: "The Great Gatsby", author: "F. Scott Fitzgerald" },
{ _id: "doc-2", title: "To Kill a Mockingbird", author: "Harper Lee" },
]);
```
##### Querying documents for a specific tenant
Similarly to writes, you can query documents for a specific tenant by providing the tenant ID as `partition_name` alongside the `collection_name`
when creating the collection client. Queries for missing partitions will return `PartitionNotFound` error.
```python Python
client.collection("books", "tenant-1234").query(
select("title")
.filter(match("gatsby"))
.limit(10)
)
```
```typescript Javascript
await client.collection("books", "tenant-1234").query(
select({
title: field("title"),
})
.filter(match("gatsby"))
.limit(10)
);
```
#### Read Consistency
TopK supports three different consistency levels, allowing you to choose the right trade-off between consistency, performance, and cost. By default, we provide a **Balanced Consistency Mode**, which balances data freshness (~750ms p99 write-to-queryable) and query efficiency for most applications. Below, we explain how TopK handles data writes and reads and how each consistency mode impacts behavior.
##### **Balanced Consistency (Default)**
Reads in this mode consider both indexed files and the most recent writes. While there may be a small delay of less than a second for some recent writes to appear, this mode offers lower cost compared to strong consistency. It is ideal for most real-world applications where near-real-time updates are sufficient.
```python Python
client.collection("my_collection").query(
query,
# no need to specify consistency mode
)
```
```typescript Javascript
await client.collection("my_collection").query(
query
// no need to specify the consistency mode
);
```
**How It Works:**
- The **Router** checks both compacted files and a cached view of the **WAL** (refresh rate is less than 1s)
- This introduces a chance of delay: if a write has just been added to WAL but hasn't been cached yet, it may not show up in a read
- However, this delay is minimal (less than 1s in most cases), making it a practical and efficient default
---
##### **Indexed Consistency**
Reads in this mode only consider fully compacted files and ignore recent WAL writes to deliver constantly low query latency. This is best suited for workloads
with asynchronous write path that are not sensitive to recent writes being visible in queries with low delay.
```python Python
client.collection("my_collection").query(
..., # query
consistency="indexed",
)
```
```typescript Javascript
await client
.collection("my_collection")
.query(query, { consistency: "indexed" });
```
**How It Works:**
- The **Router** forwards queries only to the **Executor**, which reads from compacted files
- WAL is ignored, meaning queries are always served from stable, processed data
- This reduces query latency and load, making it the most cost-efficient option for high-throughput reads
---
##### **Strong Consistency**
Reads in this mode always return the latest writes before responding. While this ensures that all queries see the most recent updates, it comes with higher latency and cost due to additional WAL reads. This mode recommended for cases where clients always need to see the most recent writes.
```python Python
client.collection("my_collection").query(
..., # query
consistency="strong",
)
```
```typescript Javascript
await client
.collection("my_collection")
.query(query, { consistency: "strong" });
```
**How It Works:**
- Before serving a read, the **Router explicitly checks the WAL** to ensure the latest writes are reflected
- This guarantees that all queries see the most recent updates but adds overhead because it requires an additional lookup
- Strong consistency ensures that all queries see the most recent updates but is **more expensive** than other modes due to the extra computation
---
##### Choosing the Right Mode
| Consistency Mode | Freshness | Cost | Query performance |
| ---------------------- | ----------------------------- | ------ | ----------------- |
| **Balanced (Default)** | Near real-time (less than 1s) | Low | Good |
| **Indexed** | Only compacted data | Low | Fastest |
| **Strong** | All writes are visible | Higher | Slower |
For most use cases, **Balanced Consistency** offers the best trade-off between performance and correctness. However, if you prioritize low query latency over recency, **Indexed Consistency** is the right choice. When no staleness is allowed, **Strong Consistency** ensures every read reflects the latest write.
---
##### LSN-based Consistency
For even more precise control over consistency, TopK also supports **LSN (Log Sequence Number)** based consistency. This approach allows you to ensure read-after-write consistency by specifying the exact sequence number of a write operation in your queries.
For detailed information about using LSNs in queries, see our [LSN-based Consistency](/collections/query#lsn-based-consistency) guide in the Query documentation.
### Limits
URL: https://docs.topk.io/limits
These limits are subject to change as we continuously improve our system. If you expect to be blocked by any of these, please
let us know.
#### Collection Limits
| Scope | Production limit |
|-----------------------------------|---------------------------------|
| Max collections | Unlimited |
| Max documents (global) | Unlimited |
| Max documents (per partition) | 1B+ |
| Write throughput (global) | Unlimited |
| Write throughput (per partition) | ~70MB/s |
| Query throughput (global) | Unlimited |
| Query throughput (per partition) | 1k+ queries/s |
| Max document size | 200KB |
| Max indexed fields | Unlimited (up to document size) |
| Max dense vector dimension | 16,384 |
| Max sparse vector dimension | 2^32-1 |
| Max multi-vector dimension | 1024 |
| Max upsert request size | 8MB |
| Recall | 95%+ |
Per-partition limits apply independently, so total collection throughput grows with the number of partitions. Learn more about [Partitions and Multi-tenancy](/concepts#multi-tenancy).
### Regions
URL: https://docs.topk.io/regions
TopK region is where your data is stored. It maps to a specific cloud region.
Choose the region that is geographically closest to your application, your agents, or your end users for the best latency.
Currently available public regions:
| Cloud | Region | Location | Name |
|-------|---------|-----------|-----|
| AWS | us-east-1 | 🇺🇸 N. Virginia | `aws-us-east-1-elastica` |
| AWS | eu-central-1 | 🇪🇺 Frankfurt | `aws-eu-central-1-monstera` |
| GCP | us-east4 | 🇺🇸 N. Virginia | `gcp-us-east4-aloe` |
To deploy TopK in your own VPC, please [contact us](https://topk.io/contact).
### Changelog
URL: https://docs.topk.io/changelog
{/* ## May 2026
- structs */}
#### June 2026
- **Features**: Added [`Partitioned Collections`](https://docs.topk.io/sdk/topk-py/index#collection) (Namespaces) for effortless multi-tenancy with fully isolated, on-demand partitions.
- **Features**: Made [`SQL`](https://docs.topk.io/sdk/topk-sql/overview) your Search Query Language for hybrid and multi-vector search—no proprietary query language required.
- **Features**: Introduced [`semantic_index`](https://docs.topk.io/guides/semantic-search) enabling production-ready multi-vector retrieval with a single schema annotation.
- **Performance**: Optimized SMVE kernel to match GPU performance with just 8 CPU threads.
#### May 2026
- **Features**: Added native support for [`structs`](https://docs.topk.io/sdk/topk-py/schema#struct) with full indexing and filtering capabilities. Search and filter nested structured data without flattening your schema.
- **Research**: Released [`Iso-ModernColBERT`](https://huggingface.co/topk-io/Iso-ModernColBERT), a late interaction model optimized for efficient inference and scalable retrieval. Built to deliver strong retrieval performance in production environments with strict latency and throughput requirements.
#### April 2026
- **Datasets API**: Shipped datasets API for unstructured document [ingestion](/datasets/ingest), [search](/datasets/search), and grounded [question answering](/datasets/ask). Give your agents context from complex PDFs, Markdown, HTML, and more.
- [**CLI**](/cli): Manage datasets, ingest documents, and query them from your terminal.
- [**MCP**](/mcp-server): Connect private data inside datasets to your agents.
#### March 2026
- **Features**: Added support for tuning [`BM25`](https://docs.topk.io/sdk/topk-py/query#bm25_score). Configure your own `b` and `k1` parameters to adjust ranking behavior and refine result relevance.
- **Blog**: Published a post about [`SMVE`](https://www.topk.io/blog/20260311-smve-multi-vector-retrieval) — an algorithm for scaling multi-vector retrieval, focusing on improved efficiency and performance for large-scale workloads.
#### February 2026
- **Features**: Enabled native support for state-of-the-art retrieval models via multi-vector retrieval. ~5.5x faster than PLAID, ~7.5 faster than MUVERA with 1-bit, 2-bit and scalar quantization to optimize storage efficiency.
- **Features**: Added native support for [`f8`](https://docs.topk.io/sdk/topk-py/schema#f8_vector) and [`f16`](https://docs.topk.io/sdk/topk-py/schema#f16_vector) vector types to optimize embedding storage size and improve efficiency when storing large document collections.
#### January 2026
- **Features**: Added support for multi-vector [`indexing`](https://docs.topk.io/sdk/topk-py/schema#multi_vector_index) and [`querying`](https://docs.topk.io/sdk/topk-py/query#multi_vector_distance), enabling more advanced multi-embedding retrieval use cases.
- **Features**: Introduced the [`list.starts_with`](https://docs.topk.io/sdk/topk-py/query#starts_with) operator in our query language, enabling efficient prefix filtering on array string fields.
#### November 2025
- **Features**: Added support for [`regular-expression`](/collections/query#regexp_match) filtering in our query language, enabling more flexible querying logic.
- **Benchmarks**: Published the new [`TopK Benchmarks`](https://www.topk.io/blog/20251201-topk-bench) results, showcasing performance and scalability across production-like workloads for multiple providers.
- **Billing**: Shipped billing, unlocking end-to-end usage tracking and payment workflows.
- **Performance**: Shipped distributed compaction to optimize cost and improve indexing throughput per collection.
#### October 2025
- **Features**: Added [`update()`](https://docs.topk.io/sdk/topk-py/index#update)API to simplify partial record updates.
- **Features**: Shipped support for [`delete-by-filter`](/collections/write#delete-documents-by-filter-expression) operations for more flexible bulk deletions.
- **Docs & SDKs**: Added support for Cohere’s embed-v4 model in [`semantic_index()`](https://docs.topk.io/sdk/topk-py/schema#semantic-index) and exposed organization limits in ddb-management-plane for improved visibility and management.
#### September 2025
- **Docs & SDKs**: Published SDK reference for [**Python**](https://docs.topk.io/sdk/topk-py) and [**JavaScript**](https://docs.topk.io/sdk/topk-js) clients, and added detailed docstrings for a smoother developer experience in both SDKs
- **Python SDK**: Released [`AsyncClient`](https://docs.topk.io/sdk/topk-py/index#asyncclient) for easier async workflows.
- **String Operators**: Added [`lt`](/collections/query#lt), [`lte`](/collections/query#lte), [`gt`](https://docs.topk.io/sdk/topk-py/query#gt), [`gte`](https://docs.topk.io/sdk/topk-py/query#gte), [`min`](/collections/query#min), and [`max`](https://docs.topk.io/sdk/topk-py/query#max).
- **Query Helpers**: Introduced [`any`](https://docs.topk.io/sdk/topk-py/query#any) and [`all`](https://docs.topk.io/sdk/topk-py/query#all) helpers.
- **List Support**: Added [`contains`](https://docs.topk.io/sdk/topk-py/query#contains) and [`in`](https://docs.topk.io/sdk/topk-py/query#in) operators for list fields.
- **Observability**: Added Query Latency and Write Latency charts to the Usage Metrics in [console](https://console.topk.io/).
- **New Data Type**: Added [`int8`](https://docs.topk.io/sdk/topk-py/schema#i8-vector) vector support.
- **Eager Caching**: Added support for eager caching to mitigate tail latencies for concurrent read/write workloads.
- **Faster GETs**: Added option to cache raw document data and improved performance with zero-copy design.
- **Performance**: Improved performance for queries with default & strong [consistency level](https://docs.topk.io/sdk/topk-py/index#consistencylevel).
#### August 2025
- **Lists Data Type**: Native support for [list](https://docs.topk.io/sdk/topk-py/data#list) fields.
- **Performance**: Added [`skip_refine`](https://docs.topk.io/sdk/topk-py/query#vector-distance) query option to improve speed when reranking isn’t needed.
- **Monitoring**: Usage Metrics now available directly in the [console](https://console.topk.io/).
#### July 2025
- **Math Operators**: Added [`ln`](https://docs.topk.io/sdk/topk-py/query#ln), [`exp`](https://docs.topk.io/sdk/topk-py/query#exp), [`sqrt`](https://docs.topk.io/sdk/topk-py/query#sqrt), [`square`](https://docs.topk.io/sdk/topk-py/query#square), [`min`](https://docs.topk.io/sdk/topk-py/query#min-2), [`max`](https://docs.topk.io/sdk/topk-py/query#max-2), and [`abs`](https://docs.topk.io/sdk/topk-py/query#abs).
- **Advanced Querying**: Introduced [`choose`](https://docs.topk.io/sdk/topk-py/query#choose), [`match_all`](https://docs.topk.io/sdk/topk-py/query#match-all), [`match_any`](https://docs.topk.io/sdk/topk-py/query#match-any), [`coalesce`](https://docs.topk.io/sdk/topk-py/query#coalesce), and [`boost`](https://docs.topk.io/sdk/topk-py/query#boost) (with null coalescing).
- **Binary Data**: Added [`bytes()`](https://docs.topk.io/sdk/topk-py/data#bytes) constructor to the Python SDK.
- **Performance**: Optimized workload distribution for large-scale deployments.
#### June 2025
- **Sparse Vectors**: Added support for [f32](https://docs.topk.io/sdk/topk-py/schema#f32-sparse-vector) and [u8](https://docs.topk.io/sdk/topk-py/schema#u8-sparse-vector) sparse vector fields.
- **Benchmarks**: Published [billion-scale benchmarks](https://www.topk.io/benchmarks) for dense & sparse vector search with filtering.
## Collection API
### Write
URL: https://docs.topk.io/collections/write
Documents in TopK are JSON-like objects composed of key-value pairs.
Each document within a collection:
- Must include a unique `_id` field
- Must conform to the schema defined for the collection
Fields defined in the schema can be indexed for vector, keyword, or other retrieval strategies.
#### Upsert documents
To upsert documents, pass a list of documents to the [`upsert()`](/sdk/topk-py#upsert) function:
```python Python
client.collection("books").upsert(
[
{
"_id": "book-1",
"title": "The Great Gatsby",
"published_year": 1925,
"title_embedding": [0.12, 0.67, 0.82, 0.53, ...]
},
{
"_id": "book-2",
"title": "To Kill a Mockingbird",
"published_year": 1960,
"title_embedding": [0.42, 0.53, 0.65, 0.33, ...]
},
{
"_id": "book-3",
"title": "1984",
"published_year": 1949,
"title_embedding": [0.59, 0.33, 0.71, 0.61, ...]
}
]
)
```
```typescript Javascript
await client.collection("books").upsert([
{
_id: "book-1",
title: "The Great Gatsby",
published_year: 1925,
title_embedding: [0.12, 0.67, 0.82, 0.53],
},
{
_id: "book-2",
title: "To Kill a Mockingbird",
published_year: 1960,
title_embedding: [0.42, 0.53, 0.65, 0.33],
},
{
_id: "book-3",
title: "1984",
published_year: 1949,
title_embedding: [0.59, 0.33, 0.71, 0.61],
},
]);
```
```sql SQL
-- INSERT has upsert semantics: an existing document with the same _id is replaced
INSERT INTO books (_id, title, published_year, title_embedding)
VALUES
('book-1', 'The Great Gatsby', 1925, '[0.12, 0.67, 0.82, 0.53]'::f32_vector),
('book-2', 'To Kill a Mockingbird', 1960, '[0.42, 0.53, 0.65, 0.33]'::f32_vector),
('book-3', '1984', 1949, '[0.59, 0.33, 0.71, 0.61]'::f32_vector);
```
- Every document must have a **string** `_id` field.
- If a document with the specified `_id` doesn't exist, a new document will be **inserted**.
- If a document with the same `_id` already exists, the existing document will be **replaced** with the new one.
The `upsert()` function does not perform a _partial update_ or _merge_ - the entire document is being replaced.
Each document you send is serialized as a Protocol Buffers (protobuf) message. The encoded size of that message must be **128KB or smaller**.
##### Additional (non-schema) fields
You may include fields that are not defined in the collection schema.
These fields:
- Are stored with the document
- Can be returned to the client in query results
- Can be used for **filtering** in queries
Fields that are not defined in the schema are not indexed.
If you want to use a field for [vector search](/guides/vector-search), [semantic search](/guides/semantic-search), [keyword search](/guides/keyword-search) or [multi-vector search](/guides/multi-vector-search), it must be declared in the schema
and have a corresponding index defined.
```python Python
from topk_sdk.schema import text, int, f32_vector, vector_index, keyword_index
from topk_sdk.query import select, field, fn
client.collections().create(
"books",
schema={
"title": text().index(keyword_index()).required(),
"published_year": int().required(),
"title_embedding": f32_vector(dimension=1024).index(vector_index(metric="cosine")).required(),
},
)
client.collection("books").upsert([
{
"_id": "book-1",
"title": "The Great Gatsby",
"published_year": 1925,
"title_embedding": [0.12, 0.67, 0.82, 0.53, ...],
"tags": ["fiction", "classic"], # non-schema field
"source_url": "https://example.com/gatsby", # non-schema field
}
])
client.collection("books").query(
select(
"title",
"source_url",
"title_similarity": fn.semantic_similarity("title", "classic American novel"),
)
.filter(field("tags").contains("fiction")) # non-schema fields can still be used for filtering
)
```
```typescript Javascript
import { text, int, f32Vector, vectorIndex, keywordIndex } from "topk-js/schema";
import { select, field, fn } from "topk-js/query";
await client.collections().create("books", {
title: text().index(keywordIndex()).required(),
published_year: int().required(),
title_embedding: f32Vector({ dimension: 1024 })
.index(vectorIndex({ metric: "cosine" }))
.required()
});
await client.collection("books").upsert([
{
_id: "book-1",
title: "The Great Gatsby",
published_year: 1925,
title_embedding: [0.12, 0.67, 0.82, 0.53],
tags: ["fiction", "classic"], // non-schema field
source_url: "https://example.com/gatsby", // non-schema field
},
]);
const docs = await client.collection("books").query(
select({
title: field("title"),
source_url: field("source_url"),
title_similarity: fn.semanticSimilarity("title", "classic American novel"),
})
.filter(field("tags").contains("fiction")) // non-schema fields can still be used for filtering
);
```
##### Supported types
TopK documents are a flat structure of key-value pairs.
The following value types are supported:
| Type | Python Type | JavaScript Type | Helper Function |
|-----------------------|------------------|-----------------|-----------------------------------------------------------------|
| **String** | `str` | `string` | - |
| **Integer** | `int` | `number` | - |
| **Float** | `float` | `number` | - |
| **Boolean** | `bool` | `boolean` | - |
| **Timestamp** | `datetime.datetime` / `datetime.date` / `int` (epoch ms) | `Date` / `number` (epoch ms) | - |
| **String list** | `list[str]` | `string[]` | [`string_list()`](../sdk/topk-py/data#string-list) |
| **F32 list** | `list[float]` | `number[]` | [`f32_list()`](../sdk/topk-py/data#f32-list) |
| **F64 list** | _use helper_ | _use helper_ | [`f64_list()`](../sdk/topk-py/data#f64-list) |
| **I32 list** | _use helper_ | _use helper_ | [`i32_list()`](../sdk/topk-py/data#i32-list) |
| **I64 list** | _use helper_ | _use helper_ | [`i64_list()`](../sdk/topk-py/data#i64-list) |
| **U32 list** | _use helper_ | _use helper_ | [`u32_list()`](../sdk/topk-py/data#u32-list) |
| **F8 vector** | _use helper_ | _use helper_ | [`f8_vector()`](../sdk/topk-py/data#f8-vector) |
| **F16 vector** | _use helper_ | _use helper_ | [`f16_vector()`](../sdk/topk-py/data#f16-vector) |
| **F32 vector** | `list[float]` | `number[]` | [`f32_vector()`](../sdk/topk-py/data#f32-vector) |
| **U8 vector** | _use helper_ | _use helper_ | [`u8_vector()`](../sdk/topk-py/data#u8-vector) |
| **I8 vector** | _use helper_ | _use helper_ | [`i8_vector()`](../sdk/topk-py/data#i8-vector) |
| **Binary vector** | _use helper_ | _use helper_ | [`binary_vector()`](../sdk/topk-py/data#binary-vector) |
| **F32 sparse vector** | _use helper_ | _use helper_ | [`f32_sparse_vector()`](../sdk/topk-py/data#f32-sparse-vector) |
| **U8 sparse vector** | _use helper_ | _use helper_ | [`u8_sparse_vector()`](../sdk/topk-py/data#u8-sparse-vector) |
| **Matrix** | _use helper_ | _use helper_ | [`matrix()`](../sdk/topk-py/data#matrix-2) |
| **Bytes** | _use helper_ | _use helper_ | [`bytes()`](../sdk/topk-py/data#bytes) |
| **Struct** | `dict[str, Any]` | `Record` | [`struct()`](../sdk/topk-py/data#struct) |
#### Delete documents
You can delete documents by their `_id` or using a [filter expression](/collections/query#filtering). Both methods provide
the same consistency guarantees and will be reflected in query/get results according to your [consistency level](/concepts#read-consistency).
##### Delete documents by `_id`
To delete documents by their `_id`, pass a list of `_id`s to the [`delete()`](/sdk/topk-py#delete) method:
```python Python
client.collection("books").delete(
["book-1", "book-2", "book-3"]
)
```
```typescript Javascript
await client.collection("books").delete(["book-1", "book-2", "book-3"]);
```
```sql SQL
DELETE FROM books WHERE _id IN ('book-1', 'book-2', 'book-3');
```
The `delete()` method returns an **LSN** (Log Sequence Number) that you can pass to subsequent queries for [read-after-write consistency](/collections/query#lsn-based-consistency).
##### Delete documents by filter expression
To delete documents that match a predicate, you can pass a [filter expression](/collections/query#filtering) to the `delete()` function.
```python Python
from topk_sdk.query import field
client.collection("books").delete(field("published_year").lt(1997))
```
```typescript Javascript
import { field } from "topk-js/query";
await client.collection("books").delete(field("published_year").lt(1997));
```
```sql SQL
DELETE FROM books WHERE published_year < 1997;
```
Passing a filter expression to `delete()` is useful for deleting documents that match a specific condition, such as all documents for a **specific tenant** e.g. `field("_id").starts_with("tenant-123/")`.
### Query
URL: https://docs.topk.io/collections/query
TopK provides a data frame-like syntax for querying documents. It features built-in **semantic search**, **text search**, **vector search**, and metadata **filtering** capabilities.
With TopK's declarative query builder, you can easily select fields, chain filters, and apply vector/text search in a composable manner.
#### Query structure
In TopK, a query consists of multiple stages:
Select static or computed fields that will be returned in the query results. These fields can be used in stages such as Filter or TopK.
Filter the documents that will be returned in the query results. Filters can be applied to static fields, computed fields such as `vector_distance()` or `semantic_similarity()`, or custom properties computed inside `select()`.
Order results by an expression (ascending or descending).
Return at most `k` results.
}
>
Return the total number of documents matching the query.
All queries **must** have either Sort + Limit or Count collection stage.
You can stack multiple select and filter stages in a single query.
A typical query in TopK looks as follows:
```mermaid
flowchart TD
A[Select]
A --> B[Filter]
B --> C[Sort]
B --> F[Count]
C --> D[Limit]
D --> H@{ shape: stadium, label: "Results collection" }
F --> I@{ shape: stadium, label: "Results count" }
```
#### Select
The `select()` function is used to initialize the select stage of a query. It accepts a key-value pair of field names and field expressions:
```python Python
from topk_sdk.query import select, field
client.collection("books").query(
select(
"published_year", # elect the static fields directly
title=field("title"),
)
...
)
```
```js Javascript
import { select, field } from "topk-js/query";
await client.collection("books").query(
select({
title: field("title"),
})
...
)
```
##### Select expressions
Use a `field()` function to select fields from a document. In the select stage, you can also rename existing fields
or define computed fields using [function expressions](#function-expressions).
```python Python
from topk_sdk.query import select, field
docs = client.collection("books").query(
select(
"title", # the actual "title" field from the document
year=field("published_year"), # renamed field
year_plus_ten=field("published_year") + 10, # computed field
)
)
```
```js Javascript
import { select, field } from "topk-js/query";
const docs = await client.collection("books").query(
select({
title: field("title"), // the actual "title" field from the document
year: field("published_year"), // renamed field
year_plus_ten: field("published_year").add(10), // computed field
})
);
```
```sql SQL
SELECT
title, -- static field
published_year AS year, -- renamed field
published_year + 10 AS year_plus_ten -- computed field
FROM books
LIMIT 10;
```
##### Function expressions
Function expressions are used to define computed fields that will be included in your query results. TopK currently supports four main function expressions:
- `vector_distance(field, vector)`: Computes distance between vectors for vector search. This function is available for all dense and sparse vector types.
- `bm25_score()`: Calculates relevance scores using the BM25 algorithm for keyword search
- `semantic_similarity(field, query)`: Measures semantic similarity between the provided text query and the field's embedding
- `multi_vector_distance(field, matrix)`: Computes MaxSim distance for multi-vector (matrix) fields. Requires a [`multi_vector_index()`](/sdk/topk-py/schema#multi_vector_index) on the field. See [multi-vector search](/guides/multi-vector-search).
###### Vector distance
The [`vector_distance()`](/sdk/topk-py/query#vector_distance) function is used to compute the vector score between a query vector and a vector field in a collection.
There are **multiple ways** to represent a query vector:
- Dense vectors:
- `[0.1, 0.2, 0.3, ...]` - Array of numbers resolved as a **dense float32 vector**
- `f32_vector([...])` - Helper function returning a **dense float32 vector**
- `f16_vector([...])` - Helper function returning a **dense float16 vector**
- `f8_vector([...])` - Helper function returning a **dense float8 vector**
- `u8_vector([...])` - Helper function returning a **dense u8 vector**
- `i8_vector([...])` - Helper function returning a **dense i8 vector**
- `binary_vector([...])` - Helper function returning a **binary vector**
- Sparse vectors:
- `{ 0: 0.1, 1: 0.2, 2: 0.3, ... }` - Mapping from index → value resolved as a **sparse float32 vector**
- `f32_sparse_vector({ ... })` - Helper function returning a **sparse float32 vector**
- `u8_sparse_vector({ ... })` - Helper function returning a **sparse u8 vector**
Optionally, uses can provide `skip_refine=True` to bypass the internal distance refinement step. This will improve performance for queries with large `top_k` at the cost of lower accuracy.
We don't recommend using `skip_refine=True` unless you're using a large `top_k`.
To use the `vector_distance()` function, you **must** have a [**vector index**](http://docs.topk.io/collections/create#vector-index) defined on the field you're computing the vector distance against:
```python Python
from topk_sdk.query import select, field, fn
docs = client.collection("books").query(
select(
"title",
title_similarity=fn.vector_distance(
"title_embedding",
[0.1, 0.2, 0.3, ...] # embedding for "animal"
)
)
.sort(field("title_similarity"), asc=False).limit(10)
)
### Example result:
[
{
"_id": "2",
"title": "To Kill a Mockingbird",
"title_similarity": 0.7484796643257141
},
{
"_id": "1",
"title": "The Catcher in the Rye",
"title_similarity": 0.5471329569816589
}
]
```
```js Javascript
import { select, field, fn } from "topk-js/query";
const docs = await client.collection("books").query(
select({
title: field("title"),
title_similarity: fn.vectorDistance(
"title_embedding",
[0.1, 0.2, 0.3 /* embedding for "animal" */]
),
})
);
// Example result:
[
{
_id: '2',
title: 'To Kill a Mockingbird',
title_similarity: 0.7484796643257141
},
{
_id: '1',
title: 'The Catcher in the Rye',
title_similarity: 0.5471329569816589,
}
]
```
```sql SQL
SELECT
title,
vector_distance(title_embedding, '[0.1, 0.2, ..., 0.3]'::f32_vector) AS title_similarity
FROM books
ORDER BY title_similarity DESC
LIMIT 10;
```
###### BM25 Score
The BM25 score is a relevance score that can be used to score documents based on their text content.
To use the `fn.bm25_score()` in your query, you **must** include a `match` predicate in your filter stage.
To use the `fn.bm25_score()` function, you **must** have a [**keyword index**](http://docs.topk.io/collections/create#keyword-index) defined in your collection schema.
```python Python
from topk_sdk.query import select, field, fn, match
docs = client.collection("books").query(
select(
"title",
text_score=fn.bm25_score(),
)
.filter(match("Good")) # must include a match predicate
.sort(field("text_score"), asc=False).limit(10)
)
### Example result:
[
{
"_id": "1",
"title": "Good Night, Bat! Good Morning, Squirrel!",
"text_score": 0.2447269707918167
},
{
"_id": "2",
"title": "Good Girl, Bad Blood",
"text_score": 0.20035339891910553
}
]
```
```js Javascript
import { select, field, fn, match } from "topk-js/query";
const results = await client.collection("books").query(
select({
title: field("title"),
text_score: fn.bm25Score(),
})
.filter(match("Good"))
.sort(field("text_score"), false).limit(10)
);
// Example result:
[
{
_id: '1',
title: 'Good Night, Bat! Good Morning, Squirrel!',
text_score: 0.2447269707918167,
},
{
_id: '2',
title: 'Good Girl, Bad Blood',
text_score: 0.20035339891910553
}
]
```
```sql SQL
SELECT
title,
bm25_score() AS text_score
FROM books
WHERE match_any(title, 'Good')
ORDER BY text_score DESC
LIMIT 10;
```
###### Semantic similarity
The `semantic_similarity()` function is used to compute the similarity between a **text query** and a **text field** in a collection.
To use the `semantic_similarity()` function, you **must** have a [**semantic index**](http://docs.topk.io/collections/create#semantic-index) defined on the field you're computing the similarity on.
```python Python
from topk_sdk.query import select, field, fn
docs = client.collection("books").query(
select(
"title",
title_similarity=fn.semantic_similarity("title", "animal"),
)
.sort(field("title_similarity"), asc=False).limit(10)
)
### Example result:
[
{
"_id": "2",
"title": "To Kill a Mockingbird",
"title_similarity": 0.7484796643257141
},
{
"_id": "1",
"title": "The Catcher in the Rye",
"title_similarity": 0.5471329569816589
}
]
```
```js Javascript
import { select, field, fn } from "topk-js/query";
const docs = await client.collection("books").query(
select({
title: field("title"),
title_similarity: fn.semanticSimilarity("title", "animal"),
})
.sort(field("title_similarity"), false).limit(10)
);
// Example result:
[
{
_id: '2',
title: 'To Kill a Mockingbird',
title_similarity: 0.7484796643257141
},
{
_id: '1',
title: 'The Catcher in the Rye',
title_similarity: 0.5471329569816589
}
]
```
```sql SQL
SELECT
title,
semantic_similarity(title, 'animal') AS title_similarity
FROM books
ORDER BY title_similarity DESC
LIMIT 10;
```
###### Multi-vector distance
The `multi_vector_distance()` function computes the MaxSim score between a query matrix and a matrix field in a collection. Use it for multi-vector (late-interaction) retrieval when documents are stored as `N x D` embedding matrices.
To use `multi_vector_distance()`, you **must** have a [`multi_vector_index()`](/sdk/topk-py/schema#multi_vector_index) defined on the field. The query matrix can be a list of lists (defaults to f32), a numpy array (type inferred from dtype), or a [`matrix()`](/sdk/topk-py/data#matrix-2) instance. The optional `candidates` parameter limits the number of candidate vectors considered during search.
```python Python
from topk_sdk.query import select, field, fn
docs = client.collection("passages").query(
select(
"content",
dist=fn.multi_vector_distance(
"token_embeddings",
[[0.1, 0.2, ...], [0.4, 0.5, ...]], # query matrix
candidates=100,
),
)
.sort(field("dist"), asc=False).limit(10)
)
```
```js Javascript
import { select, field, fn } from "topk-js/query";
const docs = await client.collection("passages").query(
select({
content: field("content"),
dist: fn.multiVectorDistance(
"token_embeddings",
[[0.1, 0.2, ...], [0.4, 0.5, ...]], // query matrix
100 // optional: candidates
),
})
.sort(field("dist"), false).limit(10)
);
```
```sql SQL
SELECT
content,
multi_vector_distance(
token_embeddings,
'[[0.1, 0.2, ..., 0.0], [0.4, 0.5, ..., 0.1]]'::f32_matrix,
100
) AS dist
FROM passages
ORDER BY dist DESC
LIMIT 10;
```
See [multi-vector search](/guides/multi-vector-search) for schema setup and ingestion details.
##### Advanced select expressions
TopK doesn't only let you select static fields from your documents or computed fields using function expressions.
You can also use TopK powerful expression language to select fields by chaining arbitrary logical expressions:
```python Python
from topk_sdk.query import select, field
select(
weight_in_grams=field("weight").mul(1000),
is_adult=field("age").gt(18),
published_in_nineteenth_century=field("published_year") >= 1800 & field("published_year") < 1900,
)
```
```js Javascript
import { select, field } from "topk-js/query";
select({
weight_in_grams: field("weight").mul(1000),
is_adult: field("age").gt(18),
published_in_nineteenth_century: field("published_year")
.gte(1800)
.and(field("published_year").lt(1900)),
});
```
#### Filtering
You can filter documents by **metadata**, **keywords**, **custom properties** computed inside `select()` (e.g. vector similarity or BM25 score) and more.
Filter expressions support all
- [logical operators](#logical-operators),
- [comparison operators](#comparison-operators),
- [mathematical operators](#mathematical-operators).
##### Metadata filtering
```python Python
.filter(
field("published_year") > 1980
)
```
```js Javascript
.filter(field("published_year").gt(1980))
```
```sql SQL
WHERE published_year > 1980
```
##### Keyword search
The `match()` function is the backbone of keyword search in TopK.
It allows you to search for documents that contain specific keywords or phrases.
You can configure the `match()` function to:
- Match on multiple terms
- Match only on specific fields
- Use weights to prioritize certain terms
The `match()` function accepts the following parameters:
String token to match. Can also contain multiple terms separated by a delimiter which is any **non-alphanumeric** character.
Field to match on.
If not provided, the function will match on all fields.
Weight to use for matching.
If not provided, the function will use the default weight(**1.0**).
Use `all` parameter when a text **must** contain all terms(separated by a delimeter)
- when `all` is `false` (default) it's an equivalent of `OR` operator
- when `all` is `true` it's an equivalent of `AND` operator
Searching for a term like `"catcher"` in your documents is as simple as using the `match()` function in the filter stage of your query:
```python Python
from topk_sdk.query import match
.filter(
match("catcher")
)
```
```js Javascript
import { match } from "topk-js/query";
.filter(match("catcher"))
```
```sql SQL
WHERE match_any(title, 'catcher')
```
###### Match multiple terms
The `match()` function can be configured to match all terms when using a **delimiter**.
A term delimiter is any **non-alphanumeric** character.
To ensure that all terms are matched, use the `all` parameter:
```python Python
from topk_sdk.query import match
.filter(match("catcher|rye", field="title", all=True))
```
```js Javascript
import { match } from "topk-js/query";
.filter(match("catcher|rye", { field: "title", weight: 1, all: true }))
```
```sql SQL
WHERE match_all(title, 'catcher rye')
```
###### Give weight to specific terms
You can give weight to specific terms by using the `weight` parameter:
```python Python
from topk_sdk.query import match
.filter(match("catcher", weight=2.0) | match("rye", weight=1.0))
```
```js Javascript
import { match } from "topk-js/query";
.filter(match("catcher", { weight: 2.0 }).or(match("rye", { weight: 1.0 })))
```
###### Boost ranking with optional terms
The `should()` function adds an optional BM25 scoring term without filtering documents from the result set.
Documents containing the term receive a higher BM25 score, while documents that do not contain it remain eligible for the results. Use `should()` together with `match()` when some terms are required and others should only influence ranking.
When used on its own, `should()` matches the entire collection and ranks documents according to how well they match the term.
```python Python
from topk_sdk.query import match, should
.filter(match("hobbit rings", field="title") & should("lord", field="title"))
```
```js Javascript
import { match, should } from "topk-js/query";
.filter(match("hobbit rings", { field: "title" }).and(should("lord", { field: "title" })))
```
```sql SQL
WHERE match('hobbit rings', title) AND should('lord', title)
```
This returns only documents matching `hobbit` or `rings`, while boosting documents that also match `lord`.
The `should()` function accepts the following parameters:
String token to score against.
Keyword-indexed field used for scoring.
Searches all eligible fields when omitted.
Multiplier applied to the term's BM25 contribution.
Defaults to **1.0**.
##### Combine keyword search and metadata filtering
You can combine metadata filtering and keyword search in a single query by stacking multiple filter stages.
In the example below, we're searching for documents that contain the keyword `"catcher"` and were published in `1997`, or between `1920` and `1980`.
```python Python
.filter(
match("catcher")
)
.filter(
field("published_year") == 1997 | (field("published_year") >= 1920 & field("published_year") <= 1980)
)
```
```js Javascript
.filter(
match("catcher")
)
.filter(
field("published_year").eq(1997).or(field("published_year").gte(1920).and(field("published_year").lte(1980)))
)
```
```sql SQL
WHERE match_any(title, 'catcher')
AND (published_year = 1997
OR (published_year >= 1920 AND published_year <= 1980))
```
#### Operators
When writing queries, you can use the following operators for:
- field selection
- filtering
- topk collection
##### Logical operators
Logical operators combine multiple expressions by applying boolean logic and conditions.
###### and
The `and` operator can be used to combine multiple logical expressions.
```python Python
.filter(
field("published_year") == 1997 & field("title") == "The Catcher in the Rye"
)
### or
.filter(
field("published_year").eq(1997).and_(field("title").eq("The Catcher in the Rye"))
)
```
```js Javascript
.filter(
field("published_year").eq(1997).and(field("title").eq("The Catcher in the Rye"))
)
```
###### or
The `or` operator can be used to combine multiple logical expressions.
```python Python
.filter(
field("published_year") == 1997 | field("title") == "The Catcher in the Rye"
)
### or
.filter(
field("published_year").eq(1997).or_(field("title").eq("The Catcher in the Rye"))
)
```
```js Javascript
.filter(
field("published_year").eq(1997).or(field("title").eq("The Catcher in the Rye"))
)
```
###### not
The `not` helper can be used to **negate** a logical expression. It takes an expression as an argument and inverts its logic.
```python Python
from topk_sdk.query import field, not_
.filter(
not_(field("title").contains("Catcher"))
)
```
```typescript Javascript
import { field, not } from "topk-js/query";
.filter(
not(field("title").contains("Catcher"))
)
```
###### all
The `all()` helper evaluates to `true` if each expression in the array is true. It's equivalent to applying the logical AND operator across all expressions.
```python Python
from topk_sdk.query import all, field
.filter(
all([
field("published_year") >= 1900,
field("published_year") <= 2000,
field("title").is_not_null()
])
)
```
```typescript Javascript
import { all, field } from "topk-js/query";
.filter(
all([
field("published_year").gte(1900),
field("published_year").lte(2000),
field("title").isNotNull()
])
)
```
This is equivalent to:
```python Python
field("published_year") >= 1900 & field("published_year") <= 2000 & field("title").is_not_null()
```
```typescript Javascript
field("published_year").gte(1900).and(field("published_year").lte(2000)).and(field("title").isNotNull())
```
###### any
The `any()` helper evaluates to `true` if at least one expression in the array is true. It's equivalent to applying the logical OR operator across all expressions.
```python Python
from topk_sdk.query import any, field
.filter(
any([
field("genre") == "fiction",
field("genre") == "mystery",
field("genre") == "thriller"
])
)
```
```typescript Javascript
import { any, field } from "topk-js/query";
.filter(
any([
field("genre").eq("fiction"),
field("genre").eq("mystery"),
field("genre").eq("thriller")
])
)
```
This is equivalent to:
```python Python
field("genre") == "fiction" | field("genre") == "mystery" | field("genre") == "thriller"
```
```typescript Javascript
field("genre").eq("fiction").or(field("genre").eq("mystery")).or(field("genre").eq("thriller"))
```
###### choose
The `choose` operator evaluates a condition and returns the first argument if the condition is true, else the second argument.
```python Python
select(
summary=(field("book_type") == "fiction").choose(
field("plot_summary"),
field("technical_summary")
)
)
```
```js Javascript
select({
summary: field("book_type").eq("fiction").choose(
field("plot_summary"),
field("technical_summary")
),
})
```
###### boost
The `boost` operator multiplies the scoring expression by the provided `boost` value if the `condition` is true.
Otherwise, the scoring expression is unchanged (multiplied by 1).
```python Python
select(
summary_distance=fn.vector_distance("summary_embedding", [2.3] * 16)
).sort(
field("summary_distance").boost(field("summary").match_all("deep learning"), 1.5),
asc=False
).limit(10)
### this boost expression is equivalent to
### field("summary_distance") * (field("summary").match_all("deep learning").choose(1.5, 1.0)),
```
```js Javascript
select({
summary_distance: fn.vectorDistance("summary_embedding", Array(16).fill(2.3)),
}).sort(
field("summary_distance").boost(field("summary").matchAll("deep learning"), 1.5),
false
).limit(10)
// this boost expression is equivalent to
// field("summary_distance").mul(field("summary").matchAll("deep learning").choose(1.5, 1.0)),
```
###### coalesce
The `coalesce` operator replaces `null` values with a provided value.
```python Python
select(importance=field("nullable_importance").coalesce(1.0))
```
```js Javascript
select({
importance: field("nullable_importance").coalesce(1.0)
})
```
##### Comparison operators
Comparison operators provide various logical, numerical and string functions that evaluate to true or false.
###### eq
The `eq` operator can be used to match documents that have a field with a specific value.
```python Python
.filter(
field("published_year") == 1997
)
### or
.filter(
field("published_year").eq(1997)
)
```
```js Javascript
.filter(field("published_year").eq(1997))
```
###### ne
The `ne` operator can be used to match documents that have a field with a value that is not equal to a specific value.
```python Python
.filter(
field("published_year") != 1997
)
### or
.filter(
field("published_year").ne(1997)
)
```
```js Javascript
.filter(field("published_year").ne(1997))
```
###### is_null
The `is_null` operator can be used to match documents that have a field with a value that is `null`.
```python Python
.filter(
field("title").is_null()
)
```
```js Javascript
.filter(field("title").isNull())
```
###### is_not_null
The `is_not_null` operator can be used to match documents that have a field with a value that is not `null`.
```python Python
.filter(
field("title").is_not_null()
)
```
```js Javascript
.filter(field("title").isNotNull())
```
###### gt
The `gt` operator can be used to match documents that have a field with a value greater than a specific value.
For strings, it uses lexicographic order.
```python Python
.filter(
field("published_year") > 1997
)
### or
.filter(
field("published_year").gt(1997)
)
```
```js Javascript
.filter(field("published_year").gt(1997))
```
###### gte
The `gte` operator can be used to match documents that have a field with a value greater than or equal to a specific value.
For strings, it uses lexicographic order.
```python Python
.filter(
field("published_year") >= 1997
)
### or
.filter(
field("published_year").gte(1997)
)
```
```js Javascript
.filter(field("published_year").gte(1997))
```
###### lt
The `lt` operator can be used to match documents that have a field with a value less than a specific value.
For strings, it uses lexicographic order.
```python Python
.filter(
field("published_year") < 1997
)
### or
.filter(
field("published_year").lt(1997)
)
```
```js Javascript
.filter(field("published_year").lt(1997))
```
###### lte
The `lte` operator can be used to match documents that have a field with a value less than or equal to a specific value.
For strings, it uses lexicographic order.
```python Python
.filter(
field("published_year") <= 1997
)
### or
.filter(
field("published_year").lte(1997)
)
```
```js Javascript
.filter(field("published_year").lte(1997))
```
###### starts_with
The `starts_with` operator can be used on string fields to match documents that start with a given prefix. This is especially
useful in multi-tenant applications where document IDs can be structured as `{tenant_id}/{document_id}` and `starts_with` can
then be used to scope the query to a specific tenant. Also supports list-of-string fields for prefix filtering on array elements (e.g. `field("tags").starts_with("fiction")`).
```python Python
.filter(
field("_id").starts_with("tenant_123/")
)
```
```js Javascript
.filter(field("_id").startsWith("tenant_123/"))
```
###### contains
The `contains` operator can be used on both text fields and list fields to match documents that include a specific value. For text fields, it matches documents that include a specific substring (case-sensitive). For list fields, it matches documents where the field of type list contains the specified value.
* [**Text fields**](/collections/create#text): Matches documents that include a specific substring. It is **case-sensitive** and avoids the text processing pipeline (tokenization and stemming) used by the [`match()`](#keyword-search) function. This makes it particularly useful when you need exact substring matching or want to provide your own pre-processed tokens. Unlike `match()`, the `contains` operator can be used without requiring a keyword index.
* [**List fields**](/collections/create#list): Matches documents where the list field contains the specified value. The value can be a literal or a field reference. You can also use a list of strings with a keyword index if you want to provide your own tokens instead of using the text processing pipeline.
```python Python
### String contains
.filter(
field("title").contains("Catcher")
)
### List contains
.filter(
# Tags is a text list field: ["novel", "fiction", "science-fiction"]
field("tags").contains("novel")
)
### List contains combined with a field reference
.filter(
field("codes").contains(field("slug"))
)
```
```typescript Javascript
// String contains
.filter(field("title").contains("Catcher"))
// List contains
.filter(field("tags").contains("novel"))
// List contains combined with a field reference
.filter(field("codes").contains(field("slug")))
```
The `contains` operator works exactly the same as the `in` operator, but with reversed operands: `x CONTAINS y` is equivalent to `y IN x`. Both operators are provided for convenience and to make queries more readable.
###### in
The `in` (or `in_` in Python) operator checks if a field value is present in a list of values, string literal or another field. It can be used in several ways:
* **Field in list**: Checks if a field value is present in a list of literal values.
* **Field in string**: Checks if a string field is a substring of another string. Unlike the [`match()`](#keyword-search), this avoids the text processing pipeline (tokenization and stemming) and performs exact substring matching.
* **Field in field**: Checks if a field value is present in another field.
```python Python
### Field in list of literals
.filter(
field("published_year").in_([1999, 1988, 1997])
)
### Field in string
.filter(
field("slug").in_("harry-potter lord-of-the-rings")
)
### Field in another field (list)
.filter(
field("_id").in_(field("tags"))
)
```
```typescript Javascript
// Field in list of literals
.filter(field("published_year").in([1999, 1988, 1997]))
// Field in string
.filter(field("slug").in("harry-potter lord-of-the-rings"))
// Field in another field (list)
.filter(field("_id").in(field("tags")))
```
The `in` operator works exactly the same as the `contains` operator, but with reversed operands: `y IN x` is equivalent to `x CONTAINS y`. Both operators are provided for convenience and to make queries more readable.
###### match_all
The `match_all` operator returns `true` if all terms in the query are present in the field with a keyword index.
```python Python
.filter(
field("summary").match_all("love marriage england")
)
### you can also pass a list of strings:
.filter(
field("summary").match_all(["love", "marriage", "england"])
)
```
```js Javascript
.filter(field("summary").matchAll("love marriage england"))
// you can also pass an array of strings:
.filter(field("summary").matchAll(["love", "marriage", "england"]))
```
When using a `match_all` operator against a text field, it must be used in conjunction with a [**keyword index**](/collections/create#keyword-index) defined in your collection schema.
###### match_any
The `match_any` operator returns `true` if any term in the query is present in the field with a keyword index.
```python Python
.filter(
field("summary").match_any("love ring")
)
### you can also pass a list of strings:
.filter(
field("summary").match_any(["love", "ring"])
)
```
```js Javascript
.filter(field("summary").matchAny("love ring"))
// you can also pass an array of strings:
.filter(field("summary").matchAny(["love", "ring"]))
```
When using a `match_any` operator against a text field, it must be used in conjunction with a [**keyword index**](/collections/create#keyword-index) defined in your collection schema.
###### regexp_match
The `regexp_match` operator returns `true` if the field value matches the regular expression. Internally, this uses Rust's
[`regex`](https://docs.rs/regex) crate to evaluate the regular expression.
```python Python
.filter(
field("summary").regexp_match("^love")
)
### Optionally, you can pass flags to the regular expression
.filter(
field("summary").regexp_match("^love", "i")
)
```
```js Javascript
.filter(field("summary").regexpMatch("^love"))
// Optionally, you can pass flags to the regular expression
.filter(field("summary").regexpMatch("^love", "i"))
```
##### Mathematical operators
Mathematical operators perform computations on numbers.
###### add
The `add` operator can be used to add two numbers.
```python Python
.filter(
field("published_year") + 1997
)
### or
.filter(
field("published_year").add(1997)
)
```
```js Javascript
.filter(field("published_year").add(1997))
```
###### sub
The `sub` operator can be used to subtract two numbers.
```python Python
.filter(
field("published_year") - 1997
)
### or
.filter(
field("published_year").sub(1997)
)
```
```js Javascript
.filter(field("published_year").sub(1997))
```
###### mul
The `mul` operator can be used to multiply two numbers.
```python Python
.filter(
field("published_year") * 1997
)
### or
.filter(
field("published_year").mul(1997)
)
```
```js Javascript
.filter(field("published_year").mul(1997))
```
###### div
The `div` operator can be used to divide two numbers.
```python Python
.filter(
field("published_year") / 1997
)
### or
.filter(
field("published_year").div(1997)
)
```
```js Javascript
.filter(field("published_year").div(1997))
```
###### abs
The `abs` operator returns the absolute value of a number, which is useful for calculating distances or differences.
```python Python
from topk_sdk.query import abs
### Find books published closest to 1990
select(
delta=abs(field("published_year").sub(1990))
)
```
```js Javascript
import { abs } from "topk-js/query";
// Find books published closest to 1990
select({
delta: abs(field("published_year").sub(1990))
})
```
###### min
The `min` operator returns the smaller of two values, commonly used for clamping or setting upper bounds. It can work with both scalar values and other fields or expressions.
For strings, it uses lexicographic order.
```python Python
from topk_sdk.query import min
### Clamp BM25 scores to a maximum of 2.0
select(
clamped_score=min(field("bm25_score"), 2.0)
)
### Take the lower of critic score vs user rating
select(
conservative_score=min(field("critic_score"), field("user_rating"))
)
```
```js Javascript
import { min } from "topk-js/query";
// Clamp BM25 scores to a maximum of 2.0
select({
clamped_score: min(field("bm25_score"), 2.0)
})
// Take the lower of critic score vs user rating
select({
conservative_score: min(field("critic_score"), field("user_rating"))
})
```
###### max
The `max` operator returns the larger of two values, commonly used for clamping or setting lower bounds. It can work with both scalar values and other fields or expressions.
For strings, it uses lexicographic order.
```python Python
from topk_sdk.query import max
### Ensure minimum relevance score of 1.5
select(
boosted_score=max(field("relevance_score"), 1.5)
)
### Take the higher of critic score vs user rating
select(
best_score=max(field("critic_score"), field("user_rating"))
)
```
```js Javascript
import { max } from "topk-js/query";
// Ensure minimum relevance score of 1.5
select({
boosted_score: max(field("relevance_score"), 1.5)
})
// Take the higher of critic score vs user rating
select({
best_score: max(field("critic_score"), field("user_rating"))
})
```
###### ln
The `ln` operator calculates the natural logarithm, useful for logarithmic scaling and dampening large values.
```python Python
### Apply logarithmic dampening to scores
select(
log_score=(field("raw_score") + 1).ln()
)
```
```js Javascript
// Apply logarithmic dampening to scores
select({
log_score: field("raw_score").add(1).ln()
})
```
###### exp
The `exp` operator calculates the exponential function (e^x), useful for exponential scaling and boosting.
```python Python
### Apply exponential boosting to BM25 scores
select(
boosted_score=(field("bm25_score") * 1.5).exp()
)
```
```js Javascript
// Apply exponential boosting to BM25 scores
select({
boosted_score: field("bm25_score").mul(1.5).exp()
})
```
###### sqrt
The `sqrt` operator calculates the square root, useful for dampening values and creating non-linear transformations.
```python Python
### Dampen large distance values
select(
dampened_distance=field("vector_distance").sqrt()
)
```
```js Javascript
// Dampen large distance values
select({
dampened_distance: field("vector_distance").sqrt()
})
```
###### square
The `square` operator multiplies a number by itself (x²), useful for amplifying differences and creating quadratic transformations.
```python Python
### Create quadratic penalty for age differences
select(
age_penalty=(field("user_age") - 50).square()
)
```
```js Javascript
// Create quadratic penalty for age differences
select({
age_penalty: field("user_age").sub(50).square()
})
```
#### Collection
All queries **must** have a collection stage. Currently, we support `topk()`, `count()` and `group_by()` collectors.
##### topk
Use the `topk()` function to return the top `k` results. The `topk()` function accepts the following parameters:
The logical expression to sort the results by.
The number of results to return.
Whether to sort the results in ascending order.
To get the top 10 results with the highest `title_similarity`, you can use the following query:
```python Python
.sort(field("title_similarity"), asc=False).limit(10)
```
```typescript Javascript
.sort(field("title_similarity"), false).limit(10)
```
```sql SQL
ORDER BY title_similarity DESC
LIMIT 10
```
The `topk()` stage is equivalent to applying `sort(expr, asc)` followed by `limit(k)`. It is a convenience shorthand for the common pattern of ordering results by a scoring expression and returning the top `k`.
##### limit
Use the `.limit(k)` stage to return at most `k` results. Can be used with or without `topk()`.
```python Python
client.collection("books").query(
select("title", "author"),
filter=field("year") >= 2000,
).limit(50)
```
```js Javascript
await client.collection("books").query(
select({ title: field("title"), author: field("author") }),
{ filter: field("year").gte(2000) }
).limit(50);
```
```sql SQL
SELECT title, author
FROM books
WHERE published_year >= 2000
LIMIT 50;
```
##### offset
Use the `.offset(n)` stage to skip the first `n` results.
```python Python
client.collection("books").query(
select("title", "author"),
filter=field("year") >= 2000,
).limit(50).offset(100)
```
```js Javascript
await client.collection("books").query(
select({ title: field("title"), author: field("author") }),
{ filter: field("year").gte(2000) }
).limit(50).offset(100);
```
```sql SQL
SELECT title, author
FROM books
WHERE published_year >= 2000
LIMIT 50 OFFSET 100;
-- OFFSET requires a LIMIT clause
```
##### sort
Use the `.sort(expr, asc)` stage to sort results by an expression. Use `asc=True` for ascending order, `asc=False` for descending order.
```python Python
client.collection("books").query(
select("title", "author", "year"),
filter=field("author") == "George Orwell",
).sort(field("year"), asc=True)
```
```js Javascript
await client.collection("books").query(
select({ title: field("title"), author: field("author"), year: field("year") }),
{ filter: field("author").eq("George Orwell") }
).sort(field("year"), true);
```
```sql SQL
SELECT title, author, published_year AS year
FROM books
WHERE author = 'George Orwell'
ORDER BY published_year ASC
LIMIT 100;
```
To sort by more than one key, pass a list of sort expressions instead of a single expression. They are applied in order, each breaking ties left by the previous ones:
```python Python
.sort([(field("year"), "asc"), (field("rating"), "desc")]).limit(100)
```
```js Javascript
.sort([
{ expr: field("year"), order: "asc" },
{ expr: field("rating"), order: "desc" },
]).limit(100)
```
```sql SQL
ORDER BY published_year ASC, rating DESC
LIMIT 100
```
##### count
Use the `count()` function to get the total number of documents matching the query. If there are no filters then `count()` will return the total number of documents in the collection.
```python Python
### Count the total number of documents in the collection
.count()
```
```js Javascript
// Count the total number of documents in the collection
.count()
```
```sql SQL
-- Count all documents
SELECT COUNT(*) FROM books;
-- Count with a filter
SELECT COUNT(*) FROM books WHERE published_year > 2000;
```
##### group_by
Use the `group_by(keys, aggs)` stage to group documents by one or more key expressions and compute aggregations for each group. The query returns one row per group, containing the group keys and the aggregated values.
```python Python
from topk_sdk.query import group_by, field, agg
client.collection("books").query(
group_by(
{"is_classic": field("published_year") < 1940},
{"count": agg.count()},
)
)
```
```js Javascript
import { groupBy, field, agg } from "topk-js/query";
await client.collection("books").query(
groupBy(
{ is_classic: field("published_year").lt(1940) },
{ count: agg.count() }
)
);
```
```sql SQL
SELECT published_year < 1940 AS is_classic, COUNT(*) AS count
FROM books
GROUP BY is_classic;
```
The following aggregate functions are supported, exposed via the `agg` module in the SDKs (`topk_sdk.query.agg` in Python, `agg` from `topk-js/query` in JavaScript) and as standard `COUNT`/`SUM`/`MIN`/`MAX`/`AVG` functions in SQL:
| Aggregate | Description |
| --------- | ----------- |
| `count()` | Number of documents in the group |
| `count(field)` | Number of non-null values of `field` in the group |
| `sum(field)` | Sum of `field` in the group |
| `min(field)` | Minimum value of `field` in the group |
| `max(field)` | Maximum value of `field` in the group |
| `avg(field)` | Average value of `field` in the group |
Multiple aggregations can be computed in a single `group_by()`:
```python Python
client.collection("books").query(
group_by(
{"is_classic": field("published_year") < 1940},
{
"count": agg.count(),
"rated": agg.count("rating"),
"total_pages": agg.sum("pages"),
"oldest": agg.min("published_year"),
"newest": agg.max("published_year"),
"avg_year": agg.avg("published_year"),
},
)
)
```
```js Javascript
await client.collection("books").query(
groupBy(
{ is_classic: field("published_year").lt(1940) },
{
count: agg.count(),
rated: agg.count("rating"),
total_pages: agg.sum("pages"),
oldest: agg.min("published_year"),
newest: agg.max("published_year"),
avg_year: agg.avg("published_year"),
}
)
);
```
```sql SQL
SELECT published_year < 1940 AS is_classic,
COUNT(*) AS count,
COUNT(rating) AS rated,
SUM(pages) AS total_pages,
MIN(published_year) AS oldest,
MAX(published_year) AS newest,
AVG(published_year) AS avg_year
FROM books
GROUP BY is_classic;
```
The `group_by()` stage can be combined with preceding `filter()` and `select()` stages — group keys and aggregations can reference computed columns projected by an earlier `select()`:
```python Python
client.collection("books").query(
filter(field("published_year") >= 1940).group_by(
{"recent": field("published_year") > 1980},
{"count": agg.count()},
)
)
```
```js Javascript
await client.collection("books").query(
filter(field("published_year").gte(1940)).groupBy(
{ recent: field("published_year").gt(1980) },
{ count: agg.count() }
)
);
```
```sql SQL
SELECT published_year > 1980 AS recent, COUNT(*) AS count
FROM books
WHERE published_year >= 1940
GROUP BY recent;
-- Use HAVING to filter on the grouped output
SELECT published_year > 1980 AS recent, COUNT(*) AS count
FROM books
WHERE published_year >= 1940
GROUP BY recent
HAVING count > 2;
```
When writing queries, remember that they all require the `topk`, `count` or `group_by` function at the end.
#### Query options
The `query()` method accepts a `consistency` parameter to control read consistency: `indexed`, `balanced` (default), or `strong`. See the [consistency](/concepts#read-consistency) concept for details.
#### LSN-based Consistency
TopK supports **LSN (Log Sequence Number)** based consistency for ensuring read-after-write consistency. When you perform a write operation (like `upsert`), you receive an LSN as a **string** that represents the sequence number of that write in the system's log.
You can use this LSN in subsequent queries to ensure that the query only returns results that are at least as recent as that write operation.
##### How it works
1. **Write operation**: When you call `lsn = client.collection().upsert()`, you receive an LSN
2. **Query with LSN**: Pass that LSN to `client.collection().query(..., lsn=lsn)`
3. **Consistency guarantee**: If the write is not yet available in the read path, the query will be rejected and the client will automatically retry
This approach ensures that your queries always see the results of your recent writes, providing strong consistency guarantees when needed.
```python Python
### Upsert a document and get the LSN
lsn = client.collection("books").upsert([
{"_id": "1984", "title": "1984", "author": "George Orwell", "year": 1949}
])
### Query with LSN to ensure consistency (optionally use consistency="strong")
results = client.collection("books").query(
select("title", "author", "year")
.filter(field("author") == "George Orwell")
.sort(field("year"), asc=False).limit(10),
lsn=lsn,
consistency="strong"
)
```
```js Javascript
// Upsert a document and get the LSN
const lsn = await client.collection("books").upsert([
{ _id: "1984", title: "1984", author: "George Orwell", "year": 1949 }
]);
// Query with LSN to ensure consistency (optionally use consistency: "strong")
const results = await client.collection("books").query(
select({ title: field("title"), author: field("author"), year: field("year") })
.filter(field("author").eq("George Orwell"))
.sort(field("title"), false).limit(10),
{ lsn: lsn, consistency: "strong" }
)
```
Using LSN-based consistency may increase query latency as the system needs to verify that the specified LSN has been processed before returning results.
### Get
URL: https://docs.topk.io/collections/get
TopK collections store documents as key-value pairs. [`get()`](../sdk/topk-py#get) provides direct key-based lookup, similar to a key-value store.
This operation is optimized for **high throughput** and **low latency**.
```python Python
docs = client.collection("books").get(["lotr", "moby"])
```
```typescript Javascript
const docs = await client.collection("books").get(["lotr", "moby"]);
```
The result is a key-value mapping: each key is a document ID and each value is a full document as it was upserted into the collection.
```python Python
### Example response
{
"lotr": {
"_id": "lotr",
"title": "The Lord of the Rings",
"author": "J.R.R. Tolkien",
"published_year": 1954
},
"moby": {
"_id": "moby",
"title": "Moby Dick",
"author": "Herman Melville",
"published_year": 1851
}
}
```
```typescript Javascript
// Example response
{
lotr: {
_id: "lotr",
title: "The Lord of the Rings",
author: "J.R.R. Tolkien",
published_year: 1954
},
moby: {
_id: "moby",
title: "Moby Dick",
author: "Herman Melville",
published_year: 1851
}
}
```
If a document with a given ID does not exist in the collection, it is simply
omitted from the results - no error is thrown.
## Management API
### Collections
URL: https://docs.topk.io/collections/manage
Collections organize your documents, define their schema, and enable fast vector search, filtering, keyword search, semantic search, and multi-vector search.
#### Create
In order to create a collection, call the [`create()`](/sdk/topk-py#create) method on the [`client.collections()`](/sdk/topk-py#collectionsclient) object:
```python Python
from topk_sdk.schema import int, text, semantic_index
client.collections().create(
"books",
schema={
"title": text().required().index(semantic_index()),
"published_year": int().required(),
},
)
```
```typescript Javascript
import { int, text, semanticIndex } from "topk-js/schema";
await client.collections().create("books", {
title: text().required().index(semanticIndex()),
published_year: int().required(),
});
```
```sql SQL
CREATE TABLE books (
title TEXT NOT NULL INDEX semantic_index(),
published_year INTEGER NOT NULL
);
```
Field names starting with `_` are reserved for internal use.
##### Schema
###### Opt-in schema
TopK is schemaless-by-default. Fields without types can store any value. When types are specified, data is validated during upsert.
Indexed fields require **explicit types**.
###### Field types
| Type | Use case |
|------|----------|
| [`text()`](/sdk/topk-py/schema#text) | Strings, descriptions, content, IDs |
| [`bytes()`](/sdk/topk-py/schema#bytes) | Binary data, images, files |
| [`int()`](/sdk/topk-py/schema#int) | Integers, counts, IDs |
| [`float()`](/sdk/topk-py/schema#float) | Decimal numbers, prices |
| [`bool()`](/sdk/topk-py/schema#bool) | true/false values |
| [`timestamp()`](/sdk/topk-py/schema#timestamp) | Timestamps, stored as milliseconds since UNIX epoch |
| [`list(value_type)`](/sdk/topk-py/schema#list) | Arrays of text, integer, or float elements |
| [`struct(fields)`](/sdk/topk-py/schema#struct) | Nested objects with named fields |
| [`f8_vector(dim)`](/sdk/topk-py/schema#f8_vector) | 8-bit float embeddings |
| [`f16_vector(dim)`](/sdk/topk-py/schema#f16_vector) | 16-bit float embeddings |
| [`f32_vector(dim)`](/sdk/topk-py/schema#f32_vector) | Dense embeddings (most common) |
| [`u8_vector(dim)`](/sdk/topk-py/schema#u8_vector) | Quantized embeddings |
| [`i8_vector(dim)`](/sdk/topk-py/schema#i8_vector) | Signed quantized embeddings |
| [`binary_vector(dim)`](/sdk/topk-py/schema#binary_vector) | Binary embeddings |
| [`f32_sparse_vector()`](/sdk/topk-py/schema#f32_sparse_vector) | Sparse embeddings |
| [`u8_sparse_vector()`](/sdk/topk-py/schema#u8_sparse_vector) | Quantized sparse embeddings |
| [`matrix(dim, value_type)`](/sdk/topk-py/schema#matrix) | Multi-vector embeddings |
Nested objects are automatically treated as structs — no need to use `struct()` explicitly.
```python Python
from topk_sdk.schema import struct, text
schema = {
"meta": {
"name": text(),
"source": {
"url": text(),
},
},
# Implicit struct, equivalent to:
# "meta": struct({
# "name": text(),
# "source": struct({
# "url": text(),
# }),
# })
}
```
```typescript Javascript
import { struct, text } from "topk-js/schema";
const schema = {
meta: {
name: text(),
source: {
url: text(),
},
},
// Implicit struct, equivalent to:
// meta: struct({
// name: text(),
// source: struct({
// url: text(),
// }),
// })
};
```
###### Required fields
Fields are optional by default.
Add [`required()`](/sdk/topk-py/schema#required) to make them mandatory—required fields must be present in every document during upsert. Documents missing a required field are rejected with a validation error.
```python Python
from topk_sdk.schema import int, text
schema = {
"name": text().required(), # Must be present in all documents
"price": int(), # Can be omitted (null)
}
```
```typescript Javascript
import { int, text } from "topk-js/schema";
const schema = {
name: text().required(), // Must be present in all documents
price: int(), // Can be omitted (null)
};
```
```sql SQL
CREATE TABLE books (
name TEXT NOT NULL, -- NOT NULL marks the field as required
price INTEGER -- nullable by default (can be omitted)
);
```
##### Indexes
Only indexed fields can be searched. Non-indexed fields support exact-match filters only.
###### Vector Index
Used for vector search. Supports dimensions up to 2^14. Enabled by [`vector_index()`](/sdk/topk-py/schema#vector_index).
```python Python
from topk_sdk.schema import f32_vector, vector_index
schema = {
"embedding": f32_vector(dimension=1536).index(vector_index(metric="cosine")),
}
```
```typescript Javascript
import { f32Vector, vectorIndex } from "topk-js/schema";
const schema = {
embedding: f32Vector({ dimension: 1536 }).index(vectorIndex({ metric: "cosine" })),
};
```
```sql SQL
CREATE TABLE books (
embedding f32_vector(1536) INDEX vector_index(metric = 'cosine')
);
```
**Similarity metrics compatibility:**
| Vector Type | `cosine` | `euclidean` | `dot_product` | `hamming` |
|-----------------------|:--------:|:-----------:|:-------------:|:---------:|
| `f8_vector` | ✅ | ✅ | ✅ | — |
| `f16_vector` | ✅ | ✅ | ✅ | — |
| `f32_vector` | ✅ | ✅ | ✅ | — |
| `u8_vector` | ✅ | ✅ | ✅ | — |
| `i8_vector` | ✅ | ✅ | ✅ | — |
| `binary_vector` | — | — | — | ✅ |
| `f32_sparse_vector` | — | — | ✅ | — |
| `u8_sparse_vector` | — | — | ✅ | — |
###### Multi-Vector Index
Enables multi-vector search on [`matrix()`](/sdk/topk-py/schema#matrix) fields using the maxsim metric for late-interaction scoring. Enabled by [`multi_vector_index()`](/sdk/topk-py/schema#multi_vector_index). See [multi-vector search](/guides/multi-vector-search) for more information.
```python Python
from topk_sdk.schema import matrix, multi_vector_index
schema = {
"token_embeddings": matrix(
dimension=1536,
value_type="f32"
).index(
multi_vector_index(metric="maxsim")
),
}
```
```typescript Javascript
import { matrix, multiVectorIndex } from "topk-js/schema";
const schema = {
token_embeddings: matrix({
dimension: 1536,
valueType: "f32",
}).index(
multiVectorIndex({ metric: "maxsim" })
),
};
```
```sql SQL
CREATE TABLE passages (
token_embeddings f16_matrix(128) INDEX multi_vector_index(metric = 'maxsim')
);
```
###### Keyword Index
Traditional text search with BM25 relevance scoring. Fast keyword matching with no embedding overhead. Enabled by [`keyword_index()`](/sdk/topk-py/schema#keyword_index).
```python Python
from topk_sdk.schema import keyword_index, text
schema = {
"title": text().index(keyword_index()),
}
```
```typescript Javascript
import { keywordIndex, text } from "topk-js/schema";
const schema = {
title: text().index(keywordIndex()),
};
```
```sql SQL
CREATE TABLE books (
title TEXT INDEX keyword_index()
);
```
###### Semantic Index
Convenience method for automatic embeddings. Enabled by [`semantic_index()`](/sdk/topk-py/schema#semantic_index).
```python Python
from topk_sdk.schema import semantic_index, text
schema = {
"title": text().index(semantic_index()),
}
```
```typescript Javascript
import { semanticIndex, text } from "topk-js/schema";
const schema = {
title: text().index(semanticIndex()),
};
```
```sql SQL
CREATE TABLE books (
title TEXT INDEX semantic_index()
);
```
See [semantic_index()](../sdk/topk-py/schema#semantic-index) for details.
###### NGram Index
Accelerates substring and regular expression filters such as [`contains`](/collections/query#contains) and [`regexp_match`](/collections/query#regexp_match) on text fields. Enabled by [`ngram_index()`](/sdk/topk-py/schema#ngram_index).
```python Python
from topk_sdk.schema import ngram_index, text
schema = {
"title": text().index(ngram_index()),
}
```
```typescript Javascript
import { ngramIndex, text } from "topk-js/schema";
const schema = {
title: text().index(ngramIndex()),
};
```
```sql SQL
CREATE TABLE books (
title TEXT INDEX ngram_index()
);
```
#### List
You can list all collections in a project by calling [`client.collections().list()`](/sdk/topk-py#list):
```python Python
collections = client.collections().list()
```
```typescript Javascript
const collections = await client.collections().list();
```
```sql SQL
SELECT table_name FROM information_schema.tables;
```
The `list()` function returns a list of `Collection` objects:
```python Python
for collection in collections:
print(f"Collection name: {collection.name}")
print(f"Organization ID: {collection.org_id}")
print(f"Project ID: {collection.project_id}")
print(f"Region: {collection.region}")
print(f"Schema: {collection.schema}")
```
```js Javascript
for (const collection of collections) {
console.log(`Collection name: ${collection.name}`);
console.log(`Organization ID: ${collection.orgId}`);
console.log(`Project ID: ${collection.projectId}`);
console.log(`Region: ${collection.region}`);
console.log(`Schema: ${collection.schema}`);
}
```
#### Get
You can get a specific collection in a project by calling [`client.collections().get(name)`](/sdk/topk-py#get-3):
```python Python
collection = client.collections().get("books")
```
```typescript Javascript
const collection = await client.collections().get("books")
```
The `get()` function takes the name of a collection and returns a single `Collection` object.
```python Python
print(f"Collection name: {collection.name}")
print(f"Organization ID: {collection.org_id}")
print(f"Project ID: {collection.project_id}")
print(f"Region: {collection.region}")
print(f"Schema: {collection.schema}")
```
```js Javascript
console.log(`Collection name: ${collection.name}`);
console.log(`Organization ID: ${collection.orgId}`);
console.log(`Project ID: ${collection.projectId}`);
console.log(`Region: ${collection.region}`);
console.log(`Schema: ${collection.schema}`);
```
#### Delete
Once you decide that you no longer need a collection or that you want to start over, you can delete it.
Deleting a collection will remove all the documents and indexes associated with it.
To delete a collection, call the [`client.collections().delete(name)`](/sdk/topk-py#delete-3) method:
```python Python
client.collections().delete("my-collection")
```
```typescript JavaScript
await client.collections().delete("my-collection")
```
```sql SQL
DROP TABLE "my-collection";
-- Use IF EXISTS to suppress the error if the collection does not exist:
DROP TABLE IF EXISTS "my-collection";
```
If your collection is too large it can take a moment to delete it. You can check the status of the deletion by listing the collections again.
This operation is irreversible and will permanently delete all data in the collection.
## Guides
### Semantic search
URL: https://docs.topk.io/guides/semantic-search
**Prerequisites**
- TopK account ([Sign up here](https://console.topk.io/login))
- TopK API key ([Get an API key here](https://console.topk.io/api-key))
TopK enables you to add state-of-the-art semantic search to your documents with just a few lines of code.
With TopK's semantic search, there is no embedding pipeline to build, no vector store to operate, and no reranking service to maintain. It's as simple as adding [`semantic_index()`](/sdk/topk-py/schema#semantic_index) to your collection schema and querying with [`fn.semantic_similarity()`](/sdk/topk-py/query#semantic_similarity):
```python Python
from topk_sdk.schema import text, semantic_index
from topk_sdk.query import select, field, fn
client.collections().create("books", schema={
"title": text().required().index(semantic_index()),
})
docs = client.collection("books").query(
select("title", title_similarity=fn.semantic_similarity("title", "classic novel"))
.sort(field("title_similarity"), asc=False)
.limit(10)
)
```
```typescript Javascript
import { text, semanticIndex } from "topk-js/schema";
import { select, field, fn } from "topk-js/query";
await client.collections().create("books", {
title: text().required().index(semanticIndex()),
});
const docs = await client.collection("books").query(
select({ title: field("title"), title_similarity: fn.semanticSimilarity("title", "classic novel") })
.sort(field("title_similarity"), false)
.limit(10)
);
```
```sql SQL
CREATE TABLE books (
title TEXT NOT NULL INDEX semantic_index()
);
INSERT INTO books (_id, title)
VALUES
('gatsby', 'The Great Gatsby'),
('1984', '1984'),
('catcher', 'The Catcher in the Rye');
SELECT title, semantic_similarity(title, 'classic novel') AS title_similarity
FROM books
ORDER BY title_similarity DESC
LIMIT 10;
```
Under the hood, `semantic_index()` is powered by [Iso-ModernColBERT](https://huggingface.co/topk-io/Iso-ModernColBERT), TopK's own multi-vector embedding model, combined with [Sparse Multi-Vector Encoding (SMVE)](https://www.topk.io/blog/20260311-smve-multi-vector-retrieval) for scalable retrieval and quantized *MaxSim* reranking.
**Why multi-vector?** Single-vector (dense) embeddings compress an entire document into one point in high-dimensional space.
Multi-vector models like [Iso-ModernColBERT](https://huggingface.co/topk-io/Iso-ModernColBERT) keep one embedding per token, enabling token-level matching via MaxSim scoring. This consistently outperforms dense models on out-of-domain content, long documents, specific clauses, tables, and structured data.
Read [High-Quality Search, Out of the Box](https://www.topk.io/blog/20260611-semantic-index-multi-vector-retrieval) for benchmarks and a deep-dive into the architecture.
#### How to perform a semantic search
In the following example, we'll:
Create a collection configured for semantic search.Insert documents into the collection.Retrieve documents using a free-form text query.
##### Define a collection schema
Semantic search is enabled by adding a [`semantic_index()`](/sdk/topk-py/schema#semantic_index) to a [`text()`](/sdk/topk-py/schema#text) field in the collection schema:
```python Python
from topk_sdk.schema import text, semantic_index
client.collections().create(
"books",
schema={
"title": text().required().index(semantic_index()),
},
)
```
```typescript Javascript
import { text, semanticIndex } from "topk-js/schema";
await client.collections().create("books", {
title: text().required().index(semanticIndex()),
});
```
```sql SQL
CREATE TABLE books (
title TEXT NOT NULL INDEX semantic_index()
);
```
This configuration automatically generates multi-vector embeddings for the field and enables keyword search. Documents are indexed with sub-second lag — they are searchable as soon as they are written.
If you want to use your own embeddings instead of TopK's built-in `semantic_index()`, see [Vector Search](/guides/vector-search) guide.
##### Add documents to the collection
Let's add some documents to the collection:
```python Python
client.collection("books").upsert(
[
{"_id": "gatsby", "title": "The Great Gatsby"},
{"_id": "1984", "title": "1984"},
{"_id": "catcher", "title": "The Catcher in the Rye"},
],
)
```
```typescript Javascript
await client.collection("books").upsert([
{ _id: "gatsby", title: "The Great Gatsby" },
{ _id: "1984", title: "1984" },
{ _id: "catcher", title: "The Catcher in the Rye" },
]);
```
```sql SQL
INSERT INTO books (_id, title)
VALUES
('gatsby', 'The Great Gatsby'),
('1984', '1984'),
('catcher', 'The Catcher in the Rye');
```
##### Run a semantic query
To search for documents based on semantic similarity, use the [`fn.semantic_similarity()`](/sdk/topk-py/query#semantic_similarity) function:
```python Python
from topk_sdk.query import select, field, fn
docs = client.collection("books").query(
select(
"title",
title_similarity=fn.semantic_similarity("title", "classic American novel"),
)
.sort(field("title_similarity"), asc=False)
.limit(10)
)
### Example results:
[
{
"_id": "2",
"title": "The Catcher in the Rye",
"title_similarity": 0.9497610926628113
},
{
"_id": "1",
"title": "The Great Gatsby",
"title_similarity": 0.9480283856391907
}
]
```
```typescript Javascript
import { select, field, fn } from "topk-js/query";
const docs = await client.collection("books").query(
select({
title: field("title"),
title_similarity: fn.semanticSimilarity("title", "classic American novel"),
})
.sort(field("title_similarity"), false)
.limit(10)
);
// Example results:
[
{
_id: '2',
title: 'The Catcher in the Rye',
title_similarity: 0.9497610926628113
},
{
_id: '1',
title: 'The Great Gatsby',
title_similarity: 0.9480283856391907
}
]
```
```sql SQL
SELECT
title,
semantic_similarity(title, 'classic American novel') AS title_similarity
FROM books
ORDER BY title_similarity DESC
LIMIT 10;
```
Let's break down the example above:
1. The `semantic_similarity()` function encodes the query `"classic American novel"` into multi-vector token embeddings using Iso-ModernColBERT and scores each document via quantized *MaxSim* — comparing every query token against every document token to find the best alignment.
2. Candidate retrieval is accelerated by [SMVE](https://www.topk.io/blog/20260311-smve-multi-vector-retrieval), which uses fast sparse approximations to identify a small set of candidates before the full MaxSim pass.
3. The results are ranked by their MaxSim score and the top 10 most relevant documents are returned.
This works **out of the box**—no embedding pipeline, no vector store, no reranking service to manage.
#### Combining semantic and keyword search
For certain use cases, you might want to use a combination of **keyword search** and **semantic search**:
```python Python
from topk_sdk.query import select, field, fn, match
docs = client.collection("books").query(
select(
"title",
title_similarity=fn.semantic_similarity("title", "catcher"),
text_score=fn.bm25_score(), # Keyword-based relevance
)
.filter(match("classic")) # Ensure the book contains the keyword "classic" in any of the text-indexed fields
.sort(field("title_similarity") * 0.7 + field("text_score") * 0.3, asc=False) # Add 70% weight to semantic similarity and 30% weight to keyword relevance
.limit(10)
)
```
```typescript Javascript
import { select, field, fn, match } from "topk-js/query";
const docs = await client.collection("books").query(
select({
title: field("title"),
title_similarity: fn.semanticSimilarity("title", "catcher"),
text_score: fn.bm25Score(), // Keyword-based relevance
})
.filter(match("classic")) // Ensure the book contains the keyword "classic" in any of the text-indexed fields
// Add 70% weight to semantic similarity and 30% weight to keyword relevance
.sort(field("title_similarity").mul(0.7).add(field("text_score").mul(0.3)), false)
.limit(10)
);
```
```sql SQL
SELECT
title,
semantic_similarity(title, 'catcher') AS title_similarity,
bm25_score() AS text_score
FROM books
WHERE match('classic')
ORDER BY title_similarity * 0.7 + text_score * 0.3 DESC
LIMIT 10;
```
This example above combines **keyword relevance (BM25)** with **semantic similarity**,\
ensuring your search results capture both exact matches and contextual meaning with a **custom scoring function** that's best suited for your use case.
### Multi-vector search
URL: https://docs.topk.io/guides/multi-vector-search
**Prerequisites**
- TopK account ([Sign up here](https://console.topk.io/login))
- TopK API key ([Get an API key here](https://console.topk.io/api-key))
Multi-vector (late-interaction) retrieval represents each document (and query) as a variable-length set of embedding vectors rather than a single embedding vector.
Instead of reducing the input to a single vector via global pooling (e.g., mean pooling) or a dedicated summary token (e.g., CLS), multi-vector representations preserve token-, segment-, or patch-level vectors and score documents using a set-wise similarity function, most commonly [**MaxSim**](#maxsim-scoring).
#### Why multi-vector retrieval is needed
Single-vector retrieval is the most common approach, but it can lose signal when:
- **The document is long**: pooling compresses many distinct concepts into one vector, potentially sacrificing important details in order to preserve overall meaning.
- **The query has multiple aspects**: a single vector tends to overemphasize features repeated across the document and suppress distinctive facets that appear only in localized context but are crucial for precision.
- **Fine-grained matching matters**: named entities, code identifiers, rare terms, or localized image regions are easily lost in single-vector retrieval but can be easily retrieved from token- or patch-level embeddings.
Multi-vector retrieval helps because it evaluates (maximum) relevance of *any* query vector against *some* document vector, instead of computing a single global similarity score.
#### Multi-vector (tensor) embeddings
Embedding models generally represent data internally as an `N x D` matrix:
- **Token-level embeddings**: each of `N` text tokens is represented by a `D`-dimensional vector.
- **Patch / region embeddings** (vision / multimodal): each of `N` patches or regions is represented by a `D`-dimensional vector.
- **Segmented / multi-field encoders**: multiple embeddings per input (e.g., each of `N` paragraphs or sections is represented by a `D`-dimensional vector).
Distinct from traditional embedding models that pool these internal representations in the output layer to produce a single vector, late-interaction models such as
[`ColBERTv2`](https://arxiv.org/abs/2112.01488) (text) and
[`ColPali`](https://arxiv.org/abs/2407.01449) (visual/multimodal)
produce a full `N x D` matrix of token- or patch-level embeddings at the output layer (potentially projected to a lower dimension, quantized, or otherwise compressed), which is then stored in the database for retrieval.
##### MaxSim scoring
For a query `Q` represented by `M` vectors `{q_1,...,q_M}` and a document `D` represented by `N` vectors `{d_1,...,d_N}` (of dimension `D`), the *MaxSim* function computes the similarity between `Q` and `D` as
```
MaxSim(Q, D) = sum_i max_j ⟨q_i, d_j⟩
```
In human words, instead of computing a single overall similarity score between the entire query and document embeddings, MaxSim compares each query token to all document tokens and keeps only the maximum similarity for each query token. The final score is the sum (or average) of these maximum similarities.
With [`metric="maxsim"`](/sdk/topk-py/schema#multi_vector_index), **higher scores indicate better matches**.
#### Define a schema for multi-vector retrieval
In TopK, multi-vector embeddings are stored in a [`matrix()`](/sdk/topk-py/schema#matrix) field and indexed with a [`multi_vector_index()`](/sdk/topk-py/schema#multi_vector_index) using the [`maxsim`](#maxsim-scoring) metric.
```python Python
from topk_sdk.schema import text, matrix, multi_vector_index
client.collections().create(
"passages",
schema={
"content": text().required(),
# Each row is one embedding vector; columns == dimension.
"token_embeddings": matrix(dimension=128, value_type="f16").index(
multi_vector_index(metric="maxsim")
),
},
)
```
```typescript Javascript
import { matrix, multiVectorIndex, text } from "topk-js/schema";
await client.collections().create("passages", {
content: text().required(),
// Each row is one embedding vector; columns == dimension.
token_embeddings: matrix({ dimension: 128, valueType: "f16" }).index(
multiVectorIndex({ metric: "maxsim" })
),
});
```
```sql SQL
CREATE TABLE passages (
content TEXT NOT NULL,
token_embeddings f16_matrix(128) INDEX multi_vector_index(metric = 'maxsim')
);
```
- **`dimension`**: the number of columns `D` in your `N x D` embedding matrix (e.g. 128, 768, 1024).
- **`value_type`**: storage type for matrix elements (`f32`, `f16`, `f8`, `u8`, `i8`). Choose based on your model output and memory/perf needs.
- **`metric="maxsim"`**: a late-interaction style scoring where each query vector contributes based on its best match in the document.
- **`multi_vector_index()`** also accepts optional `quantization` (`"1bit"`, `"2bit"`, `"scalar"`), `width`, and `top_k` for tuning; see [Optimization tips](#optimization-tips) below.
#### Ingest documents with multi-vector embeddings
When upserting documents, include both:
* A multi-vector embedding for given content
* Any relevant document metadata
Each document must also include a required `_id` field.
```python Python
import numpy as np
from topk_sdk.data import matrix
### Example: shape (num_vectors, dimension)
token_embeddings = np.random.randn(12, 128).astype(np.float16)
client.collection("passages").upsert(
[
{
"_id": "p1",
"content": "Late interaction retrieval",
# `numpy.ndarray` is supported out of the box
"token_embeddings": token_embeddings,
},
{
"_id": "p2",
"content": "MaxSim in practice",
# Or use matrix data constructor via `topk_sdk.data.matrix(...)`
"token_embeddings": matrix(token_embeddings, value_type="f16"),
},
]
)
```
```typescript Javascript
import { matrix } from "topk-js/data";
await client.collection("passages").upsert([
{
_id: "p1",
content: "Late interaction retrieval",
token_embeddings: matrix(
[
[0.1, 0.2 /* ... 128 dims ... */],
[0.0, -0.1 /* ... */],
],
"f16"
),
},
]);
```
```sql SQL
INSERT INTO passages (_id, content, token_embeddings)
VALUES
('p1', 'Late interaction retrieval', '[[0.1, 0.2, ..., 0.0], [0.0, -0.1, ..., 0.3]]'::f16_matrix),
('p2', 'MaxSim in practice', '[[0.9, 0.1, ..., 0.5], [0.5, 0.5, ..., 0.2]]'::f16_matrix);
```
TopK has built-in support for [`numpy.ndarray`](https://numpy.org/doc/2.2/reference/generated/numpy.ndarray.html) when ingesting and querying multi-vector (matrix) embeddings. If you pass a 2-D ndarray directly, the matrix value type is inferred from its `dtype` (e.g. `float32`, `float16`, `uint8`, `int8`).
#### Run multi-vector retrieval
Use [`fn.multi_vector_distance()`](/sdk/topk-py/query#multi_vector_distance) to score documents against a query matrix.
When the field is indexed with `metric="maxsim"`, this computes the *MaxSim* score defined above.
```python Python
import numpy as np
from topk_sdk.query import field, fn, select
query_matrix = np.random.randn(8, 128).astype(np.float16)
docs = client.collection("passages").query(
select(
"content",
maxsim=fn.multi_vector_distance(
"token_embeddings",
query_matrix, # `numpy.ndarray` is supported in query matrix as well
candidates=200, # optional: tuning performance vs. recall
),
).sort(field("maxsim"), asc=False).limit(10)
)
print(docs)
### Results:
[
{
"_id": "p2",
"content": "MaxSim in practice",
"maxsim": 0.83,
},
{
"_id": "p1",
"content": "Late interaction retrieval",
"maxsim": 0.79,
},
]
```
```typescript Javascript
import { field, fn, select } from "topk-js/query";
import { matrix } from "topk-js/data";
const queryMatrix = matrix(
[
[0.1, 0.2 /* ... 128 dims ... */],
[0.0, -0.1 /* ... */],
],
"f16"
);
const docs = await client.collection("passages").query(
select({
content: field("content"),
maxsim: fn.multiVectorDistance("token_embeddings", queryMatrix, 200),
}).sort(field("maxsim"), false).limit(10)
);
console.log(docs);
// Results:
[
{
_id: "p2",
content: "MaxSim in practice",
maxsim: 0.83,
},
{
_id: "p1",
content: "Late interaction retrieval",
maxsim: 0.79,
},
]
```
```sql SQL
SELECT
content,
multi_vector_distance(
token_embeddings,
'[[0.1, 0.2, ..., 0.0], [0.0, -0.1, ..., 0.3]]'::f16_matrix,
200
) AS maxsim
FROM passages
ORDER BY maxsim DESC
LIMIT 10;
```
##### Optimization tips
The multi-vector index has an approximate retrieval stage (for faster pruning) followed by a more accurate scoring stage. These parameters let you trade off **memory**, **latency**, and **recall**:
- **`width`**: width of the sparse projection used for approximate MaxSim pruning.
- **Higher width**: more accurate pruning → fewer false negatives (better recall), but higher memory/compute.
- **Lower width**: more aggressive approximation → more false negatives (recall loss), but faster and smaller.
- **`top_k`**: number of top projected values to keep during the approximate stage.
- **`quantization`**: compresses stored multi-vector values.
- **`1bit` / `2bit`**: very compact and fast, but most approximate.
- **`scalar`**: higher-fidelity quantization (larger than 1–2 bit) with better quality.
- **`candidates`**: (query parameter) controls how many top document candidates from the approximate stage are promoted to a more accurate multi-vector scoring pass. Lower values reduce work (faster/cheaper) but can hurt recall; higher values improve recall at the cost of latency.
If you’re starting out, keep defaults, then tune `candidates` and these index parameters (`width`, `top_k`, `quantization`) based on your latency or recall targets.
### Dense vector search
URL: https://docs.topk.io/guides/vector-search
**Prerequisites**
- TopK account ([Sign up here](https://console.topk.io/login))
- TopK API key ([Get an API key here](https://console.topk.io/api-key))
TopK is built for high-performance dense vector search workloads. It is designed to:
- Maintain **>95% recall**, reducing the likelihood of missing relevant results in applications such as recommendation systems, image search, and semantic search.
- Deliver consistent **low latency** (p99 < 50 ms). See the [benchmarks](https://www.topk.io/benchmarks) for details.
- Support **large-scale single-collection** deployments as well as **multi-tenant** architectures.
#### Define a collection schema with a vector field
Define a schema with a vector field and add a [`vector_index()`](/sdk/topk-py/schema#vector_index):
```python Python
from topk_sdk.schema import text, f32_vector, vector_index
client.collections().create(
"books",
schema={
"title": text().required(),
"title_embedding": f32_vector(dimension=1536).required().index(vector_index(metric = "cosine")),
},
)
```
```typescript Javascript
import { text, f32Vector, vectorIndex } from "topk-js/schema";
await client.collections().create("books", {
title: text().required(),
title_embedding: f32Vector({ dimension: 1536 }).required().index(vectorIndex({ metric: "cosine" })),
});
```
```sql SQL
CREATE TABLE books (
title TEXT NOT NULL,
title_embedding f32_vector(1536) NOT NULL INDEX vector_index(metric = 'cosine')
);
```
Supported vector field types:
- **[`f32_vector()`](/sdk/topk-py/schema#f32_vector)** — Dense float32 embeddings (most common)
- **[`u8_vector()`](/sdk/topk-py/schema#u8_vector)** — Quantized uint8 embeddings
- **[`i8_vector()`](/sdk/topk-py/schema#i8_vector)** — Signed quantized int8 embeddings
- **[`binary_vector()`](/sdk/topk-py/schema#binary_vector)** — Binary embeddings (use with `hamming` metric)
- **[`f32_sparse_vector()`](/sdk/topk-py/schema#f32_sparse_vector)** — Sparse embeddings (see [sparse vector search guide](/guides/sparse-vector-search))
- **[`u8_sparse_vector()`](/sdk/topk-py/schema#u8_sparse_vector)** — Quantized sparse embeddings
- **[`matrix()`](/sdk/topk-py/schema#matrix)** — Multi-vector embeddings (see [multi-vector search guide](/guides/multi-vector-search))
See the [schema reference](/sdk/topk-py/schema) for full API details.
#### Perform a k-Nearest Neighbor (kNN) search
To retrieve the top-k nearest neighbors of a query vector, use the [`fn.vector_distance()`](/sdk/topk-py/query#vector_distance) function.
`fn.vector_distance()` computes the distance (or similarity) between a stored vector field and a query vector, based on the distance metric configured in the vector index (e.g., cosine or Euclidean).
You can use the computed value to sort and return the closest matches.
```python Python
from topk_sdk.query import select, field, fn
docs = client.collection("books").query(
select(
"title",
published_year=field("published_year"),
# Compute vector similarity between the vector embedding of the string "epic fantasy adventure"
# and the embedding stored in the `title_embedding` field.
title_similarity=fn.vector_distance("title_embedding", [0.1, 0.2, 0.3, ...]),
)
# cosine/dot-product: higher score = closer → sort descending
.sort(field("title_similarity"), asc=False).limit(10)
# for euclidean distance: lower score = closer → sort ascending
# .sort(field("title_similarity"), asc=True).limit(10)
)
### Example results:
[
{
"_id": "2",
"title": "Lord of the Rings",
"title_similarity": 0.8150404095649719
},
{
"_id": "1",
"title": "The Catcher in the Rye",
"title_similarity": 0.7825378179550171,
}
]
```
```js Javascript
import { select, field, fn } from "topk-js/query";
const docs = await client.collection("books").query(
select({
title: field("title"),
published_year: field("published_year"),
title_similarity: fn.vectorDistance(
"title_embedding",
// Compute vector similarity between the vector embedding of the string "epic fantasy adventure"
// and the embedding stored in the `title_embedding` field.
[0.1, 0.2, 0.3 /* ... */]
),
// cosine/dot-product: higher score = closer → sort descending
}).sort(field("title_similarity"), false).limit(10)
// for euclidean distance: lower score = closer → sort ascending
// }).sort(field("title_similarity"), true).limit(10)
);
// Example results:
[
{
_id: '2',
title: 'Lord of the Rings',
title_similarity: 0.8150404095649719
},
{
_id: '1',
title_similarity: 0.7825378179550171,
title: 'The Catcher in the Rye',
}
]
```
```sql SQL
SELECT
title,
published_year,
vector_distance(title_embedding, '[0.1, 0.2, ..., 0.3]'::f32_vector) AS title_similarity
FROM books
-- For cosine/dot_product: higher is closer → DESC
-- For euclidean: lower is closer → ASC
ORDER BY title_similarity DESC
LIMIT 10;
```
Let's break down the example above:
1. Compute the cosine similarity between the query embedding and the `title_embedding` field using the `vector_distance()` function.
2. Store the computed cosine similarity in the `title_similarity` field.
3. Return the top 10 results sorted by the `title_similarity` field in a descending order.
#### Combine vector search with metadata filtering
Vector search can be combined with metadata filtering by adding a [`filter()`](/sdk/topk-py/query#filter) stage to the query:
```python Python
from topk_sdk.query import select, field, fn
docs = client.collection("books").query(
select(
"title",
title_similarity=fn.vector_distance("title_embedding", [0.1, 0.2, 0.3, ...]),
published_year=field("published_year"),
)
.filter(field("published_year") > 2000)
.sort(field("title_similarity"), asc=False).limit(10)
)
```
```js Javascript
import { select, field, fn } from "topk-js/query";
const docs = await client.collection("books").query(
select({
title: field("title"),
title_similarity: fn.vectorDistance(
"title_embedding",
[0.1, 0.2, 0.3 /* ... */]
),
published_year: field("published_year"),
})
.filter(field("published_year").gt(2000))
.sort(field("title_similarity"), false).limit(10)
);
```
```sql SQL
SELECT
title,
published_year,
vector_distance(title_embedding, '[0.1, 0.2, ..., 0.3]'::f32_vector) AS title_similarity
FROM books
WHERE published_year > 2000
ORDER BY title_similarity DESC
LIMIT 10;
```
### Sparse vector search
URL: https://docs.topk.io/guides/sparse-vector-search
**Prerequisites**
- TopK account ([Sign up here](https://console.topk.io/login))
- TopK API key ([Get an API key here](https://console.topk.io/api-key))
TopK provides native support for sparse vector search, enabling exact retrieval over high-dimensional sparse representations.
It is designed to:
- Provide **100% recall** (exact search).
- Support learned sparse representations such as [SPLADE](https://github.com/naver/splade).
- Deliver consistent **low latency** (p99 < 20 ms). See the [benchmarks](https://www.topk.io/benchmarks) for details.
- Support **large-scale single-collection** deployments as well as **multi-tenant** architectures.
#### Define a collection schema with a sparse vector field
Define a schema with a sparse vector field and add a [`vector_index()`](/sdk/topk-py/schema#vector_index):
```python Python
from topk_sdk.schema import text, f32_sparse_vector, vector_index
client.collections().create(
"books",
schema={
"title": text().required(),
"title_embedding": f32_sparse_vector()
.required()
.index(vector_index(metric = "dot_product")),
},
)
```
```typescript Javascript
import { text, f32SparseVector, vectorIndex } from "topk-js/schema";
await client.collections().create("books", {
title: text().required(),
title_embedding: f32SparseVector()
.required()
.index(vectorIndex({ metric: "dot_product" })),
});
```
```sql SQL
CREATE TABLE books (
title TEXT NOT NULL,
title_embedding f32_sparse_vector NOT NULL INDEX vector_index(metric = 'dot_product')
);
```
Supported sparse vector field types:
- **[`f32_sparse_vector()`](/sdk/topk-py/schema#f32_sparse_vector)** — Sparse float32 embeddings
- **[`u8_sparse_vector()`](/sdk/topk-py/schema#u8_sparse_vector)** — Sparse uint8 embeddings
See the [schema reference](/sdk/topk-py/schema) for full API details.
Sparse vectors do not have a fixed dimension, so you don't need to specify the vector dimension when defining the field.
TopK only supports `dot_product` metric for sparse vectors which is compatible with both fixed and learned sparse
vector representations.
#### Perform a sparse vector search
To retrieve the top-k nearest neighbors of a query vector, use the [`fn.vector_distance()`](/sdk/topk-py/query#vector_distance) function.
`fn.vector_distance()` computes the distance (or similarity) between a stored sparse vector field and a query vector, based on the distance metric configured in the vector index (e.g., dot product).
You can use the computed value to sort and return the closest matches.
```python Python
from topk_sdk.query import select, field, fn
from topk_sdk.data import f32_sparse_vector
docs = client.collection("books").query(
select(
"title",
published_year=field("published_year"),
# Compute relevance score between the sparse vector embedding of the string "epic fantasy adventure"
# and the embedding stored in the `title_embedding` field.
title_score=fn.vector_distance(
"title_embedding",
f32_sparse_vector({0: 0.12, 6: 0.67, ...}),
)
)
# Return top 10 results
.sort(field("title_score"), asc=False).limit(10)
)
### Example results:
[
{
"_id": "2",
"title": "Lord of the Rings",
"title_score": 0.8150404095649719
},
{
"_id": "1",
"title": "The Catcher in the Rye",
"title_score": 0.7825378179550171,
}
]
```
```js Javascript
import { select, field, fn } from "topk-js/query";
import { f32SparseVector } from "topk-js/data";
const docs = await client.collection("books").query(
select({
title: field("title"),
published_year: field("published_year"),
title_score: fn.vectorDistance(
"title_embedding",
// Compute relevance score between the sparse vector embedding of the string "epic fantasy adventure"
// and the embedding stored in the `title_embedding` field.
f32SparseVector({0: 0.12, 6: 0.67, ...})
),
}).sort(field("title_score"), false).limit(10)
);
// Example results:
[
{
_id: '2',
title: 'Lord of the Rings',
title_score: 0.8150404095649719
},
{
_id: '1',
title_score: 0.7825378179550171,
title: 'The Catcher in the Rye',
}
]
```
```sql SQL
SELECT
title,
published_year,
vector_distance(title_embedding, '{"0": 0.12, "6": 0.67}'::f32_sparse_vector) AS title_score
FROM books
ORDER BY title_score DESC
LIMIT 10;
```
Let's break down the example above:
1. Compute the sparse dot product between the query embedding and the `title_embedding` field using the `vector_distance()` function.
2. Store the computed dot product score in the `title_score` field.
3. Return the top 10 results sorted by the `title_score` field in a descending order.
#### Combine sparse vector search with metadata filtering
Sparse vector search can be combined with metadata filtering by adding a [`filter()`](/sdk/topk-py/query#filter) stage to the query:
```python Python
from topk_sdk.query import select, field, fn
from topk_sdk.data import f32_sparse_vector
docs = client.collection("books").query(
select(
"title",
title_score=fn.vector_distance(
"title_embedding",
f32_sparse_vector({0: 0.12, 6: 0.67, ...}),
)
published_year=field("published_year"),
)
.filter(field("published_year") > 2000)
.sort(field("title_score"), asc=False).limit(10)
)
```
```js Javascript
import { select, field, fn } from "topk-js/query";
import { f32SparseVector } from "topk-js/data";
const docs = await client.collection("books").query(
select({
title: field("title"),
title_score: fn.vectorDistance(
"title_embedding",
f32SparseVector({0: 0.12, 6: 0.67, ...})
),
published_year: field("published_year"),
})
.filter(field("published_year").gt(2000))
.sort(field("title_score"), false).limit(10)
);
```
```sql SQL
SELECT
title,
published_year,
vector_distance(title_embedding, '{"0": 0.12, "6": 0.67}'::f32_sparse_vector) AS title_score
FROM books
WHERE published_year > 2000
ORDER BY title_score DESC
LIMIT 10;
```
### Keyword search (BM25)
URL: https://docs.topk.io/guides/keyword-search
**Prerequisites**
- TopK account ([Sign up here](https://console.topk.io/login))
- TopK API key ([Get an API key here](https://console.topk.io/api-key))
TopK supports keyword search with the BM25 ranking function.
To perform a keyword search on your documents, use the [`match()`](/sdk/topk-py/query#match) function.
#### Define a collection schema for keyword search
Define a schema with a [`text()`](/sdk/topk-py/schema#text) field and add a [`keyword_index()`](/sdk/topk-py/schema#keyword_index):
```python Python
from topk_sdk.schema import text, keyword_index
client.collections().create(
"books",
schema={
"title": text().index(keyword_index()),
"description": text().index(keyword_index()),
},
)
```
```js Javascript
import { text, keywordIndex } from "topk-js/schema";
await client.collections().create("books", {
title: text().index(keywordIndex()),
description: text().index(keywordIndex()),
});
```
```sql SQL
CREATE TABLE books (
title TEXT INDEX keyword_index(),
description TEXT INDEX keyword_index()
);
```
#### Run a keyword search
To run a keyword search on the `title` and `description` fields using the [`match()`](/sdk/topk-py/query#match) function.
We'll query the collection to match the term `"great"` in the `title` field or the term `"novel"` in any of the keyword-indexed text fields:
```python Python
from topk_sdk.query import select, fn, match, field
docs = client.collection("books").query(
select(
"title",
"description",
# Score documents using BM25 algorithm
text_score=fn.bm25_score(),
)
# Filter documents that have the `great` keyword in the `title` field
# or the `novel` in any of the text-indexed fields.
.filter(
match("great", field="title") | match("novel")
)
# Return top 10 documents with the highest text score
.sort(field("text_score"), asc=False).limit(10)
)
### Example result:
[
{
_id: '1',
title: 'The Great Gatsby',
description: 'A novel about a great man who wants to be rich and famous',
text_score: 0.864456057548523
},
{
_id: '2',
title: 'The Catcher in the Rye',
description: 'A novel about a boy who wants to be a writer',
text_score: 0.1948474943637848,
}
]
```
```js Javascript
import { select, field, fn, match } from "topk-js/query";
const docs = await client.collection("books").query(
select({
title: field("title"),
description: field("description"),
// Score documents using BM25 algorithm
text_score: fn.bm25Score(),
})
// Filter documents that have the `great` keyword in the `title` field
// or the `novel` in any of the text-indexed fields.
.filter(match("great", { field: "title" }).or(match("novel")))
// Return top 10 documents with the highest text score
.sort(field("text_score"), false).limit(10)
);
// Example result:
[
{
_id: '1',
title: 'The Great Gatsby',
description: 'A novel about a great man who wants to be rich and famous',
text_score: 0.864456057548523
},
{
_id: '2',
title: 'The Catcher in the Rye',
description: 'A novel about a boy who wants to be a writer',
text_score: 0.1948474943637848,
}
]
```
```sql SQL
SELECT
title,
description,
bm25_score() AS text_score
FROM books
WHERE match('great') OR match('novel')
ORDER BY text_score DESC
LIMIT 10;
```
The `match()` function will by default execute against all
fields with a [**keyword index**](/collections/create#keyword-index).
TopK provides a powerful keyword search API allowing you to customize your search queries.
Read more about keyword search [here](/collections/query#keyword-search).
### True Hybrid search
URL: https://docs.topk.io/guides/true-hybrid-search
**Prerequisites**
- TopK account ([Sign up here](https://console.topk.io/login))
- TopK API key ([Get an API key here](https://console.topk.io/api-key))
With TopK's true hybrid search, you can combine multiple retrieval techniques such as:
* vector search
* multi-vector search
* keyword search
* metadata filtering
-- all in a single query.
#### How TopK differs from other "hybrid" search systems
Most databases that offer hybrid search maintain separate vector and keyword indexes. When a query is executed they:
1. Run two separate queries for both indexes
2. Collect the top results from each query (e.g. first 100 + 100 candidates)
3. Use techniques like Reciprocal Rank Fusion (RRF) to merge and rerank these two sets of results
```mermaid
flowchart TD
A[User Query] --> B[(Query Keyword Index)]
A --> C[(Query Vector Index)]
B --> D@{ shape: docs, label: "Top 100 Keyword search results" }
C --> E@{ shape: docs, label: "Top 100 Vector search results" }
D --> F{Merge and rerank top 200 results using RRF}
E --> F
F --> G@{ shape: stadium, label: "Merged 100 top results" }
```
This approach is fundamentally **probabilistic** - the final top-k results are not guaranteed to be the actual best candidates because some potential candidates might be missed if they don't appear in either index's top results.
**TopK is different.** It runs through a single index(vector \+ keyword), ensuring that our "top 100" results are the **actual** top 100 - not just a probabilistic approximation:
```mermaid
flowchart TD
A[User Query]
A --> B[(Keyword Index)]
A --> C[(Vector Index)]
B --> D{Scan a single index and retrieve top 100 results}
C --> D
D --> F@{ shape: stadium, label: "True top 100 results" }
```
With TopK, you can:
- Retrieve documents based on multiple embeddings -- **Multi-vector retrieval**
- Combine semantic similarity(e.g vector search) with keyword search -- **True Hybrid Retrieval**
- **Filter documents** by their metadata
- Apply custom scoring functions blending multiple ranking factors -- **Custom scoring**
#### Implementing Hybrid Search (Vector \+ Keyword)
Hybrid retrieval combines **semantic similarity (vector-based search)** with **exact keyword matching**. This approach ensures that documents with **direct keyword matches** are considered alongside those that are **semantically similar** to the query.
Let's define a collection with one [`keyword_index()`](/collections/create#keyword-index) and one [`semantic_index()`](/collections/create#semantic-index):
```python Python
from topk_sdk.schema import text, keyword_index, semantic_index
client.collections().create(
"articles",
schema={
"title": text().required().index(keyword_index()), # Keyword-based retrieval
"content": text().index(semantic_index()), # Semantic search
},
)
```
```typescript Javascript
import { text, keywordIndex, semanticIndex } from "topk-js/schema";
await client.collections().create("articles", {
title: text().required().index(keywordIndex()), // Keyword-based retrieval
content: text().index(semanticIndex()), // Semantic search
});
```
```sql SQL
CREATE TABLE articles (
title TEXT NOT NULL INDEX keyword_index(),
content TEXT INDEX semantic_index()
);
```
In the following example we'll perform a hybrid search that combines keyword and vector(semantic) search in a single query:
```python Python
from topk_sdk.query import select, field, fn, match
docs = client.collection("articles").query(
select(
"title",
content_similarity=fn.semantic_similarity("content", "climate change policies"),
text_score=fn.bm25_score(),
)
.filter(match("carbon") | match("renewable energy")) # Ensure keyword relevance
.sort(field("content_similarity") * 0.6 + field("text_score") * 0.4, asc=False).limit(10)
)
```
```typescript Javascript
import { select, field, fn, match } from "topk-js/query";
const docs = await client.collection("articles").query(
select({
title: field("title"),
content_similarity: fn.semanticSimilarity(
"content",
"climate change policies"
),
text_score: fn.bm25Score(),
})
.filter(match("carbon").or(match("renewable energy"))) // Ensure keyword relevance
.sort(
field("content_similarity").mul(0.6).add(field("text_score").mul(0.4)),
false
).limit(10)
);
```
```sql SQL
SELECT
title,
semantic_similarity(content, 'climate change policies') AS content_similarity,
bm25_score() AS text_score
FROM articles
WHERE match('carbon', title) OR match('renewable energy', title)
ORDER BY content_similarity * 0.6 + text_score * 0.4 DESC
LIMIT 10;
```
Let's break down the example above:
- We retrieve documents based on semantic meaning (`content_similarity`) and keyword matching (`text_score`).
- The `filter()` ensures that documents contain at least one relevant keyword.
- The `topk()` function weights the scores, prioritizing semantic meaning (60%) while still considering keyword matches (40%).
This **balances precision and recall**, capturing both **exact keyword matches** and **meaningful context**.
#### Implementing Complex Search(Keyword \+ Vector \+ Filtering)
In TopK, you can combine [keyword search](/guides/keyword-search), [vector search](/guides/vector-search), and [filtering](/collections/query#filtering) in a single query.
This allows you to fetch the truly **most relevant results** while maintaining a steady performance - no overfetching.
```python Python
from topk_sdk.query import select, field, fn, match
docs = client.collection("books").query(
select(
"title",
# Score documents using BM25 algorithm
text_score=fn.bm25_score(),
# Compute semantic similarity between the provided query and the `title` field.
title_similarity=fn.semantic_similarity("title", "catcher"),
)
# Filter documents that contain the `great` keyword
.filter(match("great"))
# Filtering by metadata
.filter(field("published_year") > 1980)
# Return top 10 documents with the highest combined score
.sort(field("text_score") * 0.2 + field("title_similarity") * 0.8, asc=False).limit(10)
)
```
```typescript Javascript
import { select, fn, field, match } from "topk-js/query";
const docs = await client.collection("books").query(
select({
title: field("title"),
text_score: fn.bm25Score(),
title_similarity: fn.semanticSimilarity("title", "catcher"),
})
.filter(match("great"))
.filter(field("published_year").gt(1980))
.sort(
field("text_score").mul(0.2).add(field("title_similarity").mul(0.8)),
false
).limit(10)
);
```
```sql SQL
-- In SQL, keyword and semantic indexes must be on separate fields (unlike the SDK).
-- This uses 'articles' from above: title (keyword_index) + content (semantic_index).
SELECT
title,
semantic_similarity(content, 'climate policy') AS content_similarity
FROM articles
WHERE match_any(title, 'carbon')
AND published_year > 2020
ORDER BY content_similarity DESC
LIMIT 10;
```
As you might have noticed, we are also sorting the top-k results using a custom scoring function.
You can read more about custom scoring functions in the following section.
#### Custom Scoring Functions
TopK allows you to **define custom scoring functions** by combining:
- Semantic similarity score
- Keyword score(BM25)
- Vector distance
- "Bring-your-own" precomputed importance score
##### Defining a Collection with Custom Scoring Fields
```python Python
from topk_sdk.schema import text, float, semantic_index
client.collections().create(
"documents",
schema={
"content": text().index(semantic_index()), # Semantic search
"importance": float().required(), # Precomputed importance score
},
)
```
```typescript Javascript
import { text, float, semanticIndex } from "topk-js/schema";
await client.collections().create("documents", {
content: text().index(semanticIndex()), // Semantic search
importance: float().required(), // Precomputed importance score
});
```
```sql SQL
CREATE TABLE documents (
content TEXT INDEX semantic_index(),
importance FLOAT NOT NULL
);
```
##### Querying with a Custom Scoring Function
```python Python
from topk_sdk.query import select, field, fn
docs = client.collection("documents").query(
select(
"content",
"importance",
content_score=fn.semantic_similarity("content", "machine learning applications"),
)
.sort(0.8 * field("importance") + 0.2 * field("content_score"), asc=False).limit(10)
)
```
```typescript Javascript
import { select, field, fn } from "topk-js/query";
const docs = await client.collection("documents").query(
select({
content: field("content"),
importance: field("importance"),
content_score: fn.semanticSimilarity(
"content",
"machine learning applications"
),
}).sort(
field("importance").mul(0.8).add(field("content_score").mul(0.2)),
false
).limit(10)
);
```
```sql SQL
SELECT
content,
importance,
semantic_similarity(content, 'machine learning applications') AS content_score
FROM documents
ORDER BY importance * 0.8 + content_score * 0.2 DESC
LIMIT 10;
```
Let's break down the example above:
1. First, we retrieve documents based on both semantic similarity (`content_score`) and precomputed importance (`importance_score`).
2. Then, the `topk()` function gives 80% weight to content score and 20% weight to document importance.
3. Sorting by a custom scoring function allows us to boost more critical documents, ensuring that highly relevant but less "important" content doesn't dominate.
## Python SDK Reference
### topk_sdk
URL: https://docs.topk.io/sdk/topk-py
#### Classes
##### Client
Client for interacting with the TopK API. For available regions see [regions](/regions)
**Methods**
**Constructor**
```python
Client(
api_key: str,
region: str,
host: str = "topk.io",
https: bool = True,
retry_config: Optional[RetryConfig | dict[str, Any]] = None
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `api_key` | str |
| `region` | str |
| `host` | str |
| `https` | bool |
| `retry_config` | Optional[[`RetryConfig`](#retryconfig) | dict[str, Any]] |
###### collection()
```python
collection(self, collection: str, partition: Optional[str] = None) -> CollectionClient
```
Get a client for managing data operations on a specific collection such as querying, upserting, and deleting documents.
Optionally, pass partition name to scope data operations to that partition.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `collection` | str |
| `partition` | Optional[str] |
**Returns**
[`CollectionClient`](#collectionclient)
***
###### collections()
```python
collections(self) -> CollectionsClient
```
Get a client for managing collections.
**Returns**
[`CollectionsClient`](#collectionsclient)
***
##### AsyncClient
Async client for interacting with the TopK API. For available regions see [regions](/regions)
**Methods**
**Constructor**
```python
AsyncClient(
api_key: str,
region: str,
host: str = "topk.io",
https: bool = True,
retry_config: Optional[RetryConfig | dict[str, Any]] = None
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `api_key` | str |
| `region` | str |
| `host` | str |
| `https` | bool |
| `retry_config` | Optional[[`RetryConfig`](#retryconfig) | dict[str, Any]] |
###### collection()
```python
collection(self, collection: str, partition: Optional[str] = None) -> AsyncCollectionClient
```
Get an async client for a specific collection.
Optionally, pass partition name to scope data operations to that partition.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `collection` | str |
| `partition` | Optional[str] |
**Returns**
[`AsyncCollectionClient`](#asynccollectionclient)
***
###### collections()
```python
collections(self) -> AsyncCollectionsClient
```
Get an async client for managing collections.
**Returns**
[`AsyncCollectionsClient`](#asynccollectionsclient)
***
##### CollectionClient
Synchronous client for collection operations.
**Methods**
###### get()
```python
get(
self,
ids: Sequence[str],
fields: Optional[Sequence[str]] = None,
lsn: Optional[str] = None,
consistency: Optional[ConsistencyLevel | Literal['indexed', 'strong']] = None
)
```
Get documents by their IDs.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `ids` | Sequence[str] |
| `fields` | Optional[Sequence[str]] |
| `lsn` | Optional[str] |
| `consistency` | Optional[[`ConsistencyLevel`](#consistencylevel) | Literal['indexed', 'strong']] |
**Returns**
dict[str, dict[str, Any]]
***
###### count()
```python
count(
self,
lsn: Optional[str] = None,
consistency: Optional[ConsistencyLevel | Literal['indexed', 'strong']] = None
)
```
Get the count of documents in the collection.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `lsn` | Optional[str] |
| `consistency` | Optional[[`ConsistencyLevel`](#consistencylevel) | Literal['indexed', 'strong']] |
**Returns**
int
***
###### query()
```python
query(
self,
query: query.Query,
lsn: Optional[str] = None,
consistency: Optional[ConsistencyLevel | Literal['indexed', 'strong']] = None
)
```
Execute a query against the collection.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `query` | [`query.Query`](/sdk/topk-py/query#query) |
| `lsn` | Optional[str] |
| `consistency` | Optional[[`ConsistencyLevel`](#consistencylevel) | Literal['indexed', 'strong']] |
**Returns**
list[dict[str, Any]]
***
###### upsert()
```python
upsert(self, documents: Sequence[Mapping[str, Any]]) -> str
```
Insert or update documents in the collection.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `documents` | Sequence[Mapping[str, Any]] |
**Returns**
str
***
###### update()
```python
update(self, documents: Sequence[Mapping[str, Any]], fail_on_missing: Optional[bool] = None) -> str
```
Update documents in the collection.
Existing documents will be merged with the provided fields.
Missing documents will be ignored.
Returns the `LSN` at which the update was applied.
If no updates were applied, this will be empty.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `documents` | Sequence[Mapping[str, Any]] |
| `fail_on_missing` | Optional[bool] |
**Returns**
str
***
###### delete()
```python
delete(self, expr: Sequence[str] | query.LogicalExpr) -> str
```
Delete documents by their IDs or using a filter expression.
**Example:**
Delete documents by their IDs:
```python
client.collection("books").delete(["id_1", "id_2"])
```
Delete documents by a filter expression:
```python
from topk_sdk.query import field
client.collection("books").delete(field("published_year").gt(1997))
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `expr` | Sequence[str] | [`query.LogicalExpr`](/sdk/topk-py/query#logicalexpr) |
**Returns**
str
***
###### list\_partitions()
```python
list_partitions(self, prefix: Optional[str] = None) -> PartitionListIterator
```
List partitions in the collection as an iterator.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `prefix` | Optional[str] |
**Returns**
[`PartitionListIterator`](#partitionlistiterator)
***
###### delete\_partition()
```python
delete_partition(self, name: str) -> None
```
Delete a partition and all documents within it.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `name` | str |
**Returns**
None
***
##### AsyncCollectionClient
Asynchronous client for collection operations.
**Methods**
###### get()
```python
get(
self,
ids: Sequence[str],
fields: Optional[Sequence[str]] = None,
lsn: Optional[str] = None,
consistency: Optional[ConsistencyLevel | Literal['indexed', 'strong']] = None
)
```
Get documents by their IDs asynchronously.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `ids` | Sequence[str] |
| `fields` | Optional[Sequence[str]] |
| `lsn` | Optional[str] |
| `consistency` | Optional[[`ConsistencyLevel`](#consistencylevel) | Literal['indexed', 'strong']] |
**Returns**
Awaitable[dict[str, dict[str, Any]]]
***
###### count()
```python
count(
self,
lsn: Optional[str] = None,
consistency: Optional[ConsistencyLevel | Literal['indexed', 'strong']] = None
)
```
Get the count of documents in the collection asynchronously.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `lsn` | Optional[str] |
| `consistency` | Optional[[`ConsistencyLevel`](#consistencylevel) | Literal['indexed', 'strong']] |
**Returns**
Awaitable[int]
***
###### query()
```python
query(
self,
query: query.Query,
lsn: Optional[str] = None,
consistency: Optional[ConsistencyLevel | Literal['indexed', 'strong']] = None
)
```
Execute a query against the collection asynchronously.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `query` | [`query.Query`](/sdk/topk-py/query#query) |
| `lsn` | Optional[str] |
| `consistency` | Optional[[`ConsistencyLevel`](#consistencylevel) | Literal['indexed', 'strong']] |
**Returns**
Awaitable[list[dict[str, Any]]]
***
###### upsert()
```python
upsert(self, documents: Sequence[Mapping[str, Any]]) -> Awaitable[str]
```
Insert or update documents in the collection asynchronously.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `documents` | Sequence[Mapping[str, Any]] |
**Returns**
Awaitable[str]
***
###### update()
```python
update(
self,
documents: Sequence[Mapping[str, Any]],
fail_on_missing: Optional[bool] = None
)
```
Update documents in the collection asynchronously.
Existing documents will be merged with the provided fields.
Missing documents will be ignored.
Returns the `LSN` at which the update was applied.
If no updates were applied, this will be empty.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `documents` | Sequence[Mapping[str, Any]] |
| `fail_on_missing` | Optional[bool] |
**Returns**
Awaitable[str]
***
###### delete()
```python
delete(self, expr: Sequence[str] | query.LogicalExpr) -> Awaitable[str]
```
Delete documents by their IDs or using a filter expression asynchronously.
**Example:**
Delete documents by their IDs:
```python
await client.collection("books").delete(["id_1", "id_2"])
```
Delete documents by a filter expression:
```python
from topk_sdk.query import field
await client.collection("books").delete(field("published_year").gt(1997))
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `expr` | Sequence[str] | [`query.LogicalExpr`](/sdk/topk-py/query#logicalexpr) |
**Returns**
Awaitable[str]
***
###### list\_partitions()
```python
list_partitions(self, prefix: Optional[str] = None) -> AsyncPartitionListIterator
```
List partitions in the collection as an async iterator.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `prefix` | Optional[str] |
**Returns**
[`AsyncPartitionListIterator`](#asyncpartitionlistiterator)
***
###### delete\_partition()
```python
delete_partition(self, name: str) -> Awaitable[None]
```
Delete a partition and all documents within it asynchronously.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `name` | str |
**Returns**
Awaitable[None]
***
##### Collection
Represents a collection in the TopK system.
**Properties**
| Property | Type | |
| -------- | ---- | ----------- |
| `name` | str | |
| `org_id` | str | |
| `project_id` | str | |
| `region` | str | |
| `schema` | dict[str, [`schema.FieldSpec`](/sdk/topk-py/schema#fieldspec)] | |
| `created_at` | str | |
##### Partition
Represents a partition in a collection.
**Properties**
| Property | Type | |
| -------- | ---- | ----------- |
| `name` | str | |
| `created_at` | str | |
##### CollectionsClient
Synchronous client for managing collections.
**Methods**
###### get()
```python
get(self, collection_name: str) -> Collection
```
Get information about a specific collection.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `collection_name` | str |
**Returns**
[`Collection`](#collection)
***
###### list()
```python
list(self) -> list[Collection]
```
List all collections.
**Returns**
list[[`Collection`](#collection)]
***
###### create()
```python
create(self, collection_name: str, schema: Mapping[str, schema.SchemaFieldSpec]) -> Collection
```
Create a new collection with the specified schema.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `collection_name` | str |
| `schema` | Mapping[str, [`schema.SchemaFieldSpec`](/sdk/topk-py/schema#schemafieldspec)] |
**Returns**
[`Collection`](#collection)
***
###### delete()
```python
delete(self, collection_name: str) -> None
```
Delete a collection.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `collection_name` | str |
**Returns**
None
***
##### AsyncCollectionsClient
Asynchronous client for managing collections.
**Methods**
###### get()
```python
get(self, collection_name: str) -> Awaitable[Collection]
```
Get information about a specific collection asynchronously.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `collection_name` | str |
**Returns**
Awaitable[[`Collection`](#collection)]
***
###### list()
```python
list(self) -> Awaitable[list[Collection]]
```
List all collections asynchronously.
**Returns**
Awaitable[list[[`Collection`](#collection)]]
***
###### create()
```python
create(
self,
collection_name: str,
schema: Mapping[str, schema.SchemaFieldSpec]
)
```
Create a new collection with the specified schema asynchronously.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `collection_name` | str |
| `schema` | Mapping[str, [`schema.SchemaFieldSpec`](/sdk/topk-py/schema#schemafieldspec)] |
**Returns**
Awaitable[[`Collection`](#collection)]
***
###### delete()
```python
delete(self, collection_name: str) -> Awaitable[None]
```
Delete a collection asynchronously.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `collection_name` | str |
**Returns**
Awaitable[None]
***
##### PartitionListIterator
Iterator for synchronous partition list responses.
##### AsyncPartitionListIterator
Iterator for asynchronous partition list responses.
##### ConsistencyLevel
Consistency level for read operations.
**Properties**
| Property | Type | |
| -------- | ---- | ----------- |
| `Indexed` | [`ConsistencyLevel`](#consistencylevel) | |
| `Strong` | [`ConsistencyLevel`](#consistencylevel) | |
##### RetryConfig
Configuration for retry behavior.
By default, retries occur in two situations:
1. When the server requests the client to reduce its request rate, resulting in a [SlowDownError](/sdk/topk-py/error#slowdownerror).
2. When using the `query(..., lsn=N)` to wait for writes to be available.
**Properties**
| Property | Type | |
| -------- | ---- | ----------- |
| `max_retries` | Optional[int] | Maximum number of retries to attempt. Default is 3 retries. |
| `timeout` | Optional[int] | The total timetout for the retry chain in milliseconds. Default is 30,000 milliseconds (30 seconds) |
| `backoff` | Optional[[`BackoffConfig`](#backoffconfig)] | The backoff configuration for the client. |
**Methods**
**Constructor**
```python
RetryConfig(
max_retries: Optional[int] = None,
timeout: Optional[int] = None,
backoff: Optional[BackoffConfig] = None
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `max_retries` | Optional[int] |
| `timeout` | Optional[int] |
| `backoff` | Optional[[`BackoffConfig`](#backoffconfig)] |
##### BackoffConfig
Configuration for backoff behavior in retries.
**Properties**
| Property | Type | |
| -------- | ---- | ----------- |
| `base` | Optional[int] | The base for the backoff. Default is 2x backoff. |
| `init_backoff` | Optional[int] | The initial backoff in milliseconds. Default is 100 milliseconds. |
| `max_backoff` | Optional[int] | The maximum backoff in milliseconds. Default is 10,000 milliseconds (10 seconds). |
**Methods**
**Constructor**
```python
BackoffConfig(
base: Optional[int] = None,
init_backoff: Optional[int] = None,
max_backoff: Optional[int] = None
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `base` | Optional[int] |
| `init_backoff` | Optional[int] |
| `max_backoff` | Optional[int] |
### topk_sdk.data
URL: https://docs.topk.io/sdk/topk-py/data
#### Classes
##### List
*Internal*
Instances of the `List` class are used to represent lists of values in TopK.
Usually created using data constructors such as [`f32_list()`](#f32-list), [`i32_list()`](#i32-list), etc.
##### SparseVector
*Internal*
Instances of the `SparseVector` class are used to represent sparse vectors in TopK.
Usually created using data constructors such as [`f32_sparse_vector()`](#f32-sparse-vector) or [`u8_sparse_vector()`](#u8-sparse-vector).
##### Matrix
*Internal*
Instances of the `Matrix` class are used to represent matrices in TopK.
Usually created using data constructors such as [`matrix()`](#matrix-2).
##### Struct
*Internal*
Instances of the `Struct` class are used to represent nested object values in TopK.
Usually created using the [`struct()`](#struct) helper.
##### UnknownValue
*Internal*
Placeholder for a value this version of the SDK cannot represent.
#### Functions
##### f8_vector()
```python
f8_vector(data: list[float]) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing a 8-bit float vector.
Example:
```python
from topk_sdk.data import f8_vector
f8_vector([0.12, 0.67, 0.82, 0.53])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[float] |
**Returns**
[`List`](#list)
***
##### f16_vector()
```python
f16_vector(data: list[float]) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing a 16-bit float vector.
Example:
```python
from topk_sdk.data import f16_vector
f16_vector([0.12, 0.67, 0.82, 0.53])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[float] |
**Returns**
[`List`](#list)
***
##### f32_vector()
```python
f32_vector(data: list[float]) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing a 32-bit float vector. This function is an alias for [f32_list()](/sdk/topk-py/data#f32-list).
Example:
```python
from topk_sdk.data import f32_vector
f32_vector([0.12, 0.67, 0.82, 0.53])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[float] |
**Returns**
[`List`](#list)
***
##### u8_vector()
```python
u8_vector(data: list[int]) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing an 8-bit unsigned integer vector. This function is an alias for [u8_list()](/sdk/topk-py/data#u8-list).
Example:
```python
from topk_sdk.data import u8_vector
u8_vector([0, 255, 1, 2, 3])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[int] |
**Returns**
[`List`](#list)
***
##### i8_vector()
```python
i8_vector(data: list[int]) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing an 8-bit signed integer vector.
Example:
```python
from topk_sdk.data import i8_vector
i8_vector([-128, 127, -1, 0, 1])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[int] |
**Returns**
[`List`](#list)
***
##### binary_vector()
```python
binary_vector(data: list[int]) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing a binary vector.
Example:
```python
from topk_sdk.data import binary_vector
binary_vector([0, 1, 1, 0])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[int] |
**Returns**
[`List`](#list)
***
##### f32_sparse_vector()
```python
f32_sparse_vector(data: dict[int, float]) -> SparseVector
```
Create a [SparseVector](/sdk/topk-py/data#SparseVector) type containing a 32-bit float sparse vector.
Example:
```python
from topk_sdk.data import f32_sparse_vector
f32_sparse_vector({0: 0.12, 6: 0.67, 17: 0.82, 97: 0.53})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | dict[int, float] |
**Returns**
[`SparseVector`](#sparsevector)
***
##### u8_sparse_vector()
```python
u8_sparse_vector(data: dict[int, int]) -> SparseVector
```
Create a [SparseVector](/sdk/topk-py/data#SparseVector) type containing an 8-bit unsigned integer sparse vector.
Example:
```python
from topk_sdk.data import u8_sparse_vector
u8_sparse_vector({0: 12, 6: 67, 17: 82, 97: 53})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | dict[int, int] |
**Returns**
[`SparseVector`](#sparsevector)
***
##### bytes()
```python
bytes(data: list[int] | bytes) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing bytes data.
Example:
```python
from topk_sdk.data import bytes
bytes([0, 1, 1, 0])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[int] | bytes |
**Returns**
[`List`](#list)
***
##### u32_list()
```python
u32_list(data: list[int]) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing a list of 32-bit unsigned integers.
Example:
```python
from topk_sdk.data import u32_list
u32_list([0, 1, 2, 3])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[int] |
**Returns**
[`List`](#list)
***
##### i32_list()
```python
i32_list(data: list[int]) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing a list of 32-bit signed integers.
Example:
```python
from topk_sdk.data import i32_list
i32_list([0, 1, 2, 3])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[int] |
**Returns**
[`List`](#list)
***
##### i64_list()
```python
i64_list(data: list[int]) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing a list of 64-bit signed integers.
Example:
```python
from topk_sdk.data import i64_list
i64_list([0, 1, 2, 3])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[int] |
**Returns**
[`List`](#list)
***
##### f32_list()
```python
f32_list(data: list[float]) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing a list of 32-bit floating point numbers.
Example:
```python
from topk_sdk.data import f32_list
f32_list([0.12, 0.67, 0.82, 0.53])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[float] |
**Returns**
[`List`](#list)
***
##### f64_list()
```python
f64_list(data: list[float]) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing a list of 64-bit floating point numbers.
Example:
```python
from topk_sdk.data import f64_list
f64_list([0.12, 0.67, 0.82, 0.53])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[float] |
**Returns**
[`List`](#list)
***
##### string_list()
```python
string_list(data: list[str]) -> List
```
Create a [List](/sdk/topk-py/data#List) type containing a list of strings.
Example:
```python
from topk_sdk.data import string_list
string_list(["foo", "bar", "baz"])
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `data` | list[str] |
**Returns**
[`List`](#list)
***
##### struct()
```python
struct(fields: dict[str, Any]) -> Struct
```
Create a [Struct](/sdk/topk-py/data#Struct) type containing nested object values.
Example:
```python
from topk_sdk.data import struct
struct({"author": "alice", "year": 2024})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `fields` | dict[str, Any] |
**Returns**
[`Struct`](#struct)
***
##### matrix()
```python
matrix(values: list[list[float]] | list[list[int]] | numpy.ndarray, value_type: Optional[Literal['f32', 'f16', 'f8', 'u8', 'i8']] = None) -> Matrix
```
Create a [Matrix](/sdk/topk-py/data#Matrix) type containing matrix values.
The `values` parameter can be a list of lists or a [numpy array](https://numpy.org/doc/stable/reference/generated/numpy.array.html). When passing a numpy array,
the matrix type is inferred from the array's dtype (float32, float16, uint8, int8).
When passing a list of lists, the optional `value_type` parameter specifies the matrix type.
If `value_type` is not provided, the matrix defaults to f32.
```python
from topk_sdk.data import matrix
import numpy as np
### List of lists with explicit type
matrix([[1.0, 2.0, 3.0], [4.0, 5.0, 6.0]], "f32")
### List of lists defaults to f32
matrix([[1.0, 2.0], [3.0, 4.0]])
### Numpy array infers type from dtype
matrix(np.array([[1.0, 2.0], [3.0, 4.0]], dtype=np.float16))
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `values` | list[list[float]] | list[list[int]] | numpy.ndarray |
| `value_type` | Optional[Literal['f32', 'f16', 'f8', 'u8', 'i8']] |
**Returns**
[`Matrix`](#matrix)
***
### topk_sdk.error
URL: https://docs.topk.io/sdk/topk-py/error
#### Classes
##### CollectionAlreadyExistsError
Raised when creating a collection with a name that already exists.
##### CollectionNotFoundError
Raised when a collection is not found.
##### PartitionNotFoundError
Raised when a partition is not found.
##### CollectionValidationError
Raised when a collection name or schema is invalid.
##### DocumentNotFoundError
Raised when a document is not found.
##### DocumentValidationError
Raised when a document is invalid.
##### InvalidArgumentError
Raised when an invalid argument is provided.
##### PermissionDeniedError
Raised when a permission is denied.
##### QueryLsnTimeoutError
Raised when a query LSN timeout occurs.
##### QuotaExceededError
Raised when a quota is exceeded.
##### RequestTooLargeError
Raised when a request is too large.
##### SchemaValidationError
Raised when a schema is invalid.
##### SlowDownError
Raised when a slow down occurs.
### topk_sdk.query
URL: https://docs.topk.io/sdk/topk-py/query
#### Classes
##### LogicalExpr
*Internal*
Instances of the `LogicalExpr` class are used to represent logical expressions in TopK.
Usually created using logical constructors such as [`field()`](#field), [`literal()`](#literal), etc.
**Methods**
###### is\_null()
```python
is_null(self) -> LogicalExpr
```
Check if the expression is null.
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### is\_not\_null()
```python
is_not_null(self) -> LogicalExpr
```
Check if the expression is not null.
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### abs()
```python
abs(self) -> LogicalExpr
```
Compute the absolute value of the expression.
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### ln()
```python
ln(self) -> LogicalExpr
```
Compute the natural logarithm of the expression.
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### exp()
```python
exp(self) -> LogicalExpr
```
Compute the exponential of the expression.
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### sqrt()
```python
sqrt(self) -> LogicalExpr
```
Compute the square root of the expression.
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### square()
```python
square(self) -> LogicalExpr
```
Compute the square of the expression.
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### eq()
```python
eq(self, other: FlexibleExpr) -> LogicalExpr
```
Check if the expression is equal to another expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`FlexibleExpr`](#flexibleexpr) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### ne()
```python
ne(self, other: FlexibleExpr) -> LogicalExpr
```
Check if the expression is not equal to another expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`FlexibleExpr`](#flexibleexpr) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### lt()
```python
lt(self, other: Ordered) -> LogicalExpr
```
Check if the expression is less than another expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Ordered`](#ordered) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### lte()
```python
lte(self, other: Ordered) -> LogicalExpr
```
Check if the expression is less than or equal to another expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Ordered`](#ordered) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### gt()
```python
gt(self, other: Ordered) -> LogicalExpr
```
Check if the expression is greater than another expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Ordered`](#ordered) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### gte()
```python
gte(self, other: Ordered) -> LogicalExpr
```
Check if the expression is greater than or equal to another expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Ordered`](#ordered) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### add()
```python
add(self, other: Numeric) -> LogicalExpr
```
Add another value to the expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Numeric`](#numeric) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### sub()
```python
sub(self, other: Numeric) -> LogicalExpr
```
Subtract another value from the expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Numeric`](#numeric) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### mul()
```python
mul(self, other: Numeric) -> LogicalExpr
```
Multiply the expression by another value.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Numeric`](#numeric) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### div()
```python
div(self, other: Numeric) -> LogicalExpr
```
Divide the expression by another value.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Numeric`](#numeric) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### min()
```python
min(self, other: Ordered) -> LogicalExpr
```
Compute the minimum of the expression and another value.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Ordered`](#ordered) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### max()
```python
max(self, other: Ordered) -> LogicalExpr
```
Compute the maximum of the expression and another value.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Ordered`](#ordered) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### date\_part()
```python
date_part(self, part: DatePart) -> LogicalExpr
```
Extract a part of a timestamp expression as an integer.
Supported parts:
- ``"year"`` — calendar year
- ``"month"`` — 1-12
- ``"week"`` — ISO week number
- ``"day"`` — day of month, 1-31
- ``"day_of_year"`` — 1-366
- ``"day_of_week"`` — 0-6, Monday = 0
- ``"hour"`` — 0-23
- ``"minute"`` — 0-59
- ``"second"`` — 0-59
- ``"millisecond"`` — 0-999
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `part` | [`DatePart`](#datepart) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### and\_()
```python
and_(self, other: Boolish) -> LogicalExpr
```
Compute the logical AND of the expression and another expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Boolish`](#boolish) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### or\_()
```python
or_(self, other: Boolish) -> LogicalExpr
```
Compute the logical OR of the expression and another expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Boolish`](#boolish) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### starts\_with()
```python
starts_with(self, other: Stringy) -> LogicalExpr
```
Check if the expression starts with the provided string expression.
Can be applied on a string field or a list of strings field.
```python
### Example:
from topk_sdk.query import field, starts_with
client.collection("books").query(
filter(field("title").starts_with("The") | field("tags").starts_with("fiction"))
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Stringy`](#stringy) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### contains()
```python
contains(self, other: FlexibleExpr) -> LogicalExpr
```
Check if the expression contains another value.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`FlexibleExpr`](#flexibleexpr) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### in\_()
```python
in_(self, other: Iterable) -> LogicalExpr
```
Check if the expression is in the provided iterable expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Iterable`](#iterable) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### match\_all()
```python
match_all(self, other: StringyWithList) -> LogicalExpr
```
Check if the expression matches all terms against the field with keyword index.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`StringyWithList`](#stringywithlist) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### match\_any()
```python
match_any(self, other: StringyWithList) -> LogicalExpr
```
Check if the expression matches any term against the field with keyword index.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`StringyWithList`](#stringywithlist) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### coalesce()
```python
coalesce(self, other: Numeric) -> LogicalExpr
```
Coalesce nulls in the expression with another value.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `other` | [`Numeric`](#numeric) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### choose()
```python
choose(self, x: FlexibleExpr, y: FlexibleExpr) -> LogicalExpr
```
Choose between two values based on the expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `x` | [`FlexibleExpr`](#flexibleexpr) |
| `y` | [`FlexibleExpr`](#flexibleexpr) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### boost()
```python
boost(self, condition: FlexibleExpr, boost: Numeric) -> LogicalExpr
```
Multiply the scoring expression by the provided `boost` value if the `condition` is true.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `condition` | [`FlexibleExpr`](#flexibleexpr) |
| `boost` | [`Numeric`](#numeric) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### elapsed()
```python
elapsed(self, end: FlexibleExpr, interval: Interval) -> LogicalExpr
```
Compute the number of `interval` units elapsed between the expression and `end`.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `end` | [`FlexibleExpr`](#flexibleexpr) |
| `interval` | [`Interval`](#interval) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
###### regexp\_match()
```python
regexp_match(self, pattern: str, flags: Optional[str] = None) -> LogicalExpr
```
Check if the expression matches the provided regexp pattern.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `pattern` | str |
| `flags` | Optional[str] |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
##### FunctionExpr
*Internal*
Instances of the `FunctionExpr` class are used to represent function expressions in TopK.
Usually created using function constructors such as [`fn.vector_distance()`](#vector-distance), [`fn.semantic_similarity()`](#semantic-similarity) or [`fn.bm25_score()`](#bm25-score).
##### AggregateExpr
*Internal*
Instances of the `AggregateExpr` class are used to represent aggregate expressions in TopK.
Usually created using aggregate constructors such as [`agg.count()`](#count), [`agg.sum()`](#sum), [`agg.min()`](#min-2), [`agg.max()`](#max-2) or [`agg.avg()`](#avg).
##### TextExpr
*Internal*
Instances of the `TextExpr` class are used to represent text expressions in TopK.
##### Query
**Methods**
###### select()
```python
select(self) -> Query
```
Adds a select stage to the query.
**Returns**
[`Query`](#query)
***
###### filter()
```python
filter(self, expr: LogicalExpr | TextExpr) -> Query
```
Adds a filter stage to the query.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `expr` | [`LogicalExpr`](#logicalexpr) | [`TextExpr`](#textexpr) |
**Returns**
[`Query`](#query)
***
###### sort()
```python
sort(self, expr: LogicalExpr, asc: bool = True) -> Query
sort(self, expr: Sequence[tuple[LogicalExpr, Literal['asc', 'desc']]]) -> Query
```
Adds a sort stage to the query.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `expr` | [`LogicalExpr`](#logicalexpr) | Sequence[tuple[[`LogicalExpr`](#logicalexpr), Literal['asc', 'desc']]] |
| `asc` | bool |
**Returns**
[`Query`](#query)
***
###### limit()
```python
limit(self, k: int) -> Query
```
Adds a limit stage to the query.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `k` | int |
**Returns**
[`Query`](#query)
***
###### offset()
```python
offset(self, offset: int) -> Query
```
Adds an offset stage to the query.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `offset` | int |
**Returns**
[`Query`](#query)
***
###### count()
```python
count(self) -> Query
```
Adds a count stage to the query.
**Returns**
[`Query`](#query)
***
###### group\_by()
```python
group_by(self, keys: dict[str, LogicalExpr], aggs: dict[str, AggregateExpr]) -> Query
```
Adds a group-by stage to the query.
Groups documents by one or more key expressions and computes aggregations for each group.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `keys` | dict[str, [`LogicalExpr`](#logicalexpr)] |
| `aggs` | dict[str, [`AggregateExpr`](#aggregateexpr)] |
**Returns**
[`Query`](#query)
***
###### topk()
**Deprecated** — Use ``.sort(expr, asc).limit(k)`` instead.
```python
topk(self, expr: LogicalExpr, k: int, asc: bool = False) -> Query
```
Adds a top-k stage to the query.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `expr` | [`LogicalExpr`](#logicalexpr) |
| `k` | int |
| `asc` | bool |
**Returns**
[`Query`](#query)
***
##### fn
The `query.fn` submodule exposes functions for creating function expressions such as [`fn.vector_distance()`](#vector-distance), [`fn.semantic_similarity()`](#semantic-similarity) or [`fn.bm25_score()`](#bm25-score).
**Methods**
###### vector\_distance()
```python
vector_distance(
field: str,
vector: list[int] | list[float] | dict[int, float] | dict[int, int] | numpy.ndarray | topk_sdk.data.SparseVector | topk_sdk.data.List,
skip_refine: bool = False
)
```
Calculate the vector distance between a field and a query vector.
```python
### Example:
from topk_sdk.query import field, fn, select
client.collection("books").query(
select(
"title",
title_similarity=fn.vector_distance(
"title_embedding",
[0.1, 0.2, 0.3, ...] # embedding for "animal"
)
)
.sort(field("title_similarity"), asc=False).limit(10)
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `field` | str |
| `vector` | list[int] | list[float] | dict[int, float] | dict[int, int] | numpy.ndarray | [`topk_sdk.data.SparseVector`](/sdk/topk-py/data#sparsevector) | [`topk_sdk.data.List`](/sdk/topk-py/data#list) |
| `skip_refine` | bool |
**Returns**
[`FunctionExpr`](#functionexpr)
***
###### semantic\_similarity()
```python
semantic_similarity(field: str, query: str) -> FunctionExpr
```
Calculate the semantic similarity between a field and a query string.
```python
### Example:
from topk_sdk.query import field, fn, select
client.collection("books").query(
select(
"title",
title_similarity=fn.semantic_similarity("title", "animal")
)
.sort(field("title_similarity"), asc=False).limit(10)
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `field` | str |
| `query` | str |
**Returns**
[`FunctionExpr`](#functionexpr)
***
###### bm25\_score()
```python
bm25_score(b: Optional[float] = None, k1: Optional[float] = None) -> FunctionExpr
```
Calculate the BM25 score for a keyword search.
Optional parameters: b (0-1), k1 (>=0) to override BM25 scoring behavior.
```python
### Example:
from topk_sdk.query import field, fn, select
client.collection("books").query(
select(
"title",
text_score=fn.bm25_score()
)
.filter(match("animal"))
.sort(field("text_score"), asc=False).limit(10)
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `b` | Optional[float] |
| `k1` | Optional[float] |
**Returns**
[`FunctionExpr`](#functionexpr)
***
###### multi\_vector\_distance()
```python
multi_vector_distance(
field: str,
matrix: topk_sdk.data.Matrix | numpy.ndarray | list[list[float]] | list[list[int]],
candidates: Optional[int] = None
)
```
Calculate the multi-vector distance between a field and a query matrix.
The query matrix can be a list of lists (defaults to f32), a [numpy array](https://numpy.org/doc/stable/reference/generated/numpy.array.html) (type inferred from dtype),
or a [`Matrix`](/sdk/topk-py/data#Matrix) instance. To specify a different matrix type,
use [`matrix()`](/sdk/topk-py/data#matrix-2) with `value_type` or a 2-D numpy array with the
corresponding dtype.
The optional `candidates` parameter limits the number of candidate vectors considered during search.
```python
from topk_sdk.query import field, fn, select
client.collection("books").query(
select(
"title",
title_distance=fn.multi_vector_distance(
"title_embedding",
[[0.1, 0.2, 0.3, ...], [0.4, 0.5, 0.6, ...]],
candidates=100
)
)
.sort(field("title_distance"), asc=False).limit(10)
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `field` | str |
| `matrix` | [`topk_sdk.data.Matrix`](/sdk/topk-py/data#matrix) | numpy.ndarray | list[list[float]] | list[list[int]] |
| `candidates` | Optional[int] |
**Returns**
[`FunctionExpr`](#functionexpr)
***
##### agg
The `query.agg` submodule exposes functions for creating aggregate expressions used in
[`group_by()`](#group-by)'s `aggs` argument, such as [`agg.count()`](#count), [`agg.sum()`](#sum),
[`agg.min()`](#min-2), [`agg.max()`](#max-2) or [`agg.avg()`](#avg).
**Methods**
###### count()
```python
count(field: str | None = None) -> AggregateExpr
```
Count the number of documents in the group.
If `field` is provided, counts only the documents where that field is non-null.
If omitted, counts every document in the group.
```python
### Example:
from topk_sdk.query import group_by, field, agg
client.collection("books").query(
group_by(
{"is_old": field("published_year") < 1940},
{"count": agg.count()},
)
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `field` | str | None |
**Returns**
[`AggregateExpr`](#aggregateexpr)
***
###### sum()
```python
sum(field: str) -> AggregateExpr
```
Sum the values of `field` across the group.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `field` | str |
**Returns**
[`AggregateExpr`](#aggregateexpr)
***
###### min()
```python
min(field: str) -> AggregateExpr
```
Find the minimum value of `field` across the group.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `field` | str |
**Returns**
[`AggregateExpr`](#aggregateexpr)
***
###### max()
```python
max(field: str) -> AggregateExpr
```
Find the maximum value of `field` across the group.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `field` | str |
**Returns**
[`AggregateExpr`](#aggregateexpr)
***
###### avg()
```python
avg(field: str) -> AggregateExpr
```
Calculate the average value of `field` across the group.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `field` | str |
**Returns**
[`AggregateExpr`](#aggregateexpr)
***
#### Functions
##### field()
```python
field(name: str) -> LogicalExpr
```
Select a field from the document.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `name` | str |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
##### select()
```python
select() -> Query
```
Creates a new query with a select stage.
```python
### Example:
from topk_sdk.query import select, field
client.collection("books").query(
select("title", year=field("published_year"))
)
```
**Returns**
[`Query`](#query)
***
##### filter()
```python
filter(expr: LogicalExpr | TextExpr) -> Query
```
Creates a new query with a filter stage.
```python
### Example:
from topk_sdk.query import filter, field
client.collection("books").query(
filter(field("published_year") > 1980)
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `expr` | [`LogicalExpr`](#logicalexpr) | [`TextExpr`](#textexpr) |
**Returns**
[`Query`](#query)
***
##### group_by()
```python
group_by(keys: dict[str, LogicalExpr], aggs: dict[str, AggregateExpr]) -> Query
```
Creates a new query with a group-by stage.
Groups documents by one or more key expressions and computes aggregations for each group.
```python
### Example:
from topk_sdk.query import group_by, field, agg
client.collection("books").query(
group_by(
{"is_old": field("published_year") < 1940},
{"count": agg.count()},
)
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `keys` | dict[str, [`LogicalExpr`](#logicalexpr)] |
| `aggs` | dict[str, [`AggregateExpr`](#aggregateexpr)] |
**Returns**
[`Query`](#query)
***
##### literal()
```python
literal(value: Any) -> LogicalExpr
```
Create a literal expression.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `value` | Any |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
##### match()
```python
match(token: str, field: str | None = None, weight: float = 1.0, all: bool = False) -> TextExpr
```
Perform a BM25 keyword search using TopK's built-in tokenizer.
The ``token`` argument is a raw query string — TopK tokenizes it automatically,
removes stop words, and scores documents using BM25. Pass the full query string
directly; tokenization and stop-word removal happen server-side.
- ``field``: restrict matching to a specific keyword-indexed field (default: all).
- ``weight``: scale the BM25 contribution of this expression (default: 1.0).
- ``all``: if True, require all tokens to match (AND); default is any-token (OR).
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `token` | str |
| `field` | str | None |
| `weight` | float |
| `all` | bool |
**Returns**
[`TextExpr`](#textexpr)
***
##### should()
```python
should(token: str, field: str | None = None, weight: float = 1.0) -> TextExpr
```
Adds an optional BM25 scoring term without filtering documents from the result set.
Documents containing the term receive a higher BM25 score, while documents that
do not contain it remain eligible for the results. Use ``should()`` together with
``match()`` when some terms are required and others should only influence ranking.
When used on its own, ``should()`` matches the entire collection and ranks
documents according to how well they match the term.
```python
match("hobbit rings", field="title") & should("lord", field="title")
```
This returns only documents matching ``hobbit`` or ``rings``, while boosting
documents that also match ``lord``.
- ``field``: Keyword-indexed field used for scoring. Searches all eligible fields when omitted.
- ``weight``: Multiplier applied to the term's BM25 contribution. Defaults to ``1.0``.
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `token` | str |
| `field` | str | None |
| `weight` | float |
**Returns**
[`TextExpr`](#textexpr)
***
##### match_tokens()
```python
match_tokens(
tokens: Sequence[str | tuple[str, float]],
field: str | None = None,
all: bool = False
)
```
Filters documents that match the provided tokens with optional per-token weights.
Each token can be a string (with the default weight of 1.0) or a (token, weight) tuple.
When ``field`` is provided, matches only against that field (must have a keyword index).
When ``field`` is None (default), matches against all keyword-indexed fields.
When ``all`` is False (default), matches documents containing any of the tokens (OR).
When ``all`` is True, matches only documents containing all tokens (AND).
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `tokens` | Sequence[str | tuple[str, float]] |
| `field` | str | None |
| `all` | bool |
**Returns**
[`TextExpr`](#textexpr)
***
##### not_()
```python
not_(expr: LogicalExpr) -> LogicalExpr
```
Negate a logical expression.
```python
### Example:
from topk_sdk.query import field, not_
.filter(
not_(field("title").contains("Catcher"))
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `expr` | [`LogicalExpr`](#logicalexpr) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
##### abs()
```python
abs(expr: LogicalExpr) -> LogicalExpr
```
Compute the absolute value of a logical expression.
```python
### Example:
from topk_sdk.query import field, abs
client.collection("books").query(
filter(abs(field("rating")) > 4.5)
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `expr` | [`LogicalExpr`](#logicalexpr) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
##### all()
```python
all(exprs: Sequence[LogicalExpr]) -> LogicalExpr
```
Create a logical AND expression.
```python
### Example:
from topk_sdk.query import field, all
client.collection("books").query(
filter(all([
field("published_year") >= 1900,
field("published_year") <= 2000,
field("title").is_not_null()
]))
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `exprs` | Sequence[[`LogicalExpr`](#logicalexpr)] |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
##### any()
```python
any(exprs: Sequence[LogicalExpr]) -> LogicalExpr
```
Create a logical OR expression.
```python
### Example:
from topk_sdk.query import field, any
client.collection("books").query(
filter(any([
field("genre") == "fiction",
field("genre") == "mystery",
field("genre") == "thriller"
]))
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `exprs` | Sequence[[`LogicalExpr`](#logicalexpr)] |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
##### min()
```python
min(left: Ordered, right: Ordered) -> LogicalExpr
```
Create a logical MIN expression.
```python
### Example:
from topk_sdk.query import field, min
client.collection("books").query(
filter(min(field("rating"), field("published_year")))
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `left` | [`Ordered`](#ordered) |
| `right` | [`Ordered`](#ordered) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
##### max()
```python
max(left: Ordered, right: Ordered) -> LogicalExpr
```
Create a logical MAX expression.
```python
from topk_sdk.query import field, max
client.collection("books").query(
filter(max(field("rating"), field("published_year")))
)
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `left` | [`Ordered`](#ordered) |
| `right` | [`Ordered`](#ordered) |
**Returns**
[`LogicalExpr`](#logicalexpr)
***
#### Type Aliases
##### DatePart
```python
DatePart = Literal['year', 'month', 'week', 'day', 'day_of_year', 'day_of_week', 'hour', 'minute', 'second', 'millisecond']
```
**Type**
Literal['year', 'month', 'week', 'day', 'day_of_year', 'day_of_week', 'hour', 'minute', 'second', 'millisecond']
***
##### Interval
```python
Interval = Literal['millisecond', 'second', 'minute', 'hour', 'day', 'week']
```
**Type**
Literal['millisecond', 'second', 'minute', 'hour', 'day', 'week']
***
##### FlexibleExpr
```python
FlexibleExpr = str | int | float | bool | None | LogicalExpr
```
**Type**
str | int | float | bool | None | [`LogicalExpr`](#logicalexpr)
***
##### Numeric
```python
Numeric = int | float | LogicalExpr
```
**Type**
int | float | [`LogicalExpr`](#logicalexpr)
***
##### Ordered
```python
Ordered = int | float | str | LogicalExpr
```
**Type**
int | float | str | [`LogicalExpr`](#logicalexpr)
***
##### Boolish
```python
Boolish = bool | LogicalExpr
```
**Type**
bool | [`LogicalExpr`](#logicalexpr)
***
##### Stringy
```python
Stringy = str | LogicalExpr
```
**Type**
str | [`LogicalExpr`](#logicalexpr)
***
##### StringyWithList
```python
StringyWithList = str | list[str] | LogicalExpr
```
**Type**
str | list[str] | [`LogicalExpr`](#logicalexpr)
***
##### Iterable
```python
Iterable = str | list[int] | list[float] | list[str] | topk_sdk.data.List | LogicalExpr
```
**Type**
str | list[int] | list[float] | list[str] | [`topk_sdk.data.List`](/sdk/topk-py/data#list) | [`LogicalExpr`](#logicalexpr)
***
### topk_sdk.schema
URL: https://docs.topk.io/sdk/topk-py/schema
#### Classes
##### FieldIndex
*Internal*
Instances of the `FieldIndex` class represents a field index created by [`vector_index`](#vector-index), [`keyword_index`](#keyword-index), [`semantic_index`](#semantic-index), [`ngram_index`](#ngram-index), or [`multi_vector_index`](#multi-vector-index) functions.
##### FieldSpec
*Internal*
Instances of the `FieldSpec` class represents a field specification created by [`text`](#text), [`int`](#int), [`float`](#float), [`bool`](#bool), [`f32_vector`](#f32-vector), [`u8_vector`](#u8-vector), [`i8_vector`](#i8-vector), [`binary_vector`](#binary-vector), [`f32_sparse_vector`](#f32-sparse-vector), [`u8_sparse_vector`](#u8-sparse-vector), [`bytes`](#bytes), [`list`](#list), [`struct`](#struct), or [`matrix`](#matrix) functions.
**Methods**
###### required()
```python
required(self) -> FieldSpec
```
Mark a field as required. All fields are optional by default.
Example:
```python
from topk_sdk.schema import text
client.collections().create("books", schema={
"title": text().required()
})
```
**Returns**
[`FieldSpec`](#fieldspec)
***
###### optional()
```python
optional(self) -> FieldSpec
```
**Returns**
[`FieldSpec`](#fieldspec)
***
###### index()
```python
index(self, index: FieldIndex) -> FieldSpec
```
Create an index on a field.
Example:
```python
from topk_sdk.schema import text, keyword_index
client.collections().create("books", schema={
"title": text().index(keyword_index())
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `index` | [`FieldIndex`](#fieldindex) |
**Returns**
[`FieldSpec`](#fieldspec)
***
#### Functions
##### text()
```python
text() -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `text` values.
Example:
```python
from topk_sdk.schema import text
client.collections().create("books", schema={
"title": text()
})
```
**Returns**
[`FieldSpec`](#fieldspec)
***
##### int()
```python
int() -> FieldSpec
```
Create an integer field specification.
**Returns**
[`FieldSpec`](#fieldspec)
***
##### float()
```python
float() -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `float` values.
Example:
```python
from topk_sdk.schema import float
client.collections().create("books", schema={
"price": float()
})
```
**Returns**
[`FieldSpec`](#fieldspec)
***
##### bool()
```python
bool() -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `bool` values.
Example:
```python
from topk_sdk.schema import bool
client.collections().create("books", schema={
"is_published": bool()
})
```
**Returns**
[`FieldSpec`](#fieldspec)
***
##### f8_vector()
```python
f8_vector(dimension: int) -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `f8_vector` values.
Example:
```python
from topk_sdk.schema import f8_vector
client.collections().create("books", schema={
"title_embedding": f8_vector(dimension=1536)
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `dimension` | int |
**Returns**
[`FieldSpec`](#fieldspec)
***
##### f16_vector()
```python
f16_vector(dimension: int) -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `f16_vector` values.
Example:
```python
from topk_sdk.schema import f16_vector
client.collections().create("books", schema={
"title_embedding": f16_vector(dimension=1536)
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `dimension` | int |
**Returns**
[`FieldSpec`](#fieldspec)
***
##### f32_vector()
```python
f32_vector(dimension: int) -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `f32_vector` values.
Example:
```python
from topk_sdk.schema import f32_vector
client.collections().create("books", schema={
"title_embedding": f32_vector(dimension=1536)
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `dimension` | int |
**Returns**
[`FieldSpec`](#fieldspec)
***
##### u8_vector()
```python
u8_vector(dimension: int) -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `u8_vector` values.
Example:
```python
from topk_sdk.schema import u8_vector
client.collections().create("books", schema={
"title_embedding": u8_vector(dimension=1536)
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `dimension` | int |
**Returns**
[`FieldSpec`](#fieldspec)
***
##### i8_vector()
```python
i8_vector(dimension: int) -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `i8_vector` values.
Example:
```python
from topk_sdk.schema import i8_vector
client.collections().create("books", schema={
"title_embedding": i8_vector(dimension=1536)
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `dimension` | int |
**Returns**
[`FieldSpec`](#fieldspec)
***
##### binary_vector()
```python
binary_vector(dimension: int) -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `binary_vector` values.
Example:
```python
from topk_sdk.schema import binary_vector
client.collections().create("books", schema={
"title_embedding": binary_vector(dimension=128)
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `dimension` | int |
**Returns**
[`FieldSpec`](#fieldspec)
***
##### f32_sparse_vector()
```python
f32_sparse_vector() -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `f32_sparse_vector` values.
Note: Sparse vectors use u32 dimension indices to support dictionaries of up to 2^32 - 1 terms.
Example:
```python
from topk_sdk.schema import f32_sparse_vector
client.collections().create("books", schema={
"sparse_field": f32_sparse_vector()
})
```
**Returns**
[`FieldSpec`](#fieldspec)
***
##### u8_sparse_vector()
```python
u8_sparse_vector() -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `u8_sparse_vector` values.
Note: Sparse vectors use u32 dimension indices to support dictionaries of up to 2^32 - 1 terms.
Example:
```python
from topk_sdk.schema import u8_sparse_vector
client.collections().create("books", schema={
"sparse_field": u8_sparse_vector()
})
```
**Returns**
[`FieldSpec`](#fieldspec)
***
##### bytes()
```python
bytes() -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `bytes` values.
Example:
```python
from topk_sdk.schema import bytes
client.collections().create("books", schema={
"image": bytes()
})
```
**Returns**
[`FieldSpec`](#fieldspec)
***
##### timestamp()
```python
timestamp() -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `timestamp` values.
Timestamps are stored as milliseconds since UNIX epoch.
When upserting timestamps, use:
- ``datetime.datetime`` — timezone-aware datetime (timezone-naive datetimes are not supported)
- ``datetime.date`` — date (padded to midnight UTC)
- ``int`` — epoch milliseconds
Example:
```python
from topk_sdk.schema import timestamp
client.collections().create("books", schema={
"published_ts": timestamp()
})
```
**Returns**
[`FieldSpec`](#fieldspec)
***
##### list()
```python
list(value_type: Literal['text', 'integer', 'float']) -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `list` values.
Example:
```python
from topk_sdk.schema import list
client.collections().create("books", schema={
"tags": list(value_type="text")
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `value_type` | Literal['text', 'integer', 'float'] |
**Returns**
[`FieldSpec`](#fieldspec)
***
##### struct()
```python
struct(fields: Mapping[str, SchemaFieldSpec]) -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `struct` values.
Example:
```python
from topk_sdk.schema import int, struct, text
client.collections().create("books", schema={
"meta": struct({"author": text(), "year": int()})
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `fields` | Mapping[str, [`SchemaFieldSpec`](#schemafieldspec)] |
**Returns**
[`FieldSpec`](#fieldspec)
***
##### matrix()
```python
matrix(dimension: int, value_type: Literal['f32', 'f16', 'f8', 'u8', 'i8']) -> FieldSpec
```
Create a [FieldSpec](/sdk/topk-py/schema#FieldSpec) type for `matrix` values.
Supported `value_type`s:
- `f32`
- `f16`
- `f8`
- `u8`
- `i8`
Example:
```python
from topk_sdk.schema import matrix
client.collections().create("books", schema={
"title_embedding": matrix(dimension=1536, value_type="f32")
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `dimension` | int |
| `value_type` | Literal['f32', 'f16', 'f8', 'u8', 'i8'] |
**Returns**
[`FieldSpec`](#fieldspec)
***
##### vector_index()
```python
vector_index(metric: Literal['cosine', 'euclidean', 'dot_product', 'hamming']) -> FieldIndex
```
Create a [FieldIndex](/sdk/topk-py/schema#FieldIndex) type for `vector_index` values.
Supported `metric`s:
- `euclidean` (only dense vectors)
- `cosine` (only dense vectors)
- `dot_product` (dense and sparse vectors)
- `hamming` (only binary vectors)
Example:
```python
from topk_sdk.schema import f32_vector, vector_index
client.collections().create("books", schema={
"title_embedding": f32_vector(dimension=1536).index(vector_index(metric="cosine"))
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `metric` | Literal['cosine', 'euclidean', 'dot_product', 'hamming'] |
**Returns**
[`FieldIndex`](#fieldindex)
***
##### keyword_index()
```python
keyword_index(type: Literal['text', 'exact'] = "text") -> FieldIndex
```
Create a [FieldIndex](/sdk/topk-py/schema#FieldIndex) type for `keyword_index` values.
Supported index `type`s:
- `text` (default) - text is tokenized before indexing
- `exact` - text is indexed as a single term
Example:
```python
from topk_sdk.schema import text, keyword_index
client.collections().create("books", schema={
"title": text().index(keyword_index())
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `type` | Literal['text', 'exact'] |
**Returns**
[`FieldIndex`](#fieldindex)
***
##### semantic_index()
```python
semantic_index() -> FieldIndex
```
Create a [FieldIndex](/sdk/topk-py/schema#FieldIndex) type for `semantic_index` values.
Example:
```python
from topk_sdk.schema import text, semantic_index
client.collections().create("books", schema={
"title": text().index(semantic_index())
})
```
**Returns**
[`FieldIndex`](#fieldindex)
***
##### ngram_index()
```python
ngram_index() -> FieldIndex
```
Create a [FieldIndex](/sdk/topk-py/schema#FieldIndex) type for `ngram_index` values.
Example:
```python
from topk_sdk.schema import text, ngram_index
client.collections().create("books", schema={
"title": text().index(ngram_index())
})
```
**Returns**
[`FieldIndex`](#fieldindex)
***
##### multi_vector_index()
```python
multi_vector_index(
metric: Literal['maxsim'],
quantization: Optional[Literal['1bit', '2bit', 'scalar']] = None,
width: Optional[int] = None,
top_k: Optional[int] = None
)
```
Create a [FieldIndex](/sdk/topk-py/schema#FieldIndex) type for `multi_vector_index` values.
Supported `metric`s:
- `maxsim`
Example:
```python
from topk_sdk.schema import matrix, multi_vector_index
client.collections().create("books", schema={
"title_embedding": matrix(dimension=1536, value_type="f32").index(multi_vector_index(metric="maxsim"))
})
```
**Parameters**
| Parameter | Type |
| --------- | ---- |
| `metric` | Literal['maxsim'] |
| `quantization` | Optional[Literal['1bit', '2bit', 'scalar']] |
| `width` | Optional[int] |
| `top_k` | Optional[int] |
**Returns**
[`FieldIndex`](#fieldindex)
***
#### Type Aliases
##### SchemaFieldSpec
```python
SchemaFieldSpec = FieldSpec | Mapping[str, 'SchemaFieldSpec']
```
**Type**
[`FieldSpec`](#fieldspec) | Mapping[str, 'SchemaFieldSpec']
***
## JavaScript SDK Reference
### topk-js
URL: https://docs.topk.io/sdk/topk-js
#### Classes
##### Client
Client for interacting with the TopK API. For available regions see https://docs.topk.io/regions
**Constructors**
**Constructor**
```ts
new Client(config: ClientConfig): Client;
```
Creates a new TopK client with the provided configuration.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `config` | [`ClientConfig`](/sdk/topk-js/index#clientconfig) |
**Returns**
[`Client`](/sdk/topk-js/index#client)
**Methods**
###### collection()
```ts
collection(name: string, partition?: string): CollectionClient;
```
Returns a client for interacting with a specific collection.
Optionally, pass partition name to scope data operations to that partition.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `name` | `string` |
| `partition?` | `string` |
**Returns**
[`CollectionClient`](/sdk/topk-js/index#collectionclient)
###### collections()
```ts
collections(): CollectionsClient;
```
Returns a client for managing collections.
This method provides access to collection management operations like creating,
listing, and deleting collections.
**Returns**
[`CollectionsClient`](/sdk/topk-js/index#collectionsclient)
***
##### CollectionClient
**`Internal`**
Client for interacting with a specific collection.
This client provides methods to perform operations on a specific collection,
including querying, upserting, and deleting documents.
**Methods**
###### count()
```ts
count(options?: QueryOptions): Promise;
```
Counts the number of documents in the collection.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `options?` | [`QueryOptions`](/sdk/topk-js/index#queryoptions) |
**Returns**
`Promise`\<`number`\>
###### delete()
```ts
delete(expr:
| string[]
| LogicalExpression): Promise;
```
Deletes documents from the collection by their IDs or using a filter expression.
Example:
Delete documents by their IDs:
```javascript
await client.collection("books").delete(["id_1", "id_2"])
```
Delete documents by a filter expression:
```javascript
import { field } from "topk-js/query";
await client.collection("books").delete(field("published_year").gt(1997))
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `expr` | \| `string`[] \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
`Promise`\<`string`\>
###### deletePartition()
```ts
deletePartition(name: string): Promise;
```
Delete a partition and all documents within it.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `name` | `string` |
**Returns**
`Promise`\<`void`\>
###### get()
```ts
get(
ids: string[],
fields?: string[],
options?: QueryOptions): Promise>>;
```
Retrieves documents by their IDs.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `ids` | `string`[] |
| `fields?` | `string`[] |
| `options?` | [`QueryOptions`](/sdk/topk-js/index#queryoptions) |
**Returns**
`Promise`\<`Record`\<`string`, `Record`\<`string`, `any`\>\>\>
###### listPartitions()
```ts
listPartitions(prefix?: string): PartitionListStream;
```
List partitions in the collection as an async iterator.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `prefix?` | `string` |
**Returns**
[`PartitionListStream`](/sdk/topk-js/index#partitionliststream)
###### query()
```ts
query(query: Query, options?: QueryOptions): Promise[]>;
```
Executes a query against the collection.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `query` | [`Query`](/sdk/topk-js/Namespace.query#query) |
| `options?` | [`QueryOptions`](/sdk/topk-js/index#queryoptions) |
**Returns**
`Promise`\<`Record`\<`string`, `any`\>[]\>
###### update()
```ts
update(docs: Record[], failOnMissing?: boolean): Promise;
```
Updates documents in the collection.
Existing documents will be merged with the provided fields.
Missing documents will be ignored.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `docs` | `Record`\<`string`, `any`\>[] |
| `failOnMissing?` | `boolean` |
**Returns**
`Promise`\<`string`\>
The `LSN` at which the update was applied.
If no updates were applied, this will be empty.
###### upsert()
```ts
upsert(docs: Record[]): Promise;
```
Inserts or updates documents in the collection.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `docs` | `Record`\<`string`, `any`\>[] |
**Returns**
`Promise`\<`string`\>
***
##### CollectionsClient
**`Internal`**
Client for managing collections.
This client provides methods to create, list, get, and delete collections.
**Methods**
###### create()
```ts
create(name: string, schema: Record): Promise;
```
Creates a new collection with the specified schema.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `name` | `string` |
| `schema` | `Record`\<`string`, [`SchemaFieldSpec`](/sdk/topk-js/index#schemafieldspec)\> |
**Returns**
`Promise`\<[`Collection`](/sdk/topk-js/index#collection-1)\>
###### delete()
```ts
delete(name: string): Promise;
```
Deletes a collection and all its data.
This operation is irreversible and will permanently delete all data in the collection.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `name` | `string` |
**Returns**
`Promise`\<`void`\>
###### get()
```ts
get(name: string): Promise;
```
Retrieves information about a specific collection.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `name` | `string` |
**Returns**
`Promise`\<[`Collection`](/sdk/topk-js/index#collection-1)\>
###### list()
```ts
list(): Promise;
```
Lists all collections in the current project.
**Returns**
`Promise`\<[`Collection`](/sdk/topk-js/index#collection-1)[]\>
***
##### PartitionListStream
Iterator for partition list responses.
This type implements JavaScript's async iterable protocol.
It can be used with `for await...of` loops.
**See**
https://developer.mozilla.org/en-US/docs/Web/JavaScript/Reference/Iteration_protocols#the_async_iterator_and_async_iterable_protocols
**Constructors**
**Constructor**
```ts
new PartitionListStream(): PartitionListStream;
```
**Returns**
[`PartitionListStream`](/sdk/topk-js/index#partitionliststream)
**Methods**
###### \[asyncIterator\]()
```ts
asyncIterator: AsyncGenerator;
```
**Returns**
`AsyncGenerator`\<[`Partition`](/sdk/topk-js/index#partition), `void`, `undefined`\>
###### next()
```ts
next(): Promise;
```
Returns the next partition in the stream.
**Returns**
`Promise`\<[`Partition`](/sdk/topk-js/index#partition)\>
#### Interfaces
##### BackoffConfig
Configuration for exponential backoff between retry attempts.
This struct controls how the delay between retry attempts increases over time.
All fields are optional and will use sensible defaults if not provided.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `base?` | `number` | Base multiplier for exponential backoff (default: 2.0) |
| `initBackoff?` | `number` | Initial delay before the first retry in milliseconds |
| `maxBackoff?` | `number` | Maximum delay between retries in milliseconds |
***
##### ClientConfig
Configuration for the TopK client.
This struct contains all the necessary configuration options to connect to the TopK API.
The `api_key` and `region` are required, while other options have sensible defaults.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `apiKey` | `string` | Your TopK API key for authentication |
| `host?` | `string` | Custom host URL (optional, defaults to the standard TopK endpoint) |
| `https?` | `boolean` | Whether to use HTTPS (optional, defaults to true) |
| `region` | `string` | The region where your data is stored. For available regions see: https://docs.topk.io/regions. |
| `retryConfig?` | [`RetryConfig`](/sdk/topk-js/index#retryconfig) | Retry configuration for failed requests (optional) |
***
##### Collection
Represents a collection in the TopK service.
A collection is a container for documents with a defined schema.
This struct contains metadata about the collection including its name,
organization, project, schema, and region.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `createdAt` | `string` | Timestamp when the collection was created (ISO 8601) |
| `name` | `string` | Name of the collection |
| `orgId` | `string` | Organization ID that owns the collection |
| `projectId` | `string` | Project ID that contains the collection |
| `region` | `string` | Region where the collection is stored |
| `schema` | `Record`\<`string`, [`CollectionFieldSpec`](/sdk/topk-js/index#collectionfieldspec)\> | Schema definition for the collection fields |
***
##### CollectionFieldSpec
Represents a field specification within a collection schema.
This struct defines the properties of a field in a collection,
including its data type, whether it's required, and any index configuration.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `dataType` | `DataType` | Data type of the field |
| `index?` | `FieldIndexUnion` | Index configuration for the field (optional) |
| `required` | `boolean` | Whether the field is required (must be present in all documents) |
***
##### Partition
A partition within a collection.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `createdAt` | `string` | RFC3339 created_at timestamp |
| `name` | `string` | Partition name |
***
##### QueryOptions
Options for query operations.
These options control the behavior of query operations, including consistency
guarantees and sequence number constraints.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `consistency?` | [`ConsistencyLevel`](/sdk/topk-js/index#consistencylevel) | Consistency level for the query |
| `lsn?` | `string` | Last sequence number to query at (for consistency) |
***
##### RetryConfig
Configuration for retry behavior when requests fail.
This struct allows you to customize how the client handles retries for failed requests.
All fields are optional and will use sensible defaults if not provided.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `backoff?` | [`BackoffConfig`](/sdk/topk-js/index#backoffconfig) | Backoff configuration for spacing out retry attempts |
| `maxRetries?` | `number` | Maximum number of retries to attempt before giving up |
| `timeout?` | `number` | Total timeout for the entire retry chain in milliseconds |
#### Namespaces
- [data](/sdk/topk-js/Namespace.data)
- [query](/sdk/topk-js/Namespace.query)
- [query\_agg](/sdk/topk-js/Namespace.query_agg)
- [query\_fn](/sdk/topk-js/Namespace.query_fn)
- [schema](/sdk/topk-js/Namespace.schema)
#### Type Aliases
##### ConsistencyLevel
```ts
type ConsistencyLevel = "indexed" | "strong";
```
Consistency levels for query operations.
- `Indexed`: Query returns results as soon as they are indexed (faster, eventual consistency)
- `Strong`: Query waits for all replicas to be consistent (slower, strong consistency)
***
##### SchemaFieldSpec
```ts
type SchemaFieldSpec =
| FieldSpec
| {
[field: string]: SchemaFieldSpec;
};
```
### topk-js/data
URL: https://docs.topk.io/sdk/topk-js/Namespace.data
[topk-js](/sdk/topk-js/index) / data
#### Functions
##### binaryVector()
```ts
function binaryVector(values: number[]): List;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing a binary vector. This function is an alias for [binaryList()](https://docs.topk.io/sdk/topk-js/data#binarylist).
Example:
```javascript
import { binaryVector } from "topk-js/data";
binaryVector([0, 1, 1, 0])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `number`[] |
**Returns**
[`List`](/sdk/topk-js/Namespace.data#list)
***
##### bytes()
```ts
function bytes(buffer: number[] | Buffer): Buffer;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing bytes data.
Example:
```javascript
import { bytes } from "topk-js/data";
bytes([0, 1, 1, 0])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `buffer` | `number`[] \| `Buffer`\<`ArrayBufferLike`\> |
**Returns**
`Buffer`
***
##### f16Vector()
```ts
function f16Vector(values: number[]): List;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing a 16-bit float vector.
Example:
```javascript
import { f16Vector } from "topk-js/data";
f16Vector([0.12, 0.67, 0.82, 0.53])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `number`[] |
**Returns**
[`List`](/sdk/topk-js/Namespace.data#list)
***
##### f32List()
```ts
function f32List(values: number[]): List;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing a list of 32-bit floating point numbers.
Example:
```javascript
import { f32List } from "topk-js/data";
f32List([0.12, 0.67, 0.82, 0.53])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `number`[] |
**Returns**
[`List`](/sdk/topk-js/Namespace.data#list)
***
##### f32SparseVector()
```ts
function f32SparseVector(vector: Record): SparseVector;
```
Creates a [SparseVector](https://docs.topk.io/sdk/topk-js/data#SparseVector) type containing a sparse vector of 32-bit floats. This function is an alias for [f32SparseList()](https://docs.topk.io/sdk/topk-js/data#f32sparselist).
Example:
```javascript
import { f32SparseVector } from "topk-js/data";
f32SparseVector({0: 0.12, 6: 0.67, 17: 0.82, 97: 0.53})
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `vector` | `Record`\<`number`, `number`\> |
**Returns**
[`SparseVector`](/sdk/topk-js/Namespace.data#sparsevector)
***
##### f32Vector()
```ts
function f32Vector(values: number[]): List;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing a 32-bit float vector. This function is an alias for [f32List()](https://docs.topk.io/sdk/topk-js/data#f32list).
Example:
```javascript
import { f32Vector } from "topk-js/data";
f32Vector([0.12, 0.67, 0.82, 0.53])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `number`[] |
**Returns**
[`List`](/sdk/topk-js/Namespace.data#list)
***
##### f64List()
```ts
function f64List(values: number[]): List;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing a list of 64-bit floating point numbers.
Example:
```javascript
import { f64List } from "topk-js/data";
f64List([0.12, 0.67, 0.82, 0.53])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `number`[] |
**Returns**
[`List`](/sdk/topk-js/Namespace.data#list)
***
##### f8Vector()
```ts
function f8Vector(values: number[]): List;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing an 8-bit float vector.
Example:
```javascript
import { f8Vector } from "topk-js/data";
f8Vector([0.12, 0.67, 0.82, 0.53])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `number`[] |
**Returns**
[`List`](/sdk/topk-js/Namespace.data#list)
***
##### i32List()
```ts
function i32List(values: number[]): List;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing a list of 32-bit signed integers.
Example:
```javascript
import { i32List } from "topk-js/data";
i32List([0, 1, 2, 3])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `number`[] |
**Returns**
[`List`](/sdk/topk-js/Namespace.data#list)
***
##### i64List()
```ts
function i64List(values: number[]): List;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing a list of 64-bit signed integers.
Example:
```javascript
import { i64List } from "topk-js/data";
i64List([0, 1, 2, 3])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `number`[] |
**Returns**
[`List`](/sdk/topk-js/Namespace.data#list)
***
##### i8Vector()
```ts
function i8Vector(values: number[]): List;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing an 8-bit signed integer vector. This function is an alias for [i8List()](https://docs.topk.io/sdk/topk-js/data#i8list).
Example:
```javascript
import { i8Vector } from "topk-js/data";
i8Vector([-128, 127, -1, 0, 1])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `number`[] |
**Returns**
[`List`](/sdk/topk-js/Namespace.data#list)
***
##### matrix()
```ts
function matrix(values: number[][], valueType?: MatrixValueType): Matrix;
```
Create a [Matrix](https://docs.topk.io/sdk/topk-js/data#Matrix) type containing matrix values.
The `values` parameter must be an array of number arrays. When passing an array of number arrays,
the optional `valueType` parameter specifies the matrix type.
If `valueType` is not provided, the matrix defaults to f32.
```javascript
import { matrix } from "topk-js/data";
// Array of number arrays with explicit type
matrix([[1.0, 2.0, 3.0], [4.0, 5.0, 6.0]], "f32")
// Array of number arrays defaults to f32
matrix([[1.0, 2.0], [3.0, 4.0]])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `number`[][] |
| `valueType?` | [`MatrixValueType`](/sdk/topk-js/Namespace.data#matrixvaluetype) |
**Returns**
[`Matrix`](/sdk/topk-js/Namespace.data#matrix)
***
##### stringList()
```ts
function stringList(values: string[]): List;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing a list of strings.
Example:
```javascript
import { stringList } from "topk-js/data";
stringList(["foo", "bar", "baz"])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `string`[] |
**Returns**
[`List`](/sdk/topk-js/Namespace.data#list)
***
##### struct()
```ts
function struct(fields: Record): Struct;
```
Creates a [Struct](https://docs.topk.io/sdk/topk-js/data#Struct) type containing nested object values.
Example:
```javascript
import { struct } from "topk-js/data";
struct({ author: "alice", year: 2024 })
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `fields` | `Record`\<`string`, `any`\> |
**Returns**
[`Struct`](/sdk/topk-js/Namespace.data#struct)
***
##### u32List()
```ts
function u32List(values: number[]): List;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing a list of 32-bit unsigned integers.
Example:
```javascript
import { u32List } from "topk-js/data";
u32List([0, 1, 2, 3])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `number`[] |
**Returns**
[`List`](/sdk/topk-js/Namespace.data#list)
***
##### u8SparseVector()
```ts
function u8SparseVector(vector: Record): SparseVector;
```
Creates a [SparseVector](https://docs.topk.io/sdk/topk-js/data#SparseVector) type containing a sparse vector of 8-bit unsigned integers. This function is an alias for [u8SparseList()](https://docs.topk.io/sdk/topk-js/data#u8sparselist).
Example:
```javascript
import { u8SparseVector } from "topk-js/data";
u8SparseVector({0: 12, 6: 67, 17: 82, 97: 53})
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `vector` | `Record`\<`number`, `number`\> |
**Returns**
[`SparseVector`](/sdk/topk-js/Namespace.data#sparsevector)
***
##### u8Vector()
```ts
function u8Vector(values: number[]): List;
```
Creates a [List](https://docs.topk.io/sdk/topk-js/data#List) type containing an 8-bit unsigned integer vector. This function is an alias for [u8List()](https://docs.topk.io/sdk/topk-js/data#u8list).
Example:
```javascript
import { u8Vector } from "topk-js/data";
u8Vector([0, 255, 1, 2, 3])
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `values` | `number`[] |
**Returns**
[`List`](/sdk/topk-js/Namespace.data#list)
#### Classes
##### List
**`Internal`**
Instances of the `List` class are used to represent lists of values in TopK.
Usually created using data constructors such as [`f32_list()`](#f32list), [`i32_list()`](#i32list), etc.
***
##### Matrix
**`Internal`**
Instances of the `Matrix` class are used to represent matrices in TopK.
Usually created using data constructors such as [`matrix()`](#matrix).
***
##### SparseVector
**`Internal`**
Instances of the `SparseVector` class are used to represent sparse vectors in TopK.
Usually created using data constructors such as [`f32_sparse_vector()`](#f32sparsevector) or [`u8_sparse_vector()`](#u8sparsevector).
***
##### Struct
**`Internal`**
Instances of the `Struct` class are used to represent nested object values in TopK.
Usually created using the [`struct()`](https://docs.topk.io/sdk/topk-js/data#struct-2) helper.
***
##### UnknownValue
**`Internal`**
Placeholder for a value this version of the SDK cannot represent.
#### Type Aliases
##### MatrixValueType
```ts
type MatrixValueType = "f32" | "f16" | "f8" | "u8" | "i8";
```
Matrix element value type.
### topk-js/query_fn
URL: https://docs.topk.io/sdk/topk-js/Namespace.query_fn
[topk-js](/sdk/topk-js/index) / query\_fn
#### Functions
##### bm25Score()
```ts
function bm25Score(options?: Bm25ScoreOptions): FunctionExpression;
```
Computes the BM25 score for a keyword search.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `options?` | [`Bm25ScoreOptions`](/sdk/topk-js/Namespace.query_fn#bm25scoreoptions) |
**Returns**
[`FunctionExpression`](/sdk/topk-js/Namespace.query#functionexpression)
***
##### multiVectorDistance()
```ts
function multiVectorDistance(
field: string,
query: Matrix | number[][],
candidates?: number): FunctionExpression;
```
Calculate the multi-vector distance between a field and a query matrix.
The query matrix can be an array of number arrays (defaults to f32),
or a [`Matrix`](https://docs.topk.io/sdk/topk-js/data#Matrix) instance. To specify a different matrix type,
use [`matrix()`](https://docs.topk.io/sdk/topk-js/data#matrix) with `valueType`.
The optional `candidates` parameter limits the number of candidate vectors considered during retrieval.
```javascript
import { field, fn, select } from "topk-js/query";
client.collection("books").query(
select({
title: field("title"),
title_distance: fn.multiVectorDistance(
"title_embedding",
[[0.1, 0.2, 0.3, ...], [0.4, 0.5, 0.6, ...]],
100
)
})
.sort(field("title_distance"), false).limit(10)
)
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `field` | `string` |
| `query` | [`Matrix`](/sdk/topk-js/Namespace.data#matrix) \| `number`[][] |
| `candidates?` | `number` |
**Returns**
[`FunctionExpression`](/sdk/topk-js/Namespace.query#functionexpression)
***
##### semanticSimilarity()
```ts
function semanticSimilarity(field: string, query: string): FunctionExpression;
```
Computes the semantic similarity between a field and a query string.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `field` | `string` |
| `query` | `string` |
**Returns**
[`FunctionExpression`](/sdk/topk-js/Namespace.query#functionexpression)
***
##### vectorDistance()
```ts
function vectorDistance(
field: string,
query:
| number[]
| List
| SparseVector
| Record,
options?: VectorDistanceOptions): FunctionExpression;
```
Computes the vector distance between a field and a query vector.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `field` | `string` |
| `query` | \| `number`[] \| [`List`](/sdk/topk-js/Namespace.data#list) \| [`SparseVector`](/sdk/topk-js/Namespace.data#sparsevector) \| `Record`\<`number`, `number`\> |
| `options?` | [`VectorDistanceOptions`](/sdk/topk-js/Namespace.query_fn#vectordistanceoptions) |
**Returns**
[`FunctionExpression`](/sdk/topk-js/Namespace.query#functionexpression)
#### Interfaces
##### Bm25ScoreOptions
Options for BM25 scoring.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `b?` | `number` | BM25 parameter b (0-1) |
| `k1?` | `number` | BM25 parameter k1 (>= 0) |
***
##### VectorDistanceOptions
**Properties**
| Property | Type |
| ------ | ------ |
| `skipRefine?` | `boolean` |
### topk-js/query_agg
URL: https://docs.topk.io/sdk/topk-js/Namespace.query_agg
[topk-js](/sdk/topk-js/index) / query\_agg
#### Functions
##### avg()
```ts
function avg(field: string): AggregateExpression;
```
Calculate the average value of the given field.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `field` | `string` |
**Returns**
[`AggregateExpression`](/sdk/topk-js/Namespace.query#aggregateexpression)
***
##### count()
```ts
function count(field?: string): AggregateExpression;
```
Count the number of non-null values for the given field.
If not provided, count the number of rows in the input.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `field?` | `string` |
**Returns**
[`AggregateExpression`](/sdk/topk-js/Namespace.query#aggregateexpression)
***
##### max()
```ts
function max(field: string): AggregateExpression;
```
Find the maximum value of the given field.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `field` | `string` |
**Returns**
[`AggregateExpression`](/sdk/topk-js/Namespace.query#aggregateexpression)
***
##### min()
```ts
function min(field: string): AggregateExpression;
```
Find the minimum value of the given field.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `field` | `string` |
**Returns**
[`AggregateExpression`](/sdk/topk-js/Namespace.query#aggregateexpression)
***
##### sum()
```ts
function sum(field: string): AggregateExpression;
```
Sum the values of the given field.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `field` | `string` |
**Returns**
[`AggregateExpression`](/sdk/topk-js/Namespace.query#aggregateexpression)
### topk-js/query
URL: https://docs.topk.io/sdk/topk-js/Namespace.query
[topk-js](/sdk/topk-js/index) / query
#### Functions
##### abs()
```ts
function abs(expr: LogicalExpression): LogicalExpression;
```
Creates an absolute value expression.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `expr` | [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
***
##### all()
```ts
function all(exprs: LogicalExpression[]): LogicalExpression;
```
Evaluates to true if each `expr` is true.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `exprs` | [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)[] |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
***
##### any()
```ts
function any(exprs: LogicalExpression[]): LogicalExpression;
```
Evaluates to true if at least one `expr` is true.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `exprs` | [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)[] |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
***
##### field()
```ts
function field(name: string): LogicalExpression;
```
Creates a field reference expression.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `name` | `string` |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
***
##### filter()
```ts
function filter(expr:
| LogicalExpression
| TextExpression): Query;
```
Creates a new query with a filter stage.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `expr` | \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) \| [`TextExpression`](/sdk/topk-js/Namespace.query#textexpression) |
**Returns**
[`Query`](/sdk/topk-js/Namespace.query#query)
***
##### groupBy()
```ts
function groupBy(keys: Record, aggs: Record): Query;
```
Creates a new query with a group-by stage.
Groups documents by one or more key expressions and computes aggregations for each group.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `keys` | `Record`\<`string`, [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)\> |
| `aggs` | `Record`\<`string`, [`AggregateExpression`](/sdk/topk-js/Namespace.query#aggregateexpression)\> |
**Returns**
[`Query`](/sdk/topk-js/Namespace.query#query)
***
##### literal()
```ts
function literal(value:
| string
| number
| boolean
| string[]
| number[]
| Date
| List): LogicalExpression;
```
Creates a literal value expression.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `value` | \| `string` \| `number` \| `boolean` \| `string`[] \| `number`[] \| `Date` \| [`List`](/sdk/topk-js/Namespace.data#list) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
***
##### match()
```ts
function match(token: string, options?: MatchOptions): TextExpression;
```
Perform a BM25 keyword search using TopK's built-in tokenizer.
The `token` argument is a raw query string — TopK tokenizes it automatically,
removes stop words, and scores documents using BM25. Pass the full query string
directly; tokenization and stop-word removal happen server-side.
- `options.field`: restrict matching to a specific keyword-indexed field (default: all).
- `options.weight`: scale the BM25 contribution of this expression (default: 1.0).
- `options.all`: if true, require all tokens to match (AND); default is any-token (OR).
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `token` | `string` |
| `options?` | [`MatchOptions`](/sdk/topk-js/Namespace.query#matchoptions) |
**Returns**
[`TextExpression`](/sdk/topk-js/Namespace.query#textexpression)
***
##### matchTokens()
```ts
function matchTokens(tokens: (
| string
| MatchTokenInput)[], options?: MatchTokensOptions): TextExpression;
```
Creates a text match expression from multiple tokens with optional per-token weights.
Each token can be a string (with the default weight of 1.0) or a `MatchTokenInput` object.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `tokens` | ( \| `string` \| [`MatchTokenInput`](/sdk/topk-js/Namespace.query#matchtokeninput))[] |
| `options?` | [`MatchTokensOptions`](/sdk/topk-js/Namespace.query#matchtokensoptions) |
**Returns**
[`TextExpression`](/sdk/topk-js/Namespace.query#textexpression)
***
##### max()
```ts
function max(left:
| string
| number
| LogicalExpression, right:
| string
| number
| LogicalExpression): LogicalExpression;
```
Creates a MAX expression that returns the larger of two values.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `left` | \| `string` \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
| `right` | \| `string` \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
***
##### min()
```ts
function min(left:
| string
| number
| LogicalExpression, right:
| string
| number
| LogicalExpression): LogicalExpression;
```
Creates a MIN expression that returns the smaller of two values.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `left` | \| `string` \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
| `right` | \| `string` \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
***
##### not()
```ts
function not(expr: LogicalExpression): LogicalExpression;
```
Creates a logical NOT expression.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `expr` | [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
***
##### select()
```ts
function select(exprs: Record): Query;
```
Creates a new query with a select stage.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `exprs` | `Record`\<`string`, \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) \| [`FunctionExpression`](/sdk/topk-js/Namespace.query#functionexpression)\> |
**Returns**
[`Query`](/sdk/topk-js/Namespace.query#query)
***
##### should()
```ts
function should(token: string, options?: ShouldOptions): TextExpression;
```
Adds an optional BM25 scoring term without filtering documents from the result set.
Documents containing the term receive a higher BM25 score, while documents that
do not contain it remain eligible for the results. Use `should()` together with
`match()` when some terms are required and others should only influence ranking.
When used on its own, `should()` matches the entire collection and ranks
documents according to how well they match the term.
```js
match("hobbit rings", { field: "title" }).and(should("lord", { field: "title" }))
```
This returns only documents matching `hobbit` or `rings`, while boosting
documents that also match `lord`.
- `options.field`: Keyword-indexed field used for scoring. Searches all eligible fields when omitted.
- `options.weight`: Multiplier applied to the term's BM25 contribution. Defaults to `1.0`.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `token` | `string` |
| `options?` | [`ShouldOptions`](/sdk/topk-js/Namespace.query#shouldoptions) |
**Returns**
[`TextExpression`](/sdk/topk-js/Namespace.query#textexpression)
#### Classes
##### AggregateExpression
**`Internal`**
***
##### FunctionExpression
**`Internal`**
***
##### LogicalExpression
**`Internal`**
**Methods**
###### abs()
```ts
abs(): LogicalExpression;
```
Computes the absolute value of the expression.
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### add()
```ts
add(other:
| number
| LogicalExpression): LogicalExpression;
```
Adds another value to the expression.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### and()
```ts
and(other:
| boolean
| LogicalExpression): LogicalExpression;
```
Computes the logical AND of the expression and another expression.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `boolean` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### boost()
```ts
boost(condition:
| boolean
| LogicalExpression, boost:
| number
| LogicalExpression): LogicalExpression;
```
Multiplies the scoring expression by the provided `boost` value if the `condition` is true.
Otherwise, the scoring expression is unchanged (multiplied by 1).
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `condition` | \| `boolean` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
| `boost` | \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### choose()
```ts
choose(x:
| string
| number
| boolean
| LogicalExpression, y:
| string
| number
| boolean
| LogicalExpression): LogicalExpression;
```
Chooses between two values based on the expression.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `x` | \| `string` \| `number` \| `boolean` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
| `y` | \| `string` \| `number` \| `boolean` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### coalesce()
```ts
coalesce(other:
| number
| LogicalExpression): LogicalExpression;
```
Coalesces nulls in the expression with another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### contains()
```ts
contains(other:
| string
| number
| LogicalExpression): LogicalExpression;
```
Checks if the expression contains another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### datePart()
```ts
datePart(part: DatePart): LogicalExpression;
```
Extracts a part of a timestamp expression as an integer.
Supported parts:
- `"year"` — calendar year
- `"month"` — 1-12
- `"week"` — ISO week number
- `"day"` — day of month, 1-31
- `"day_of_year"` — 1-366
- `"day_of_week"` — 0-6, Monday = 0
- `"hour"` — 0-23
- `"minute"` — 0-59
- `"second"` — 0-59
- `"millisecond"` — 0-999
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `part` | [`DatePart`](/sdk/topk-js/Namespace.query#datepart-1) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### div()
```ts
div(other:
| number
| LogicalExpression): LogicalExpression;
```
Divides the expression by another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### elapsed()
```ts
elapsed(end:
| number
| LogicalExpression, interval: Interval): LogicalExpression;
```
Computes the number of `interval` units elapsed between the expression and `end`.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `end` | \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
| `interval` | [`Interval`](/sdk/topk-js/Namespace.query#interval) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### eq()
```ts
eq(other:
| string
| number
| boolean
| LogicalExpression): LogicalExpression;
```
Checks if the expression equals another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| `number` \| `boolean` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### exp()
```ts
exp(): LogicalExpression;
```
Computes the exponential of the expression.
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### gt()
```ts
gt(other:
| string
| number
| LogicalExpression): LogicalExpression;
```
Checks if the expression is greater than another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### gte()
```ts
gte(other:
| string
| number
| LogicalExpression): LogicalExpression;
```
Checks if the expression is greater than or equal to another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### in()
```ts
in(other:
| string
| string[]
| number[]
| LogicalExpression
| List): LogicalExpression;
```
Checks if the expression is in another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| `string`[] \| `number`[] \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) \| [`List`](/sdk/topk-js/Namespace.data#list) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### isNotNull()
```ts
isNotNull(): LogicalExpression;
```
Checks if the expression evaluates to a non-null value.
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### isNull()
```ts
isNull(): LogicalExpression;
```
Checks if the expression evaluates to null.
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### ln()
```ts
ln(): LogicalExpression;
```
Computes the natural logarithm of the expression.
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### lt()
```ts
lt(other:
| string
| number
| LogicalExpression): LogicalExpression;
```
Checks if the expression is less than another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### lte()
```ts
lte(other:
| string
| number
| LogicalExpression): LogicalExpression;
```
Checks if the expression is less than or equal to another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### matchAll()
```ts
matchAll(other:
| string
| string[]
| LogicalExpression): LogicalExpression;
```
Checks if the expression matches all terms against the field with keyword index.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| `string`[] \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### matchAny()
```ts
matchAny(other:
| string
| string[]
| LogicalExpression): LogicalExpression;
```
Checks if the expression matches any term against the field with keyword index.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| `string`[] \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### max()
```ts
max(other:
| string
| number
| LogicalExpression): LogicalExpression;
```
Computes the maximum of the expression and another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### min()
```ts
min(other:
| string
| number
| LogicalExpression): LogicalExpression;
```
Computes the minimum of the expression and another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### mul()
```ts
mul(other:
| number
| LogicalExpression): LogicalExpression;
```
Multiplies the expression by another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### ne()
```ts
ne(other:
| string
| number
| boolean
| LogicalExpression): LogicalExpression;
```
Checks if the expression does not equal another value.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| `number` \| `boolean` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### or()
```ts
or(other:
| boolean
| LogicalExpression): LogicalExpression;
```
Computes the logical OR of the expression and another expression.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `boolean` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### regexpMatch()
```ts
regexpMatch(other: string, flags?: string): LogicalExpression;
```
Check if the expression matches the provided regexp pattern.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | `string` |
| `flags?` | `string` |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### sqrt()
```ts
sqrt(): LogicalExpression;
```
Computes the square root of the expression.
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### square()
```ts
square(): LogicalExpression;
```
Computes the square of the expression.
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### startsWith()
```ts
startsWith(other:
| string
| LogicalExpression): LogicalExpression;
```
Checks if the expression starts with another value.
Can be applied on a string field or a list of strings field.
```ts
// Example:
import { field, startsWith } from "topk-js/query";
client.collection("books").query(
filter(field("title").startsWith("The") | field("tags").startsWith("fiction"))
)
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `string` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### sub()
```ts
sub(other:
| number
| LogicalExpression): LogicalExpression;
```
Subtracts another value from the expression.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | \| `number` \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
**Returns**
[`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)
###### toString()
```ts
toString(): string;
```
Returns a string representation of the logical expression.
**Returns**
`string`
***
##### Query
**`Internal`**
A query object that represents a sequence of query stages.
Queries are built by chaining together different stages like select, filter, topk, etc.
Each stage performs a specific operation on the data.
**Methods**
###### count()
```ts
count(): Query;
```
Adds a count stage to the query.
**Returns**
[`Query`](/sdk/topk-js/Namespace.query#query)
###### filter()
```ts
filter(expr:
| LogicalExpression
| TextExpression): Query;
```
Adds a filter stage to the query.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `expr` | \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) \| [`TextExpression`](/sdk/topk-js/Namespace.query#textexpression) |
**Returns**
[`Query`](/sdk/topk-js/Namespace.query#query)
###### groupBy()
```ts
groupBy(keys: Record, aggs: Record): Query;
```
Adds a group-by stage to the query.
Groups documents by one or more key expressions and computes aggregations for each group.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `keys` | `Record`\<`string`, [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression)\> |
| `aggs` | `Record`\<`string`, [`AggregateExpression`](/sdk/topk-js/Namespace.query#aggregateexpression)\> |
**Returns**
[`Query`](/sdk/topk-js/Namespace.query#query)
###### limit()
```ts
limit(k: number): Query;
```
Adds a limit stage to the query.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `k` | `number` |
**Returns**
[`Query`](/sdk/topk-js/Namespace.query#query)
###### offset()
```ts
offset(offset: number): Query;
```
Adds an offset stage to the query.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `offset` | `number` |
**Returns**
[`Query`](/sdk/topk-js/Namespace.query#query)
###### select()
```ts
select(exprs: Record): Query;
```
Adds a select stage to the query.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `exprs` | `Record`\<`string`, \| [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) \| [`FunctionExpression`](/sdk/topk-js/Namespace.query#functionexpression)\> |
**Returns**
[`Query`](/sdk/topk-js/Namespace.query#query)
###### sort()
###### Call Signature
```ts
sort(expr: LogicalExpression, asc?: boolean): Query;
```
Adds a sort stage to the query.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `expr` | [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
| `asc?` | `boolean` |
**Returns**
[`Query`](/sdk/topk-js/Namespace.query#query)
###### Call Signature
```ts
sort(expr: SortExpr[]): Query;
```
Adds a sort stage to the query.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `expr` | [`SortExpr`](/sdk/topk-js/Namespace.query#sortexpr)[] |
**Returns**
[`Query`](/sdk/topk-js/Namespace.query#query)
###### ~~topk()~~
```ts
topk(
expr: LogicalExpression,
k: number,
asc?: boolean): Query;
```
Adds a top-k stage to the query.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `expr` | [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) |
| `k` | `number` |
| `asc?` | `boolean` |
**Returns**
[`Query`](/sdk/topk-js/Namespace.query#query)
###### Deprecated
Use `.sort(expr, false).limit(k)` instead.
***
##### TextExpression
**Constructors**
**Constructor**
```ts
new TextExpression(): TextExpression;
```
**Returns**
[`TextExpression`](/sdk/topk-js/Namespace.query#textexpression)
**Methods**
###### and()
```ts
and(other: TextExpression): TextExpression;
```
Computes the logical AND of the expression and another text expression.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | [`TextExpression`](/sdk/topk-js/Namespace.query#textexpression) |
**Returns**
[`TextExpression`](/sdk/topk-js/Namespace.query#textexpression)
###### or()
```ts
or(other: TextExpression): TextExpression;
```
Computes the logical OR of the expression and another text expression.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `other` | [`TextExpression`](/sdk/topk-js/Namespace.query#textexpression) |
**Returns**
[`TextExpression`](/sdk/topk-js/Namespace.query#textexpression)
#### Interfaces
##### MatchOptions
Options for text matching.
This struct contains configuration options for text matching operations,
including field specification, weight, and matching behavior.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `all?` | `boolean` | Whether to match all terms |
| `field?` | `string` | Field to match against |
| `weight?` | `number` | Weight for the match |
***
##### MatchTokenInput
A token for match_tokens
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `token` | `string` | The token to match |
| `weight?` | `number` | Weight for the term (defaults to 1.0) |
***
##### MatchTokensOptions
Options for match_tokens.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `all?` | `boolean` | Whether to match all terms |
| `field?` | `string` | Field to match against |
***
##### ShouldOptions
Options for `should` scoring.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `field?` | `string` | Field to score against |
| `weight?` | `number` | Weight for the term |
***
##### SortExpr
An expression to sort by with its sort order.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `expr` | [`LogicalExpression`](/sdk/topk-js/Namespace.query#logicalexpression) | The expression to sort by. |
| `order` | [`SortOrder`](/sdk/topk-js/Namespace.query#sortorder) | Sort order. |
***
##### Term
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `field?` | `string` | The field to match against. |
| `token` | `string` | The token to match. |
| `weight` | `number` | The weight of the term. |
#### Type Aliases
##### DatePart
```ts
type DatePart =
| "year"
| "month"
| "week"
| "day"
| "day_of_year"
| "day_of_week"
| "hour"
| "minute"
| "second"
| "millisecond";
```
***
##### Interval
```ts
type Interval = "millisecond" | "second" | "minute" | "hour" | "day" | "week";
```
***
##### SortOrder
```ts
type SortOrder = "asc" | "desc";
```
Sort order.
### topk-js/schema
URL: https://docs.topk.io/sdk/topk-js/Namespace.schema
[topk-js](/sdk/topk-js/index) / schema
#### Functions
##### binaryVector()
```ts
function binaryVector(options: VectorOptions): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `binary_vector` values.
Example:
```javascript
import { binaryVector } from "topk-js/schema";
await client.collections().create("books", {
title_embedding: binaryVector({ dimension: 128 })
});
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `options` | [`VectorOptions`](/sdk/topk-js/Namespace.schema#vectoroptions) |
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### bool()
```ts
function bool(): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `bool` values.
Example:
```javascript
import { bool } from "topk-js/schema";
await client.collections().create("books", {
is_published: bool()
});
```
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### bytes()
```ts
function bytes(): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `bytes` values.
Example:
```javascript
import { bytes } from "topk-js/schema";
await client.collections().create("books", {
image: bytes()
});
```
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### f16Vector()
```ts
function f16Vector(options: VectorOptions): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `f16_vector` values.
Example:
```javascript
import { f16Vector } from "topk-js/schema";
await client.collections().create("books", {
title_embedding: f16Vector({ dimension: 1536 })
});
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `options` | [`VectorOptions`](/sdk/topk-js/Namespace.schema#vectoroptions) |
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### f32SparseVector()
```ts
function f32SparseVector(): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `f32_sparse_vector` values.
Note: Sparse vectors use u32 dimension indices to support dictionaries of up to 2^32 - 1 terms.
Example:
```javascript
import { f32SparseVector } from "topk-js/schema";
await client.collections().create("books", {
sparse_field: f32SparseVector()
});
```
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### f32Vector()
```ts
function f32Vector(options: VectorOptions): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `f32_vector` values.
Example:
```javascript
import { f32Vector } from "topk-js/schema";
await client.collections().create("books", {
title_embedding: f32Vector({ dimension: 1536 })
});
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `options` | [`VectorOptions`](/sdk/topk-js/Namespace.schema#vectoroptions) |
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### f8Vector()
```ts
function f8Vector(options: VectorOptions): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `f8_vector` values.
Example:
```javascript
import { f8Vector } from "topk-js/schema";
await client.collections().create("books", {
title_embedding: f8Vector({ dimension: 1536 })
});
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `options` | [`VectorOptions`](/sdk/topk-js/Namespace.schema#vectoroptions) |
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### float()
```ts
function float(): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `float` values.
Example:
```javascript
import { float } from "topk-js/schema";
await client.collections().create("books", {
price: float()
});
```
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### i8Vector()
```ts
function i8Vector(options: VectorOptions): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `i8_vector` values.
Example:
```javascript
import { i8Vector } from "topk-js/schema";
await client.collections().create("books", {
title_embedding: i8Vector({ dimension: 1536 })
});
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `options` | [`VectorOptions`](/sdk/topk-js/Namespace.schema#vectoroptions) |
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### int()
```ts
function int(): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `int` values.
Example:
```javascript
import { int } from "topk-js/schema";
await client.collections().create("books", {
published_year: int()
});
```
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### keywordIndex()
```ts
function keywordIndex(indexType?: KeywordIndexType): FieldIndex;
```
Creates a [FieldIndex](https://docs.topk.io/sdk/topk-js/schema#FieldIndex) type for `keyword_index` values.
Supported `index_type`s:
- `text` (default) - text is tokenized before indexing
- `exact` - text is indexed as a single term
Example:
```javascript
import { text, keywordIndex } from "topk-js/schema";
await client.collections().create("books", {
title: text().index(keywordIndex())
});
```
Adding a keyword index allows you to perform keyword search on this field.
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `indexType?` | [`KeywordIndexType`](/sdk/topk-js/Namespace.schema#keywordindextype) |
**Returns**
[`FieldIndex`](/sdk/topk-js/Namespace.schema#fieldindex)
***
##### list()
```ts
function list(options: ListOptions): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `list` values.
Example:
```javascript
import { list } from "topk-js/schema";
await client.collections().create("books", {
tags: list({ valueType: "text" })
});
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `options` | [`ListOptions`](/sdk/topk-js/Namespace.schema#listoptions) |
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### matrix()
```ts
function matrix(options: MatrixOptions): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `matrix` values.
Example:
```javascript
import { matrix } from "topk-js/schema";
await client.collections().create("books", {
token_embeddings: matrix({ dimension: 7, valueType: "f32" })
});
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `options` | [`MatrixOptions`](/sdk/topk-js/Namespace.schema#matrixoptions) |
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### multiVectorIndex()
```ts
function multiVectorIndex(options: MultiVectorIndexOptions): FieldIndex;
```
Creates a [FieldIndex](https://docs.topk.io/sdk/topk-js/schema#FieldIndex) type for `multi_vector_index` values.
Example:
```javascript
import { matrix, multiVectorIndex } from "topk-js/schema";
await client.collections().create("books", {
token_embeddings: matrix({ dimension: 7, valueType: "f32" }).index(
multiVectorIndex({ metric: "max_sim" })
)
});
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `options` | [`MultiVectorIndexOptions`](/sdk/topk-js/Namespace.schema#multivectorindexoptions) |
**Returns**
[`FieldIndex`](/sdk/topk-js/Namespace.schema#fieldindex)
***
##### ngramIndex()
```ts
function ngramIndex(): FieldIndex;
```
Creates a [FieldIndex](https://docs.topk.io/sdk/topk-js/schema#FieldIndex) type for `ngram_index` values.
Example:
```javascript
import { text, ngramIndex } from "topk-js/schema";
await client.collections().create("books", {
title: text().index(ngramIndex())
});
```
**Returns**
[`FieldIndex`](/sdk/topk-js/Namespace.schema#fieldindex)
***
##### semanticIndex()
```ts
function semanticIndex(): FieldIndex;
```
Creates a [FieldIndex](https://docs.topk.io/sdk/topk-js/schema#FieldIndex) type for `semantic_index` values.
Example:
```javascript
import { text, semanticIndex } from "topk-js/schema";
await client.collections().create("books", {
title: text().index(semanticIndex())
});
```
**Returns**
[`FieldIndex`](/sdk/topk-js/Namespace.schema#fieldindex)
***
##### struct()
```ts
function struct(fields: Record): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `struct` values.
Example:
```javascript
import { struct, text, int } from "topk-js/schema";
await client.collections().create("books", {
meta: struct({ author: text(), year: int() })
});
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `fields` | `Record`\<`string`, [`SchemaFieldSpec`](/sdk/topk-js/index#schemafieldspec)\> |
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### text()
```ts
function text(): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `text` values.
Example:
```javascript
import { text } from "topk-js/schema";
await client.collections().create("books", {
title: text()
});
```
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### timestamp()
```ts
function timestamp(): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `timestamp` values.
Timestamps are stored as milliseconds since UNIX epoch.
When upserting timestamps, use:
- `Date` objects
- `number` — epoch milliseconds
Example:
```javascript
import { timestamp } from "topk-js/schema";
await client.collections().create("books", {
published_ts: timestamp()
});
```
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### u8SparseVector()
```ts
function u8SparseVector(): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `u8_sparse_vector` values.
Note: Sparse vectors use u32 dimension indices to support dictionaries of up to 2^32 - 1 terms.
Example:
```javascript
import { u8SparseVector } from "topk-js/schema";
await client.collections().create("books", {
sparse_field: u8SparseVector()
});
```
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### u8Vector()
```ts
function u8Vector(options: VectorOptions): FieldSpec;
```
Creates a [FieldSpec](https://docs.topk.io/sdk/topk-js/schema#FieldSpec) type for `u8_vector` values.
Example:
```javascript
import { u8Vector } from "topk-js/schema";
await client.collections().create("books", {
title_embedding: u8Vector({ dimension: 1536 })
});
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `options` | [`VectorOptions`](/sdk/topk-js/Namespace.schema#vectoroptions) |
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
***
##### vectorIndex()
```ts
function vectorIndex(options: VectorIndexOptions): FieldIndex;
```
Creates a [FieldIndex](https://docs.topk.io/sdk/topk-js/schema#FieldIndex) type for `vector_index` values.
Supported `metric`s:
- `euclidean` (not supported for sparse vectors)
- `cosine` (not supported for sparse vectors)
- `dot_product` (supported for dense and sparse vectors)
- `hamming` (only supported for binary_vector type)
Example:
```javascript
import { f32Vector, vectorIndex } from "topk-js/schema";
await client.collections().create("books", {
title_embedding: f32Vector({ dimension: 1536 }).index(
vectorIndex({ metric: "cosine" })
)
});
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `options` | [`VectorIndexOptions`](/sdk/topk-js/Namespace.schema#vectorindexoptions) |
**Returns**
[`FieldIndex`](/sdk/topk-js/Namespace.schema#fieldindex)
#### Classes
##### FieldIndex
**`Internal`**
***
##### FieldSpec
**`Internal`**
**Methods**
###### index()
```ts
index(index: FieldIndex): FieldSpec;
```
Creates an index on a field.
Example:
```javascript
import { text, keywordIndex } from "topk-js/schema";
await client.collections().create("books", {
title: text().index(keywordIndex())
});
```
**Parameters**
| Parameter | Type |
| ------ | ------ |
| `index` | [`FieldIndex`](/sdk/topk-js/Namespace.schema#fieldindex) |
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
###### required()
```ts
required(): FieldSpec;
```
Marks the field as required. All fields are optional by default.
Example:
```javascript
import { text } from "topk-js/schema";
await client.collections().create("books", {
title: text().required()
});
```
**Returns**
[`FieldSpec`](/sdk/topk-js/Namespace.schema#fieldspec)
#### Interfaces
##### ListOptions
Options for list field specifications.
This struct contains configuration options for list fields,
including the type of values the list can contain.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `valueType` | [`ListValueType`](/sdk/topk-js/Namespace.schema#listvaluetype) | The type of values the list can contain |
***
##### MatrixOptions
Options for matrix field specifications.
This struct contains configuration options for matrix fields,
including the dimension and value type.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `dimension` | `number` | The dimension (number of columns) of the matrix |
| `valueType` | [`MatrixValueType`](/sdk/topk-js/Namespace.schema#matrixvaluetype) | The value type of the matrix elements |
***
##### MultiVectorIndexOptions
Options for multi-vector index specifications.
This struct contains configuration options for multi-vector indexes,
including the distance metric to use.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `metric` | `"maxsim"` | The distance metric to use for multi-vector similarity |
| `quantization?` | [`MultiVectorQuantization`](/sdk/topk-js/Namespace.schema#multivectorquantization) | The quantization to use for multi-vector values |
| `topK?` | `number` | Top-k projected values to keep |
| `width?` | `number` | Width of the sparse projection |
***
##### VectorIndexOptions
Options for vector index specifications.
This struct contains configuration options for vector indexes,
including the distance metric to use.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `metric` | [`VectorDistanceMetric`](/sdk/topk-js/Namespace.schema#vectordistancemetric) | The distance metric to use for vector similarity |
***
##### VectorOptions
Options for vector field specifications.
This struct contains configuration options for vector fields,
including the required dimension parameter.
**Properties**
| Property | Type | Description |
| ------ | ------ | ------ |
| `dimension` | `number` | The dimension of the vector |
#### Type Aliases
##### KeywordIndexType
```ts
type KeywordIndexType = "text" | "exact";
```
***
##### ListValueType
```ts
type ListValueType = "text" | "integer" | "float";
```
***
##### MatrixValueType
```ts
type MatrixValueType = "f32" | "f16" | "f8" | "u8" | "i8";
```
***
##### MultiVectorDistanceMetric
```ts
type MultiVectorDistanceMetric = "maxsim";
```
***
##### MultiVectorQuantization
```ts
type MultiVectorQuantization = "1bit" | "2bit" | "scalar";
```
***
##### VectorDistanceMetric
```ts
type VectorDistanceMetric = "cosine" | "euclidean" | "dot_product" | "hamming";
```
## SQL
### Overview
URL: https://docs.topk.io/sdk/topk-sql/overview
TopK exposes a PostgreSQL wire protocol endpoint — any standard SQL client can connect and issue queries and writes against your collections.
#### Prerequisites
- **API key** — sign in to [console.topk.io](https://console.topk.io) and generate an API key.
- **Region** — see [docs.topk.io/regions](https://docs.topk.io/regions) for available regions.
#### Setup
Connect using any PostgreSQL-compatible client — `psql`, `psycopg2`, `node-postgres`, `tokio-postgres`, and others.
```bash
psql "host=.sql.topk.io port=5432 user=topk password= dbname=topk"
```
Replace `` with your selected region and `` with your API key.
See [available regions](https://docs.topk.io/regions) and get your [API key](https://console.topk.io/api-key).
#### Quick Start
Create a collection, insert documents, and run a semantic search with SQL:
```sql
-- 1. Create a collection
CREATE TABLE books (
title TEXT NOT NULL,
content TEXT INDEX semantic_index(),
author TEXT NOT NULL,
rating FLOAT
);
-- 2. Insert documents
INSERT INTO books (_id, title, content, author, rating)
VALUES
('1', 'The Hobbit',
'A hobbit embarks on an unexpected journey through Middle-earth.',
'Tolkien', 4.3),
('2', '1984',
'A dystopian novel about totalitarian surveillance and control.',
'George Orwell', 4.7),
('3', 'Dune',
'An epic saga of politics, religion, and ecology on a desert planet.',
'Frank Herbert', 4.5);
-- 3. Search
SELECT _id, title, semantic_similarity(content, 'political control and oppression') AS score
FROM books
ORDER BY score DESC
LIMIT 10;
```
The `INDEX` clause is a TopK extension to SQL that lets you declare search indexes inline with your column definitions.
#### Schemaless by default
TopK collections are schemaless by default. Documents can have any fields with any
types — no schema declaration is required to store or query them.
The only exception: **fields you want to index must be declared**, because index
configuration (metric, index type, etc.) is attached to the field definition.
Column types are inferred from the schema, search function return values, and explicit casts. Columns that can't be typed statically (e.g. unindexed fields with mixed values) fall back to JSON. Use the `::` cast operator to force a specific wire type.
For example, to cast `published_year` to `int4` and `rating` to `float8`, use:
```sql
SELECT title, published_year::int4, rating::float8 FROM books LIMIT 10;
```
#### SQL Reference
##### Table references
Statements use `
` as either a collection name or a collection plus partition:
```text
::= [schema.]collection[$partition]
```
The `schema` prefix is accepted but ignored — all collections live in a single namespace per project.
###### Partitions
Partitions can be specified with `$` or the `PARTITION` keyword:
| Form | Example |
|------|---------|
| `collection` | `books` |
| `schema.collection` | `public.books` |
| `collection$partition` | `books$2024` |
| `schema.collection$partition` | `public.books$2024` |
| `collection PARTITION name` | `books PARTITION 2024` |
Partition syntax applies to `SELECT`, `INSERT`, `UPDATE`, and `DELETE` only. `CREATE TABLE` and `DROP TABLE` name collections without partitions; partitions are created implicitly on first write.
##### SELECT
The primary query interface. Compute search scores in the projection, filter by metadata or text predicates in `WHERE`, and rank results by any scoring expression in `ORDER BY`.
```sql
SELECT FROM
[WHERE ]
[ORDER BY [ASC | DESC] LIMIT [OFFSET ]]
```
`OFFSET` requires a `LIMIT` — `OFFSET` alone is not supported.
###### Projection
Each item in the select list must be one of:
- A **named column**: `SELECT title, rating`
- A **struct subfield**: `SELECT metadata.publisher`
- An **aliased expression**: `SELECT rating * 2 AS double_rating` — expressions **must** have an `AS` alias
- A **search function**: `SELECT vector_distance(embedding, '[1,0,0,0]'::f32_vector) AS score`
- A **wire-type cast**: `SELECT rating::float8 AS rating_f64`
Wire-type casts (`::int4`, `::float8`, `::text`, …) control how the column is typed on the wire, which is useful when your driver infers the wrong type. Unaliased casts use the inner expression as the column name (`SELECT title::text` → column `title`). See [Output type mapping](#output-type-mapping) for the full table.
`COUNT(*)` returns the number of matching documents. The result column is named `_count` unless aliased with `AS`.
###### WHERE filters
| Operator | Example |
|----------|---------|
| `=`, `<>`, `!=`, `<`, `<=`, `>`, `>=` | `rating > 4.0` |
| `AND`, `OR`, `NOT` | `genre = 'fantasy' AND in_print = true` |
| `IS NULL`, `IS NOT NULL` | `checksum IS NOT NULL` |
| `IN`, `NOT IN` | `genre IN ('fantasy', 'fiction')` |
| `BETWEEN`, `NOT BETWEEN` | `published_year BETWEEN 1900 AND 2000` |
| `LIKE`, `NOT LIKE` | `title LIKE 'The%'` |
| `~` (regex) | `author ~ 'Tol.*'` |
| Arithmetic | `rating * 10 > 40` |
| `CASE WHEN … THEN … ELSE … END` | `CASE WHEN rating > 4.0 THEN 'top' ELSE 'other' END AS tier` |
| `contains(field, scalar)` | `contains(tags, 'classic')` |
| `match(query [, field [, weight [, all]]])` | `match('hobbit rings', title)` |
| `match_tokens(tokens [, field [, all]])` | `match_tokens(ARRAY['love', 'classic'], tags)` |
| `should(query [, field [, weight]])` | `should('rings', title)` |
| `match_all(field, query)` | `match_all(title, 'hobbit rings')` |
| `match_any(field, query)` | `match_any(tags, ARRAY['love', 'classic'])` |
`match(...)` and `match_tokens(...)` search keyword-indexed text and can be ranked
with `bm25_score()`. Combine text searches with `AND` / `OR`; add metadata filters
with `AND`:
```sql
WHERE (match('hobbit', title) OR match('dune', title))
AND rating > 4.0
```
Text searches can be combined with each other using `OR`, and with metadata filters using `AND`.
###### Timestamps
Declare a timestamp column with `TIMESTAMP`:
```sql
CREATE TABLE books (
title TEXT,
published_ts TIMESTAMP
);
```
Timestamps are stored as milliseconds since UNIX epoch and returned as `int8`.
To write timestamp values, use the `TIMESTAMP '...'` literal:
```sql
INSERT INTO books (_id, title, published_ts)
VALUES ('gatsby', 'The Great Gatsby', TIMESTAMP '1925-04-10');
```
Accepted formats:
- `'YYYY-MM-DD'` — midnight UTC
- `'YYYY-MM-DDTHH:MM:SS[.fff]Z'` — UTC, `Z` = UTC
- `'YYYY-MM-DDTHH:MM:SS[.fff]±HH:MM'` — UTC offset, e.g. `+02:00`
To filter by a timestamp column, compare it against a `TIMESTAMP '...'` literal:
```sql
SELECT _id, title
FROM books
WHERE published_ts < TIMESTAMP '1929-01-01'
ORDER BY published_ts ASC
LIMIT 10;
```
Use `EXTRACT(YEAR FROM ts)` (or `date_part('year', ts)`) to extract parts of a timestamp:
```sql
-- Books published in July
SELECT _id, published_ts
FROM books
WHERE EXTRACT(MONTH FROM published_ts) = 7
LIMIT 10;
```
Supported parts:
| `EXTRACT` | `date_part` | Value |
|-----------|-------------|-------|
| `YEAR` | `'year'` | calendar year |
| `MONTH` | `'month'` | 1-12 |
| `WEEK` | `'week'` | ISO week number |
| `DAY` | `'day'` | day of month, 1-31 |
| `DOY` | `'day_of_year'` | 1-366 |
| `DOW` | `'day_of_week'` | 0-6, Monday = 0 |
| `HOUR` | `'hour'` | 0-23 |
| `MINUTE` | `'minute'` | 0-59 |
| `SECOND` | `'second'` | 0-59 |
| `MILLISECOND` | `'millisecond'` | 0-999 |
Use `elapsed(start, end, interval)` to compute the number of interval units between two timestamps:
```sql
-- Days elapsed between two timestamps
SELECT _id, elapsed(published_ts, TIMESTAMP '2000-01-01', 'day') AS age_days
FROM books
ORDER BY age_days ASC
LIMIT 10;
```
Supported intervals:
- `'millisecond'`
- `'second'`
- `'minute'`
- `'hour'`
- `'day'`
- `'week'`
###### Search Functions
TopK extends SQL with search-specific functions for scoring and filtering. Scoring functions compute relevance in `SELECT`; text search predicates filter documents in `WHERE`.
###### **Scoring functions**
Scoring functions compute a relevance score for each document. Call them in `SELECT`, give them an alias, then use that alias in `ORDER BY` to rank results. All scoring functions return the score as `f32`:
```sql
SELECT _id, title, bm25_score() AS score
FROM books
WHERE match('dune', title)
ORDER BY score DESC
LIMIT 10;
```
| Function | Description |
|----------|-------------|
| `vector_distance(field, query [, skip_refine])` | Dense or sparse ANN distance |
| `multi_vector_distance(field, query [, candidates])` | Multi-vector MaxSim distance |
| `semantic_similarity(field, query)` | Semantic embedding similarity |
| `bm25_score([b, k1])` | Keyword relevance score; requires `match(...)` or `match_tokens(...)` in `WHERE` |
| `boost(score, condition, factor)` | Multiply score when condition is true |
###### **Text search predicates**
Text search predicates filter documents in `WHERE` based on keyword matches. `match(...)` and `match_tokens(...)` enable BM25 scoring via `bm25_score()`.
```sql
SELECT _id, title, bm25_score() AS score
FROM books
WHERE match('dune', title)
ORDER BY score DESC
LIMIT 10;
```
| Function | Description |
|----------|-------------|
| `match(query [, field [, weight [, all]]])` | Keyword text search |
| `match_tokens(tokens [, field [, all]])` | Keyword token search |
| `should(query [, field [, weight]])` | Optional BM25 scoring term without filtering |
| `match_all(field, query)` | Boolean predicate — all terms must match |
| `match_any(field, query)` | Boolean predicate — any term must match |
| `contains(field, scalar)` | List membership or string substring |
`should(...)` adds an optional BM25 scoring term without filtering documents from the result set — documents containing the term score higher, while documents that do not contain it remain eligible. On its own it matches the entire collection; combine it with `match(...)` using `AND` when some terms are required and others should only influence ranking:
```sql
SELECT _id, title, bm25_score() AS score
FROM books
WHERE match('hobbit rings', title) AND should('lord', title)
ORDER BY score DESC
LIMIT 10;
```
`match_all(...)` and `match_any(...)` are boolean-only predicates — they filter documents but do not affect relevance ranking:
```sql
SELECT _id, title
FROM books
WHERE match_any(title, ARRAY['dune', 'hobbit'])
AND rating > 4.0;
```
Text searches can be combined with each other using `OR`, and with metadata filters using `AND`:
```sql
SELECT _id, title, bm25_score() AS score
FROM books
WHERE (match('hobbit', title) OR match('dune', title))
AND rating > 4.0
ORDER BY score DESC
LIMIT 10;
```
`match(...)` and `match_tokens(...)` cannot be combined with metadata conditions using `OR`. Use `match_any(...)` or `match_all(...)` for keyword predicates that need to appear in an `OR` alongside other conditions — they work in any logical expression but do not affect `bm25_score()`.
###### **Example queries**
```sql
-- Vector ANN
SELECT
_id,
title,
vector_distance(embedding, '[1,0,0,0]'::f32_vector) AS vec_dist
FROM books
ORDER BY vec_dist DESC -- DESC for cosine/dot_product; ASC for euclidean
LIMIT 3;
-- Sparse vector ANN
SELECT
_id,
title,
vector_distance(sparse_emb, '{"0":1.0,"1":0.5}'::f32_sparse_vector) AS vec_dist
FROM books
ORDER BY vec_dist DESC
LIMIT 3;
-- Multi-vector MaxSim
SELECT
_id,
title,
multi_vector_distance(multi_emb, '[[1.0,0.0,0.0,0.0]]'::f32_matrix) AS vec_dist
FROM books
ORDER BY vec_dist DESC
LIMIT 3;
-- Full-text BM25
SELECT
_id,
title,
bm25_score() AS bm25_score
FROM books
WHERE match('hobbit rings', title)
ORDER BY bm25_score DESC
LIMIT 5;
-- Semantic similarity
SELECT
_id,
title,
semantic_similarity(bio, 'tales of magic and adventure') AS sem_similarity
FROM books
ORDER BY sem_similarity DESC
LIMIT 3;
-- Hybrid: vector + boost
SELECT
_id,
title,
vector_distance(embedding, '[1,0,0,0]'::f32_vector) AS vec_dist
FROM books
WHERE match_any(title, 'hobbit')
ORDER BY boost(vec_dist, in_print = true, 1.5)
LIMIT 5;
-- Boolean keyword predicates
SELECT _id, title
FROM books
WHERE match_all(title, 'the hobbit')
OR match_any(title, ARRAY['dune', '1984'])
LIMIT 5;
```
###### GROUP BY
Group rows by one or more key expressions and compute aggregations per group.
```sql
SELECT FROM
[WHERE ]
GROUP BY [, ...]
[HAVING ]
[ORDER BY [ASC | DESC] LIMIT ]
```
A GROUP BY key must be a bare identifier — either a real column (`GROUP BY genre`) or a SELECT-list alias for a computed expression:
```sql
SELECT published_year < 1940 AS is_classic, COUNT(*) AS count
FROM books
GROUP BY is_classic;
```
Every item in the SELECT list of a GROUP BY query must be either a group key or an aggregate function call — arbitrary columns are not allowed.
| Function | Description |
|----------|-------------|
| `COUNT(*)` | Number of rows in the group |
| `COUNT(field)` | Number of non-null values of `field` in the group |
| `SUM(field)` | Sum of `field` in the group |
| `MIN(field)` | Minimum value of `field` in the group |
| `MAX(field)` | Maximum value of `field` in the group |
| `AVG(field)` | Average value of `field` in the group |
`HAVING` filters on the grouped/aggregated output and requires a `GROUP BY` clause:
```sql
SELECT genre, COUNT(*) AS count, AVG(rating) AS avg_rating
FROM books
GROUP BY genre
HAVING COUNT(*) > 1
ORDER BY avg_rating DESC
LIMIT 5;
```
`GROUP BY ALL` and `ROLLUP` / `CUBE` / `GROUPING SETS` modifiers are not supported.
##### INSERT
Upsert semantics: inserting a document with an existing `_id` replaces it.
`_id` is required and must appear in the column list.
```sql
INSERT INTO
(
, ...) VALUES (, ...) [, (, ...) ...];
```
Scalars use plain literals. TopK-native values use `::topk_type` casts or constructor
calls — see [Type System](#type-system). Prefer casts in `VALUES`:
```sql
INSERT INTO books (_id, title, author, published_year, rating, embedding, sparse_emb)
VALUES
(
'hobbit', 'The Hobbit', 'Tolkien', 1937, 4.3,
'[1.0, 0.0, 0.0, 0.0]'::f32_vector,
'{"0": 1.0, "1": 0.5}'::f32_sparse_vector
);
```
##### UPDATE
Updates one or more fields on existing documents. `_id` cannot be updated. A `WHERE`
clause is required and must resolve to a set of document IDs.
Value expressions in `SET` follow the same rules as [INSERT](#insert) `VALUES`.
```sql
UPDATE
SET
= [, ...] WHERE _id = '';
UPDATE
SET
= [, ...] WHERE _id IN ('', '', ...);
```
##### DELETE
Deletes documents by ID or by filter expression. A `WHERE` clause is required unless
the target is a partition, in which case the entire partition is dropped.
```sql
DELETE FROM
WHERE _id = '';
DELETE FROM
WHERE _id IN ('', '', ...);
DELETE FROM
WHERE ;
DELETE FROM $;
```
##### CREATE TABLE
Schema is defined once at collection creation. Indexes are declared inline on each column using a TopK-specific `INDEX` clause — standalone `CREATE INDEX` statements are not supported.
```sql
CREATE TABLE [IF NOT EXISTS]
(
[NOT NULL] [INDEX ()],
...
);
```
`IF NOT EXISTS` suppresses the error if the collection already exists.
###### Column types
| SQL type | TopK field type |
|----------|-----------------|
| `BOOLEAN` | `boolean` |
| `INTEGER` / `BIGINT` / `INT` | `integer` |
| `SMALLINT` / `INT2` / `INT4` | `integer` |
| `FLOAT` / `REAL` / `DOUBLE PRECISION` | `float` |
| `TEXT` / `VARCHAR` | `text` |
| `BYTEA` | `bytes` |
| `TIMESTAMP` | `timestamp` |
| `TEXT[]` | `list` |
| `INTEGER[]` | `list` |
| `FLOAT[]` | `list` |
| `JSONB` | `struct` |
| `f32_vector(n)` | `f32_vector(n)` |
| `f16_vector(n)` | `f16_vector(n)` |
| `f8_vector(n)` | `f8_vector(n)` |
| `u8_vector(n)` | `u8_vector(n)` |
| `i8_vector(n)` | `i8_vector(n)` |
| `binary_vector(n)` | `binary_vector(n)` |
| `f32_sparse_vector` | `f32_sparse_vector` |
| `f16_sparse_vector` | `f16_sparse_vector` |
| `f8_sparse_vector` | `f8_sparse_vector` |
| `u8_sparse_vector` | `u8_sparse_vector` |
| `i8_sparse_vector` | `i8_sparse_vector` |
| `f32_matrix(n)` | `f32_matrix(n)` |
| `f16_matrix(n)` | `f16_matrix(n)` |
| `f8_matrix(n)` | `f8_matrix(n)` |
| `u8_matrix(n)` | `u8_matrix(n)` |
| `i8_matrix(n)` | `i8_matrix(n)` |
`NOT NULL` marks a field as required. All columns are optional by default.
###### Index types
| Method | Applies to | Options |
|--------|------------|---------|
| `keyword_index()` | `TEXT`, `VARCHAR` | type: `text` (default) — tokenized before indexing `exact` — indexed as a single term |
| `semantic_index()` | `TEXT`, `VARCHAR` | — |
| `ngram_index()` | `TEXT`, `VARCHAR` | — |
| `vector_index()` | `*_vector(n)`, `*_sparse_vector` | metric: `cosine`, `dot_product`, `euclidean`, `hamming` |
| `multi_vector_index()` | `*_matrix(n)` | metric: `maxsim` quantization: `1bit`, `2bit`, `scalar` width, top_k |
###### Example
```sql
CREATE TABLE books (
title TEXT NOT NULL INDEX keyword_index(),
author TEXT NOT NULL,
published_year INTEGER NOT NULL,
rating FLOAT,
genre TEXT INDEX keyword_index(type = 'exact'),
in_print BOOLEAN,
bio TEXT INDEX semantic_index(),
embedding f32_vector(4) INDEX vector_index(metric = 'cosine'),
sparse_emb f32_sparse_vector INDEX vector_index(metric = 'dot_product'),
multi_emb f32_matrix(4) INDEX multi_vector_index(metric = 'maxsim'),
tags TEXT[],
checksum BYTEA,
metadata JSONB
);
```
##### DROP TABLE
Permanently deletes a collection and all of its documents and indexes. This operation is irreversible.
```sql
DROP TABLE [IF EXISTS]
;
```
`IF EXISTS` suppresses the error if the collection does not exist.
##### information_schema
TopK exposes two `information_schema` virtual tables for inspecting collections and their schemas. Specify column names explicitly in the select list — `SELECT *` is not supported on virtual tables.
###### information_schema.tables
Returns one row per collection in the project. Use it to list collections or check whether a specific collection exists.
```sql
SELECT table_name, table_schema, table_type FROM information_schema.tables;
```
`WHERE` clauses are accepted but **silently ignored** — all collections are always returned.
| Column | Type | Value |
|--------|------|-------|
| `table_name` | `text` | collection name |
| `table_schema` | `text` | `"public"` |
| `table_type` | `text` | `"BASE TABLE"` |
| `table_owner` | `text` | `"topk"` |
###### information_schema.columns
Returns one row per declared field in a collection. Filter by collection name using `WHERE table_name = ''`.
```sql
SELECT column_name, data_type
FROM information_schema.columns
WHERE table_name = 'books';
```
Additional `AND` clauses (e.g. `AND table_schema = 'public'`) are accepted but **silently ignored**.
| Column | Type | Value |
|--------|------|-------|
| `column_name` | `text` | field name |
| `data_type` | `text` | see mapping below |
| `is_nullable` | `text` | `"YES"` or `"NO"` |
| `table_name` | `text` | collection name |
**Data type mapping:**
| TopK field type | `data_type` |
|-----------------|-------------|
| `text` | `text` |
| `integer` | `bigint` |
| `float` | `double precision` |
| `boolean` | `boolean` |
| `bytes` | `bytea` |
| `*_vector(n)` (all dense variants) | `real[]` |
| `*_sparse_vector` (all variants) | `jsonb` |
| `list`, `struct`, `*_matrix` | `jsonb` |
##### EXPLAIN
Returns the parsed `Statement` AST as a single `plan TEXT` column:
```sql
EXPLAIN ;
EXPLAIN VERBOSE ;
```
##### Session commands
| Command | Behavior |
|---------|----------|
| `SET consistency_level = 'indexed'` | Indexed consistency for subsequent reads |
| `SET consistency_level = 'strong'` | Strong consistency for subsequent reads |
| `SET consistency_level = 'default'` | Clears the session override (router default) |
| `SHOW consistency_level` | Returns the current consistency level |
`SET`/`SHOW` only recognize `consistency_level`; all other variable names return an error.
The following commands are accepted and silently succeed:
| Command |
|---------|
| `BEGIN` |
| `COMMIT` |
| `ROLLBACK` |
| `DISCARD ` |
#### PostgreSQL Compatibility
TopK speaks the PostgreSQL wire protocol but is purpose-built for search — not general-purpose relational queries. Some SQL features are intentionally absent because they don't map to search semantics or would work against search performance.
##### Queries
**Single `ORDER BY` key** — Ranking is a single scoring expression. Combine multiple signals into one composite score rather than sorting by multiple columns: `ORDER BY vec_dist * 0.7 + bm25_score() * 0.3 DESC`.
**No `SELECT *`** — Selecting all columns is not supported. Indexed vector fields cannot be projected directly — use search functions (`vector_distance`, `semantic_similarity`, …) to get scores from them instead.
**`COUNT(*)` without `GROUP BY` is a standalone aggregate** — it returns a document count and cannot be combined with other columns in the same `SELECT` list. Inside a `GROUP BY` query, `COUNT(*)` behaves as an ordinary per-group aggregate and can be combined with other keys/aggregates — see [GROUP BY](#group-by).
**`GROUP BY` keys must be identifiers** — group by a real column or a SELECT-list alias for a computed expression; you can't group by an inline expression directly. `GROUP BY ALL` and `ROLLUP`/`CUBE`/`GROUPING SETS` are not supported.
**No implicit string-to-timestamp coercion** — `WHERE published_ts < '1929-01-01'` compares against a string and silently matches nothing. Use a typed literal instead: `WHERE published_ts < TIMESTAMP '1929-01-01'`.
**Timestamps require a timezone** — datetime literals without a timezone (e.g. `TIMESTAMP '1925-04-10 00:00:00'`) are rejected. Use an RFC 3339 offset (`TIMESTAMP '1925-04-10T00:00:00Z'`) or a date-only literal (`TIMESTAMP '1925-04-10'`, midnight UTC). `TIMESTAMPTZ` is not supported.
**No whole-value equality on complex types** — `tags = ARRAY['a']` is not supported. Use `contains(tags, 'a')` to check whether a single value exists in a list field — `contains` checks for one value at a time, not a list of values.
##### Writes
**Upsert-only `INSERT`** — `INSERT` always replaces a document when `_id` already exists, so `ON CONFLICT` is built-in and not needed. `INSERT … SELECT` and `RETURNING` are not supported.
**`::topk_type` casts in `VALUES`** — Standard PostgreSQL casts (`::float8`, `CAST(… AS text)`) aren't supported inside `INSERT`/`UPDATE` values. Use TopK-native casts (`::f32_vector`, `::f32_sparse_vector`, …) instead — see [Type System](#type-system).
##### Transactions
`BEGIN`/`COMMIT`/`ROLLBACK` are accepted without error so that drivers that auto-wrap statements in transactions (psycopg2, SQLAlchemy, JDBC) connect without modification. Writes are not transactional; `ROLLBACK` does not undo changes.
##### Structs
Individual struct subfields can be selected using dot notation:
```sql
SELECT metadata.publisher, metadata.year FROM books LIMIT 10;
```
To retrieve multiple subfields, list each one explicitly — selecting a whole struct column is **not supported**:
```sql
-- not supported
SELECT metadata FROM books;
```
#### Type System
TopK-native literals use **`::topk_type` casts** (preferred in `INSERT`/`UPDATE`
`VALUES` and search-function arguments) or equivalent **constructor calls**.
PostgreSQL wire-type casts (`::float8`, …) apply only in `SELECT` projection.
| Constructor | Example |
|-------------|---------|
| `f32_vector(ARRAY[…])` | `'[0.1, 0.2, 0.3]'::f32_vector` or `f32_vector(ARRAY[0.1, 0.2, 0.3])` |
| `f16_vector(ARRAY[…])` | (same pattern) |
| `f8_vector(ARRAY[…])` | (same pattern) |
| `u8_vector(ARRAY[…])` | (same pattern) |
| `i8_vector(ARRAY[…])` | (same pattern) |
| `binary_vector(ARRAY[…])` | (same pattern) |
| `f32_sparse_vector(ARRAY[idx], ARRAY[val])` | `f32_sparse_vector(ARRAY[0, 2], ARRAY[1.0, 0.5])` or `'{"0":1.0,"2":0.5}'::f32_sparse_vector` or `'{"indices":[0,2],"values":[1.0,0.5]}'::f32_sparse_vector` |
| `f16_sparse_vector(…)` | (same pattern) |
| `f8_sparse_vector(…)` | (same pattern) |
| `u8_sparse_vector(…)` | (same pattern) |
| `i8_sparse_vector(…)` | (same pattern) |
| `f32_matrix(ARRAY[ARRAY[row1],…])` | `'[[1.0, 0.0], [0.5, 0.5]]'::f32_matrix` |
| `f16_matrix(…)` | (same pattern) |
| `f8_matrix(…)` | (same pattern) |
| `u8_matrix(…)` | (same pattern) |
| `i8_matrix(…)` | (same pattern) |
| `bytes('hexstring')` | `bytes('deadbeef')` |
| `struct(key1, val1, …)` | `struct('publisher', 'Penguin', 'pages', 320)` |
| `ARRAY[elem, …]` | `ARRAY['classic', 'fiction']` (list) |
##### Complex types → JSON
Vector, matrix, sparse, and list types are returned as JSON when selected. Indexed vector fields cannot be projected directly — use scoring functions to compute scores from them. The table below documents the wire format for each type:
| TopK type | JSON wire representation |
|-----------|--------------------------|
| Dense vector | `[0.1, 0.2, 0.3]` |
| Sparse vector | `{"indices":[0,2],"values":[1.0,0.5]}` or `{"0":1.0,"2":0.5}` |
| Matrix (multi-vector) | `[[1.0,0.0],[0.5,0.1]]` (row-major) |
| List | `["a","b"]` / `[1,2,3]` |
| Struct | `{"publisher":"Scribner","pages":180}` |
| Binary | `\xdeadbeef` |
##### Output type mapping
pgwire maps SELECT-list expressions to PostgreSQL OIDs. Explicit `::cast` in the
projection list overrides inference. Casts are stripped from the query plan — they
only affect the wire type.
| Expression | pg OID |
|------------|--------|
| `::bool` | 16 `BOOL` |
| `::smallint` / `::int2` | 21 `INT2` |
| `::int` / `::int4` | 23 `INT4` |
| `::bigint` / `::int8` | 20 `INT8` |
| `::real` / `::float4` | 700 `FLOAT4` |
| `::float` / `::float8` | 701 `FLOAT8` |
| `::text` | 25 `TEXT` |
| `::bytea` | 17 `BYTEA` |
| `::json` / `::jsonb` | 114 `JSON` |
| plain column (no cast) | 114 `JSON` |
| search function (no cast) | 700 `FLOAT4` |
| `COUNT(*)` (no cast) | 20 `INT8` |
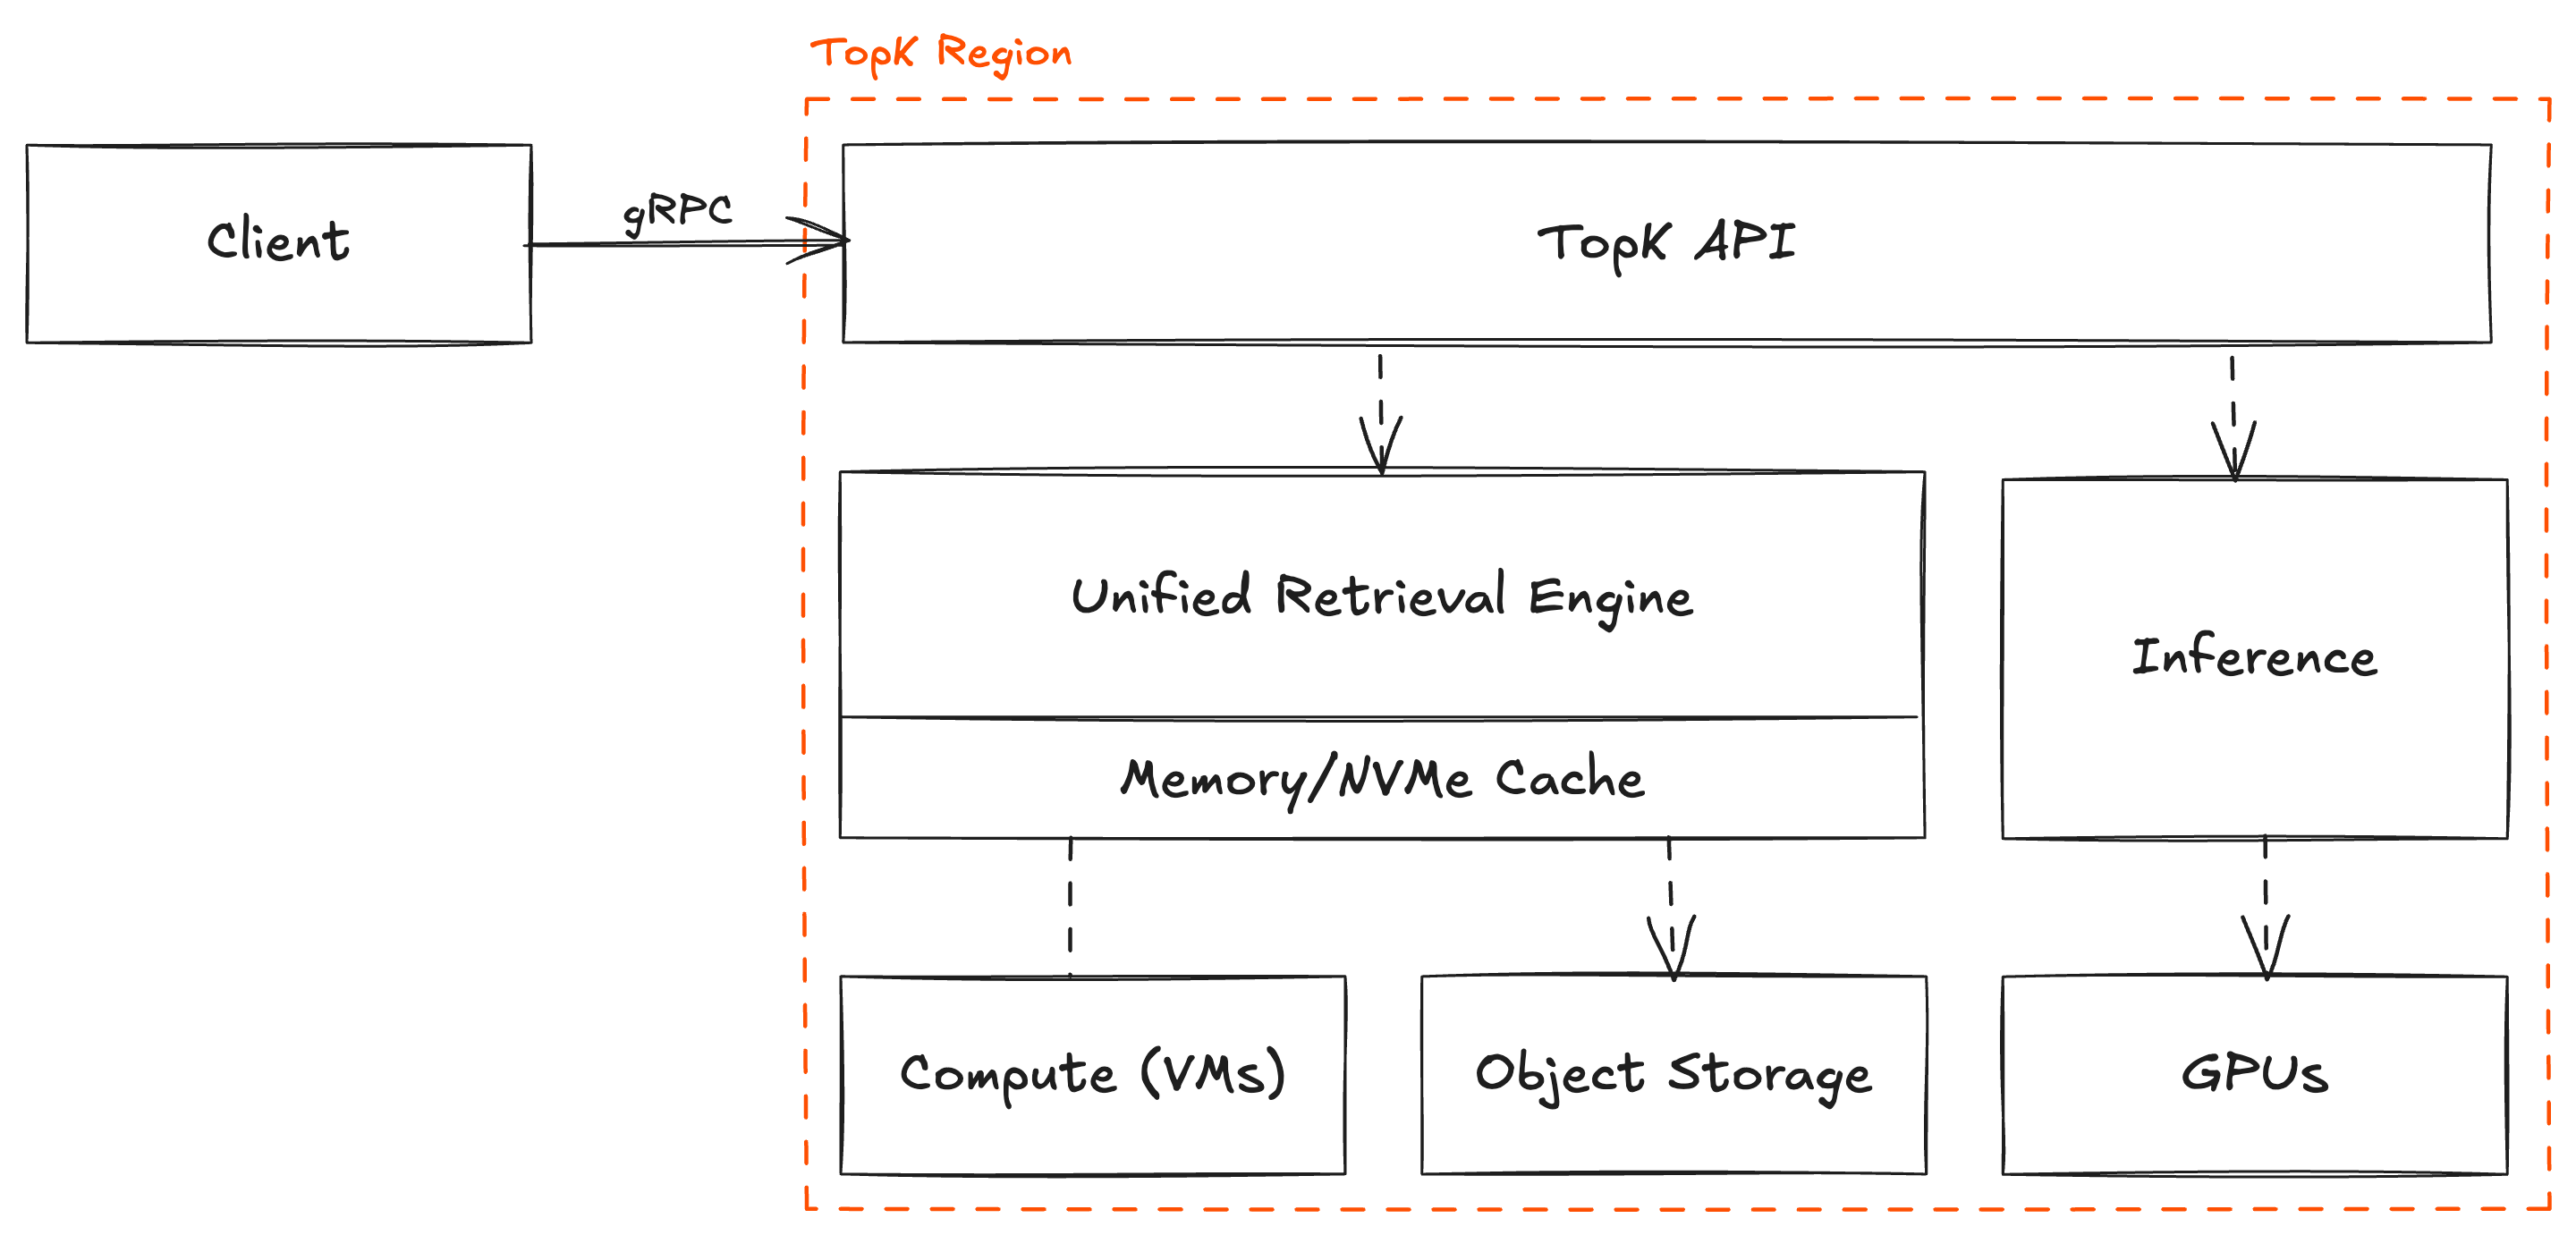
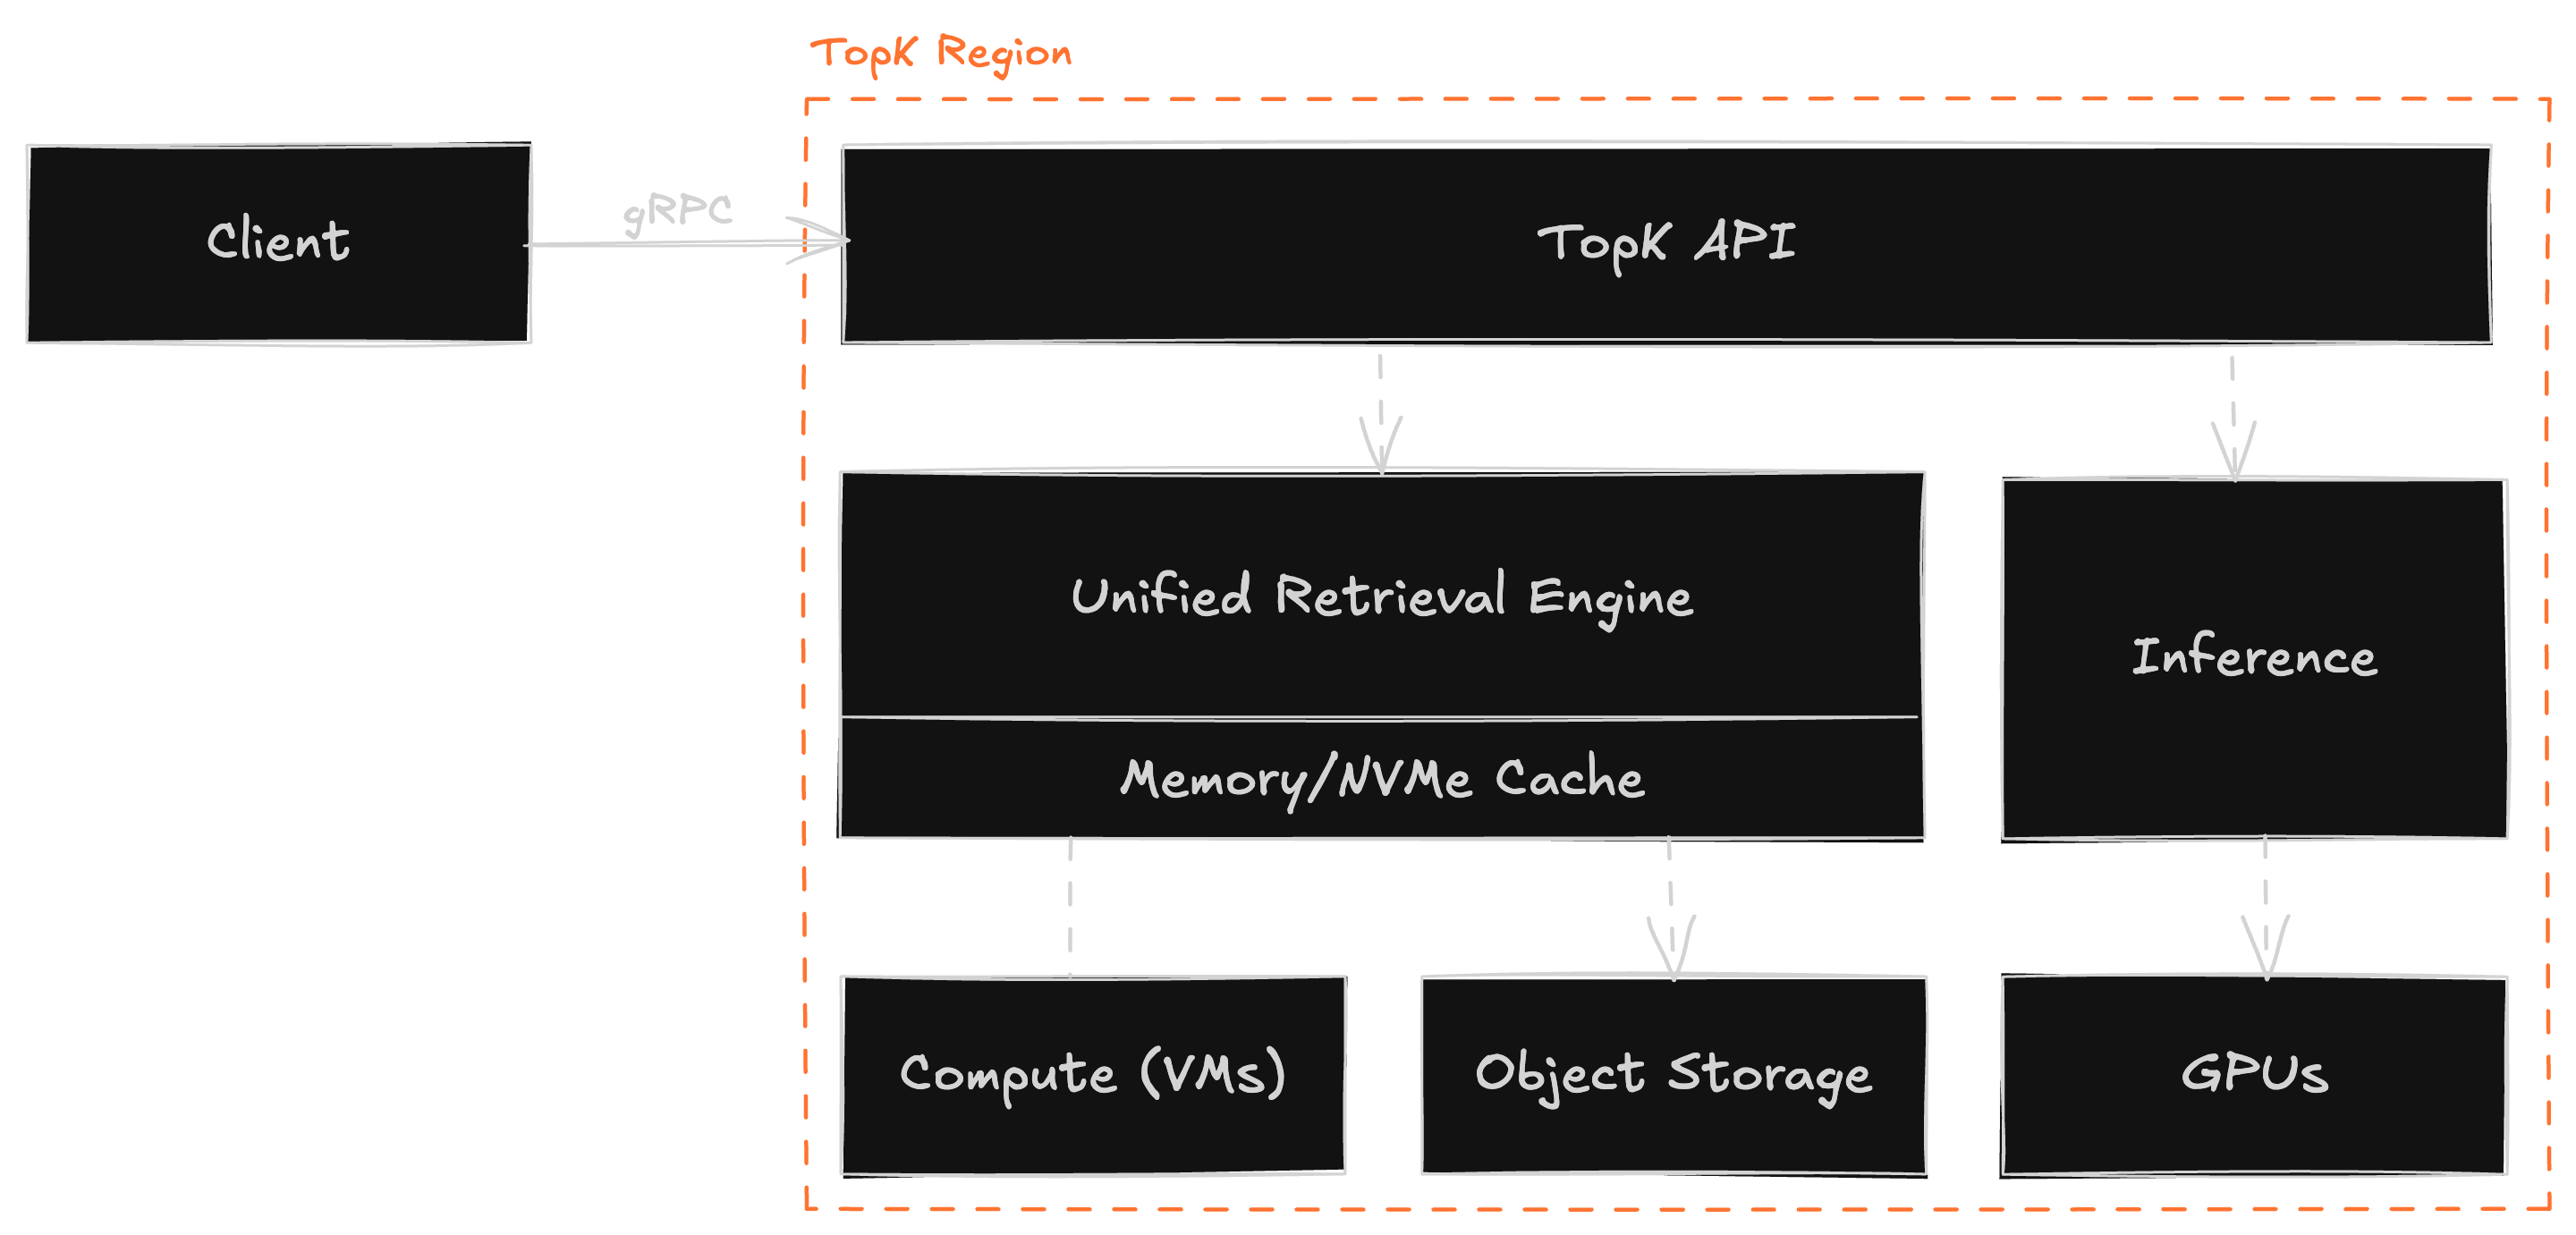 #### Data Flow
TopK is a multi-tenant service, which means that each tenant shares the same physical infrastructure with other tenants in the same region. This allows us to offer lower costs and better burst capacity. For enterprise customers that require full isolation and data residency, we offer dedicated single-tenant regions or cloud-prem deployments in customer-managed VPC.
{/* Data Flow Diagram */}
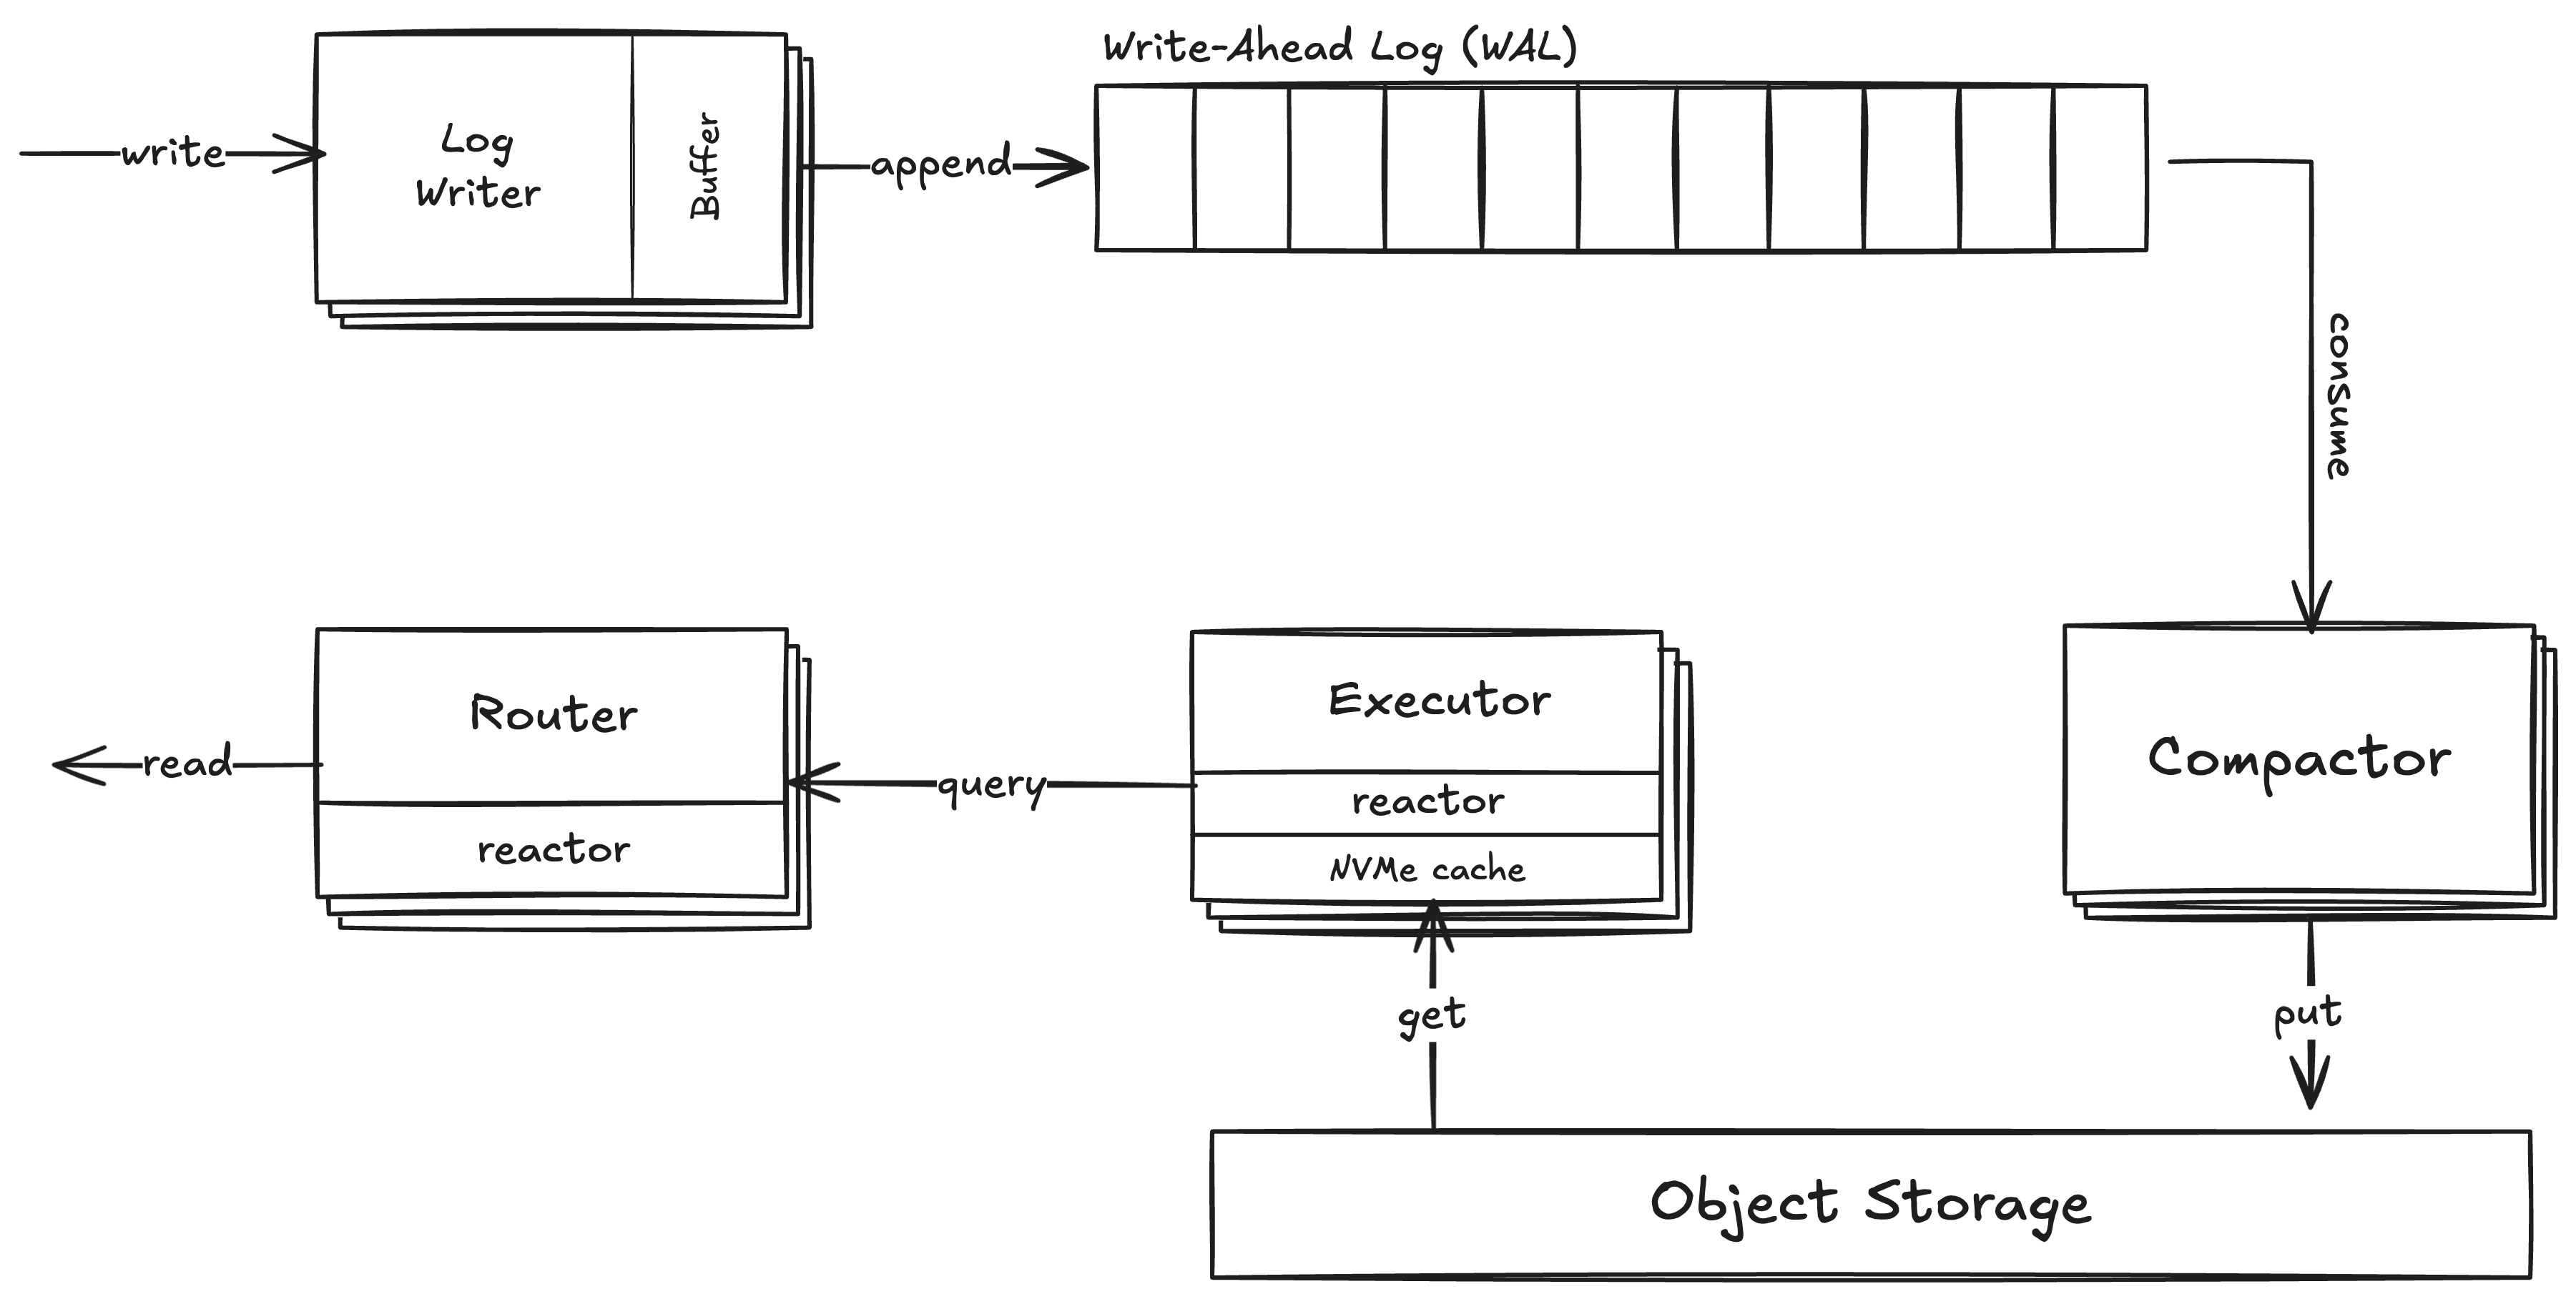
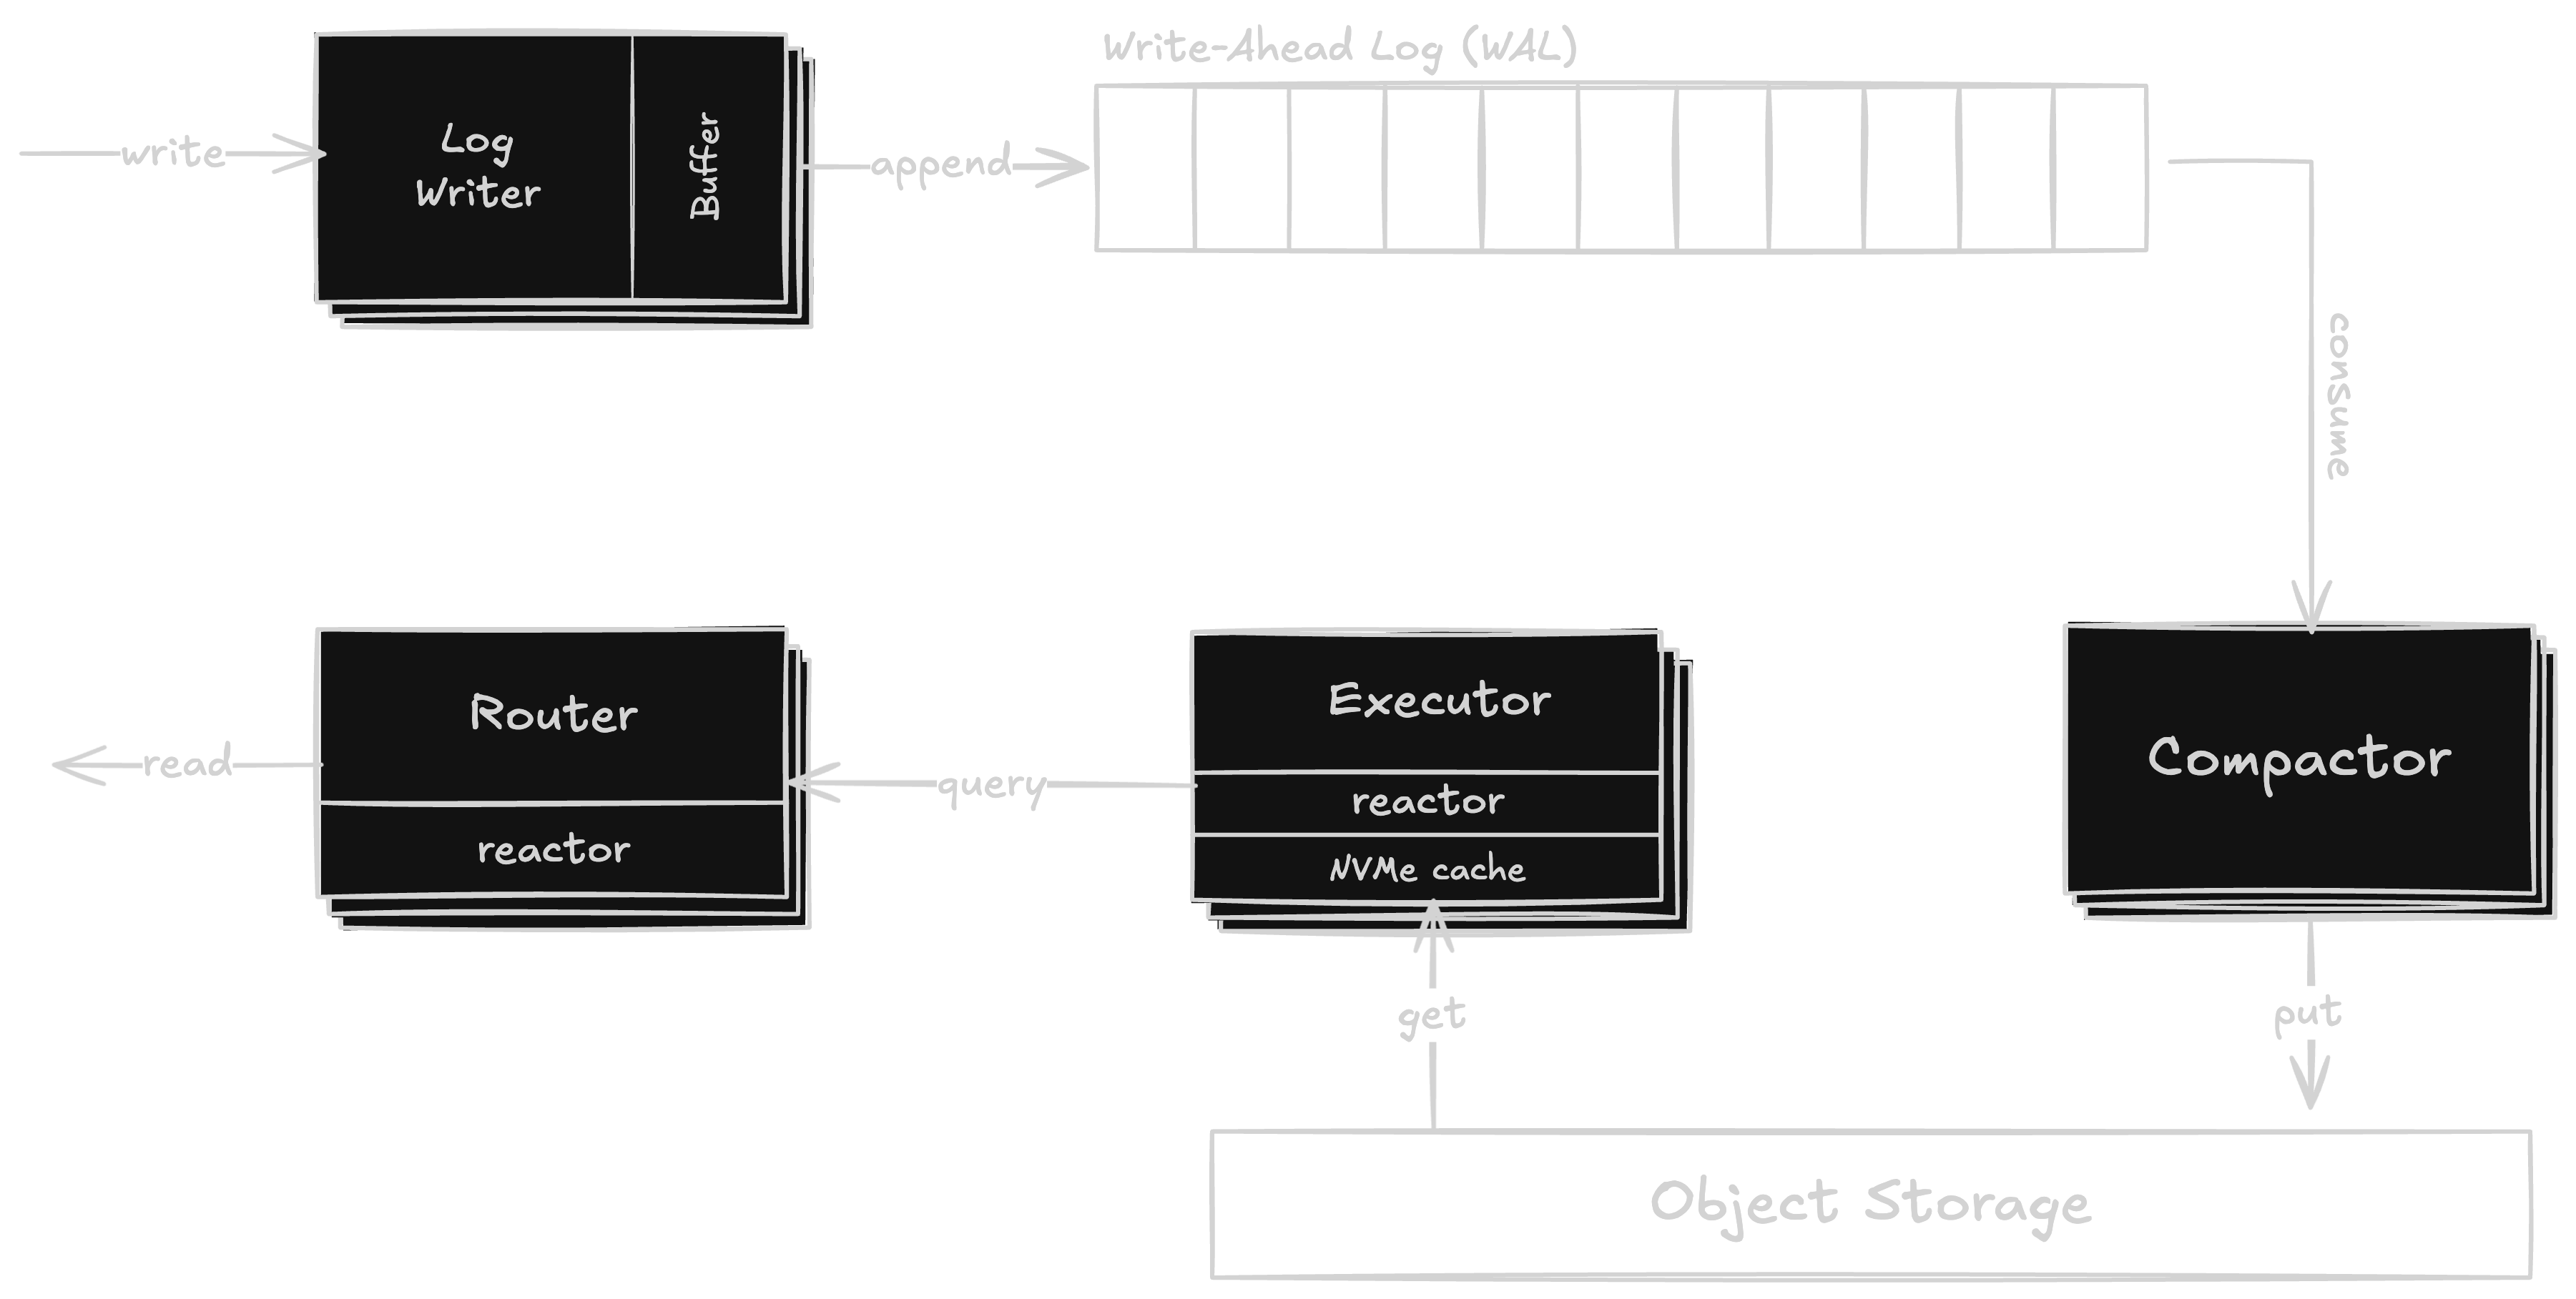 We decouple services that handle read path operations (query planning and execution) from services that handle write path operations (ingestion, indexing, and compaction) to separate node pools. This helps us scale resources cost-effectively and improves performance by reducing contention on the same physical infrastructure. Each collection has its own prefix on object storage, which isolates its data and helps us scale I/O request concurrency.
#### Write Path
##### Write-Ahead Log (WAL)
Write requests are durably persisted in a write-ahead log (WAL) which is backed by object storage. Entries in the WAL use logical log sequence numbers (LSN) to guarantee strict ordering and serializability. Once a write request returns successfully, data is guaranteed to be durably persisted to object storage. We employ dynamic batching to improve write throughput (~70MB/s or ~30,000+ vectors/sec) at the cost of higher write latency (~300ms p99 \<1MB).
##### Compactor (LSM-tree)
The write-ahead log is an append-only data structure with an unbounded number of entries. To optimize query performance and reduce storage costs, we periodically flush new WAL entries into more read-optimized format. The read-optimized files are stored as sorted runs inside a log-structured merge tree (LSM-tree). This tree is then periodically compacted to minimize read amplification, remove updated or deleted data, and minimize storage space.
Since all data is persisted on object storage with massive I/O throughput, we developed a scalable compaction planner and executor that allows us to flush new WAL entries and merge existing segments in parallel on a distributed set of nodes.
#### Read Path
{/* Data Flow Diagram */}
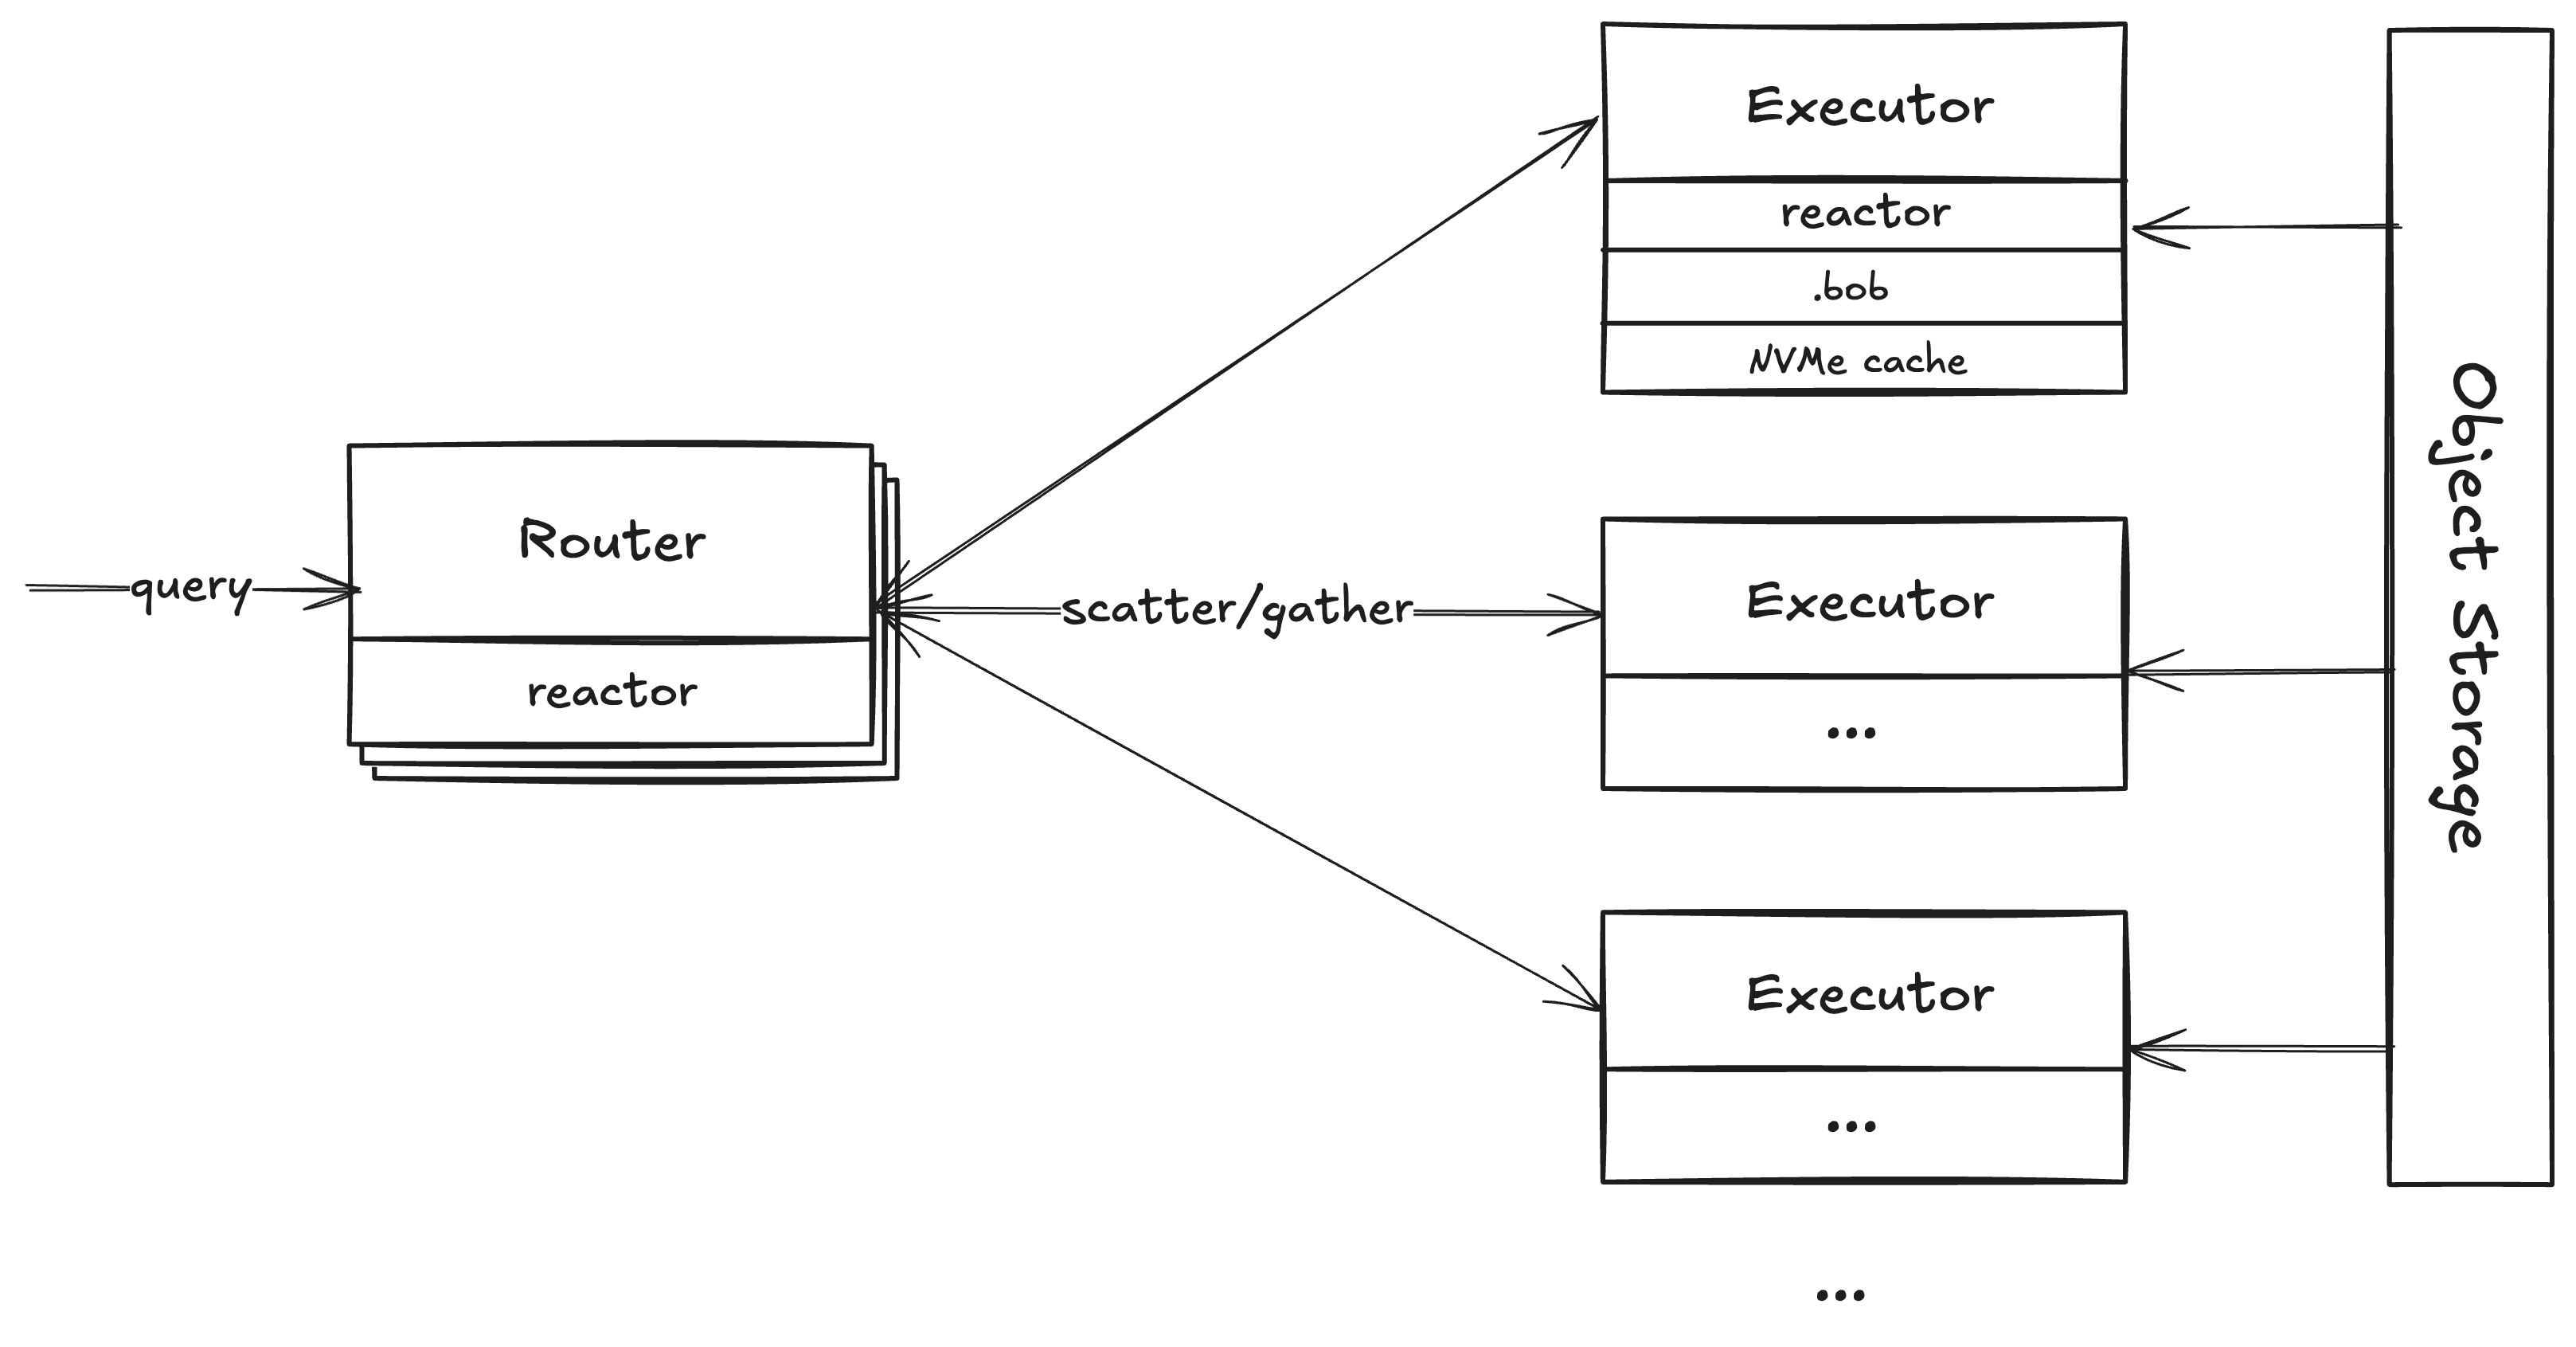
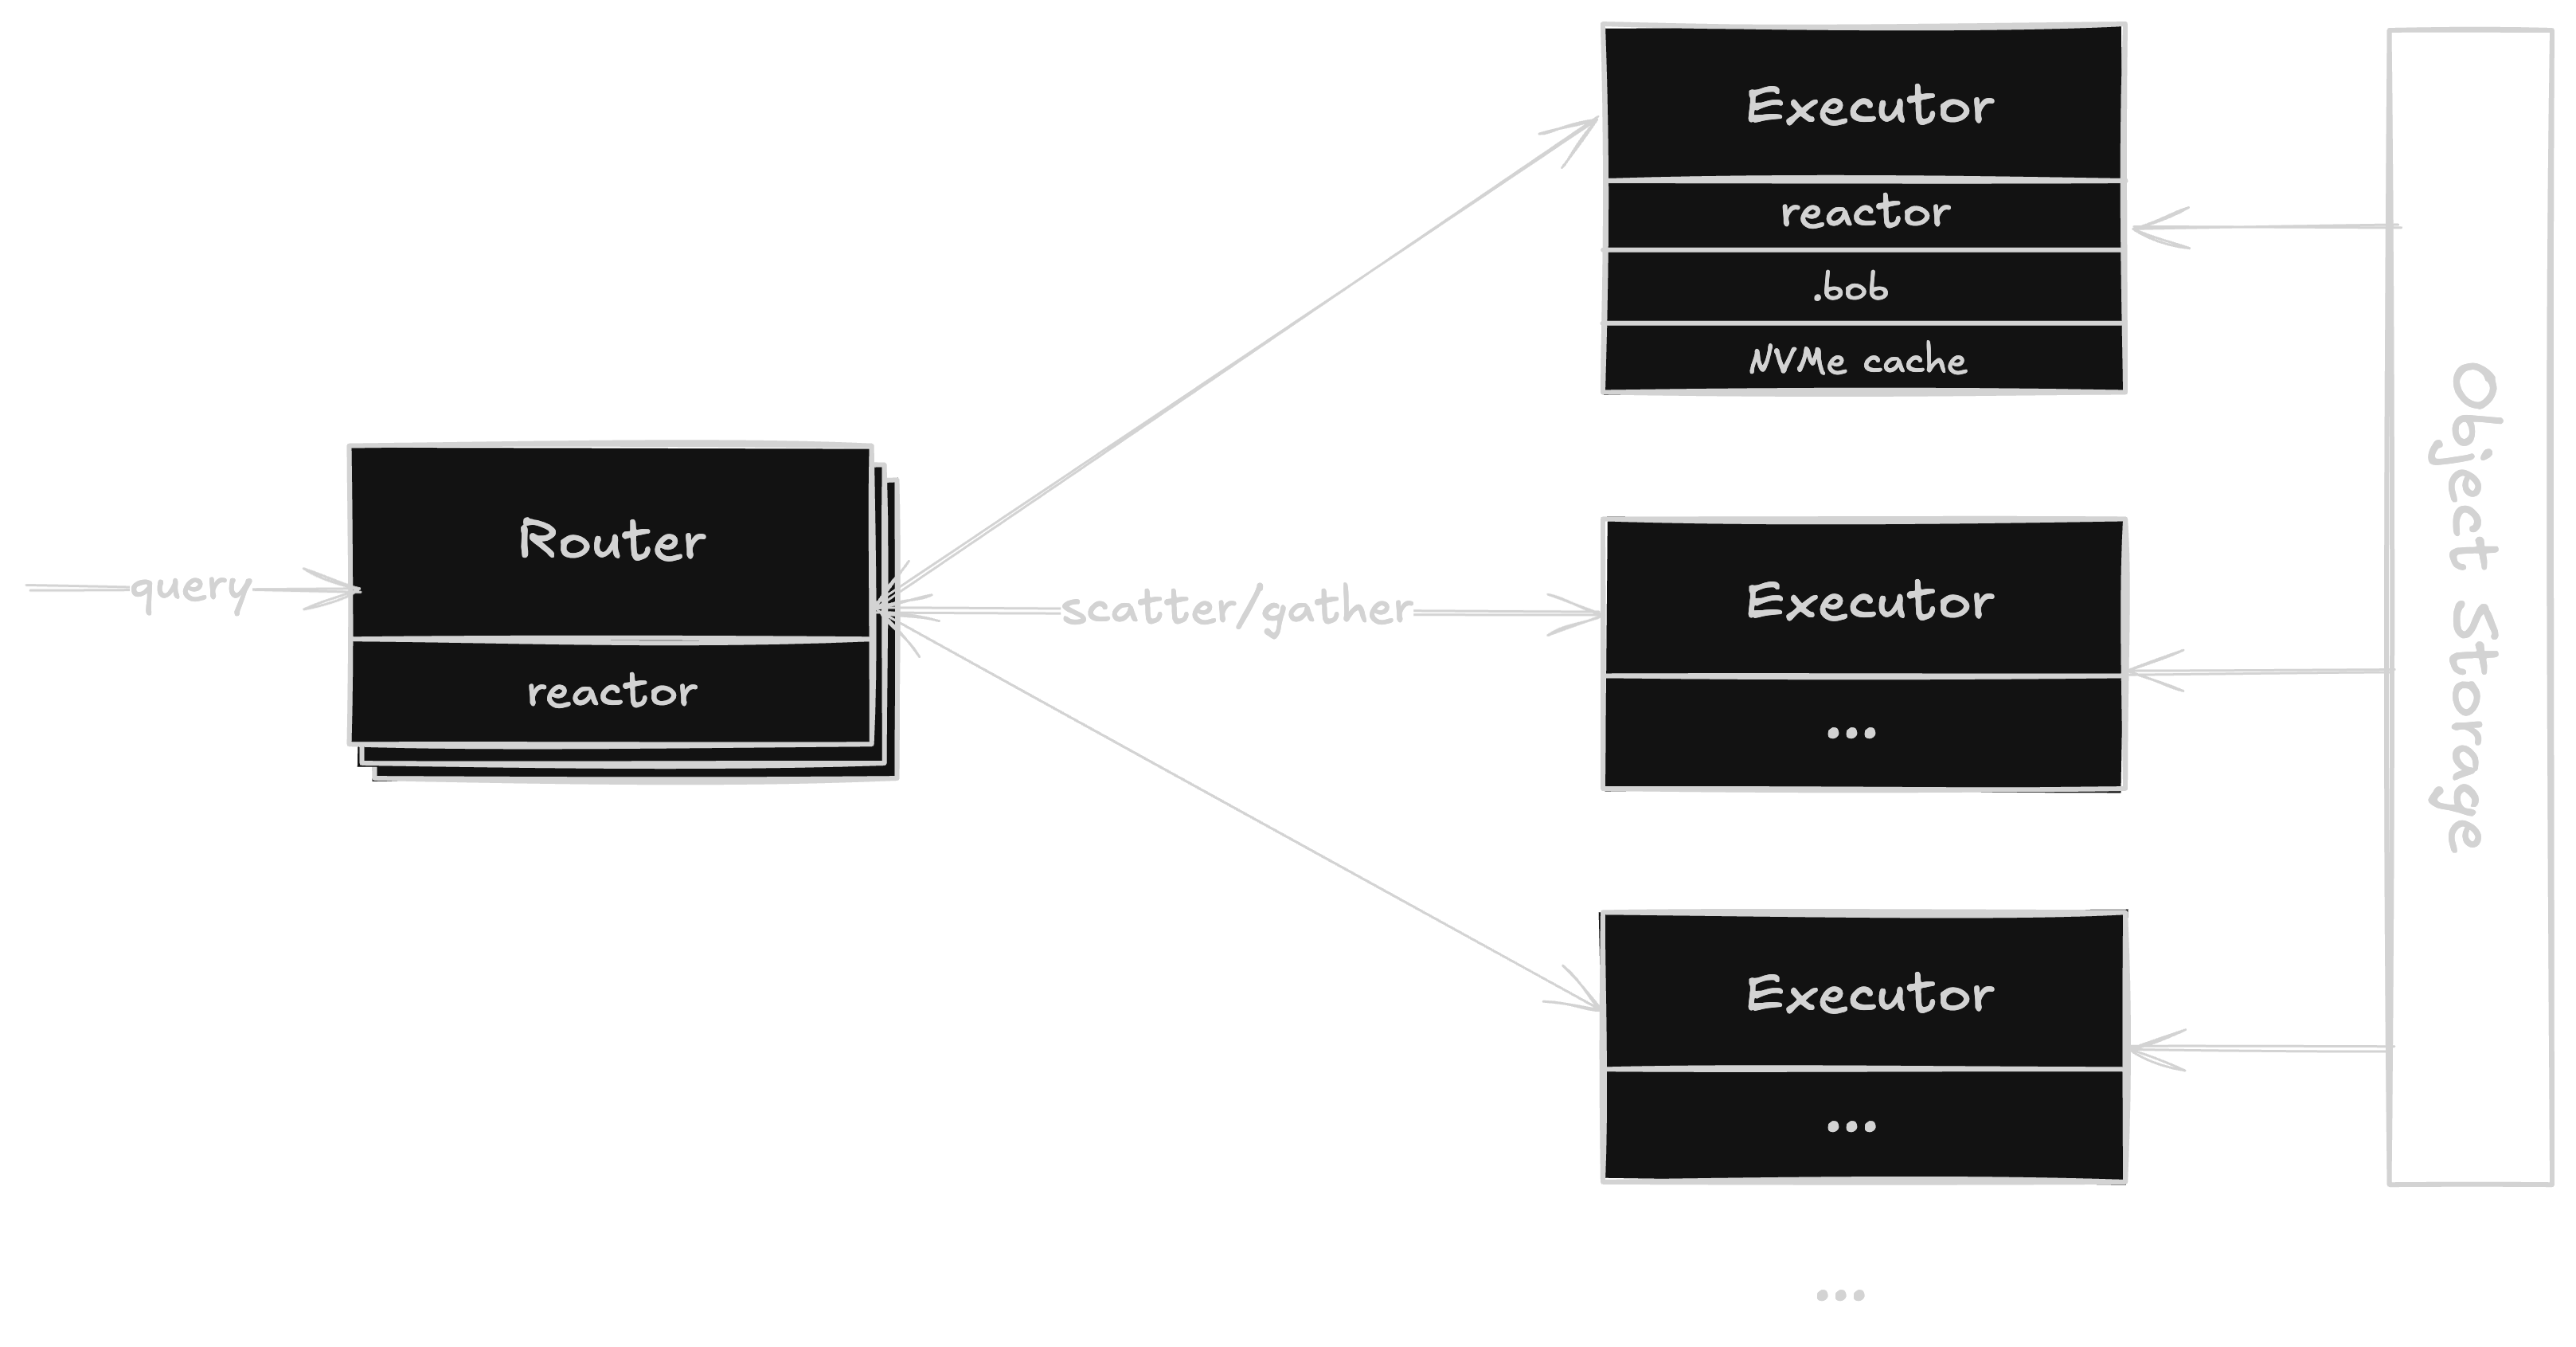 ##### Router
The router service is the front door for all read requests. It handles validation, query planning and optimization, consistent routing to optimize cache hit rates, and acts as a coordinator for distributed query execution. This decoupling allows us to horizontally scale compute resources and serve billion-scale collections with low latency and high throughput.
##### Executor
The executor service has two primary responsibilities: (1) executing (partial) query plans computed by the router and (2) caching data in memory and on NVMe SSDs. Every executor node is semi-ephemeral and fungible. In practice, this means that the persistent on-disk cache state survives restarts and deployments to minimize disruptions during rollouts. At the same time, we can lose an executor node without losing data or availability since the router will automatically redistribute requests to other executor nodes that will pull the required data from object storage.
##### Cache Hierarchy
Our query engine and storage format are designed from the ground up for multi-tier cache hierarchy. All data is persisted on object storage which is our primary/only durable storage. Executor nodes then cache a subset of this data required for query execution in memory and on locally attached NVMe SSDs to minimize latency and maximize throughput.
Cache placement and I/O requests are handled by our I/O runtime (based on `io_uring`) optimized to efficiently utilize the massive read throughput of object storage and NVMe SSDs.
#### Query Engine (`reactor`)
{/* Plan diagram */}
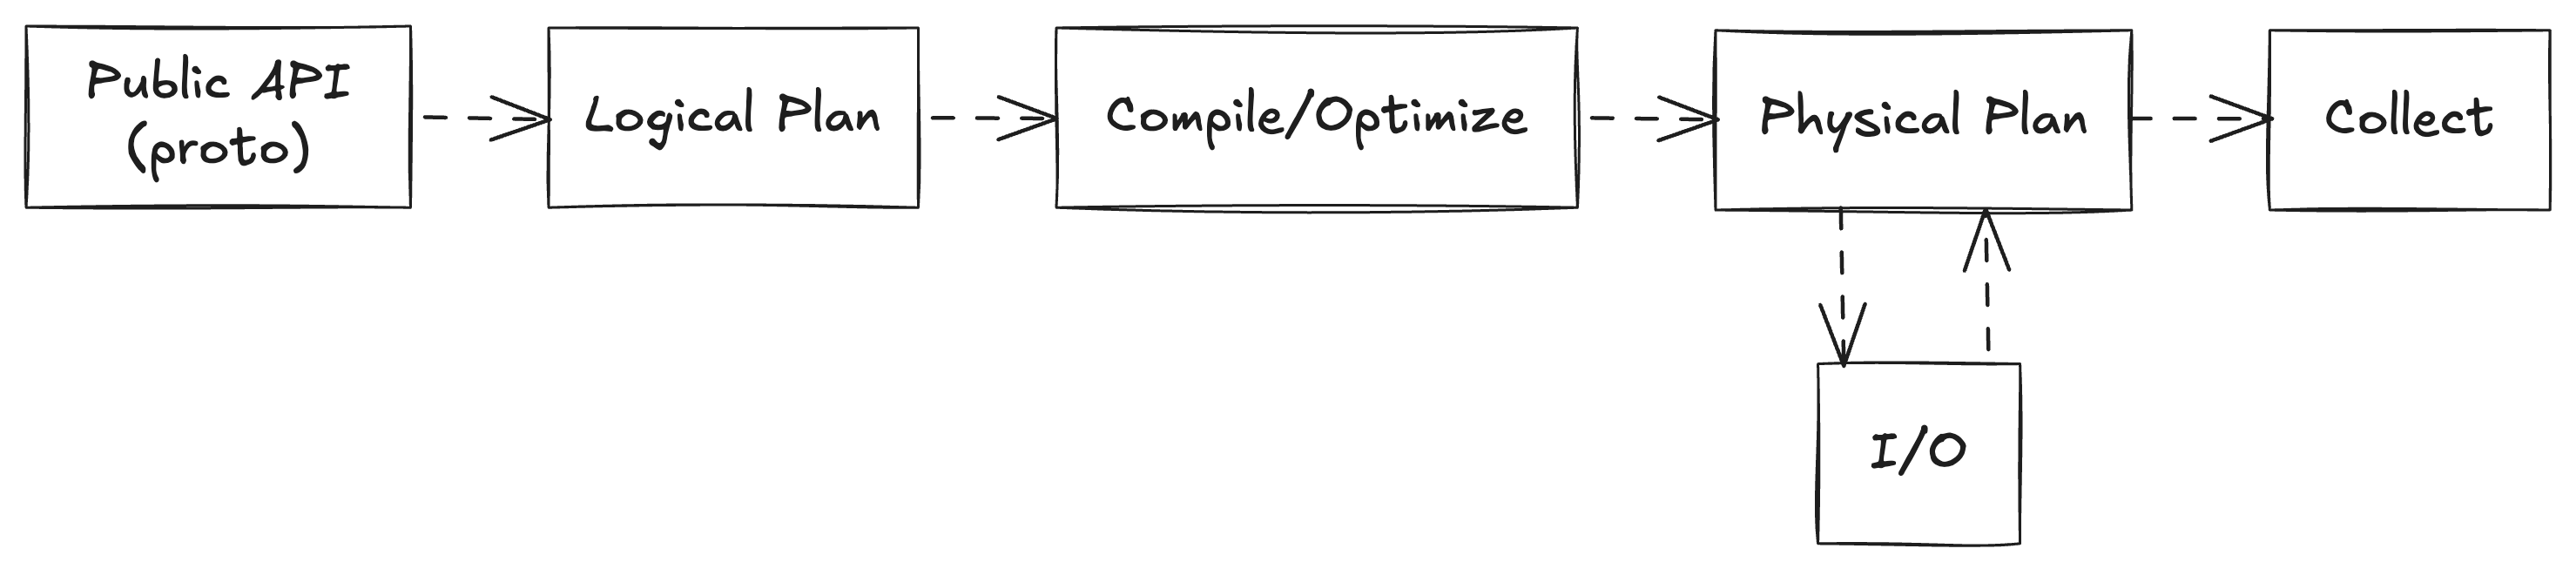
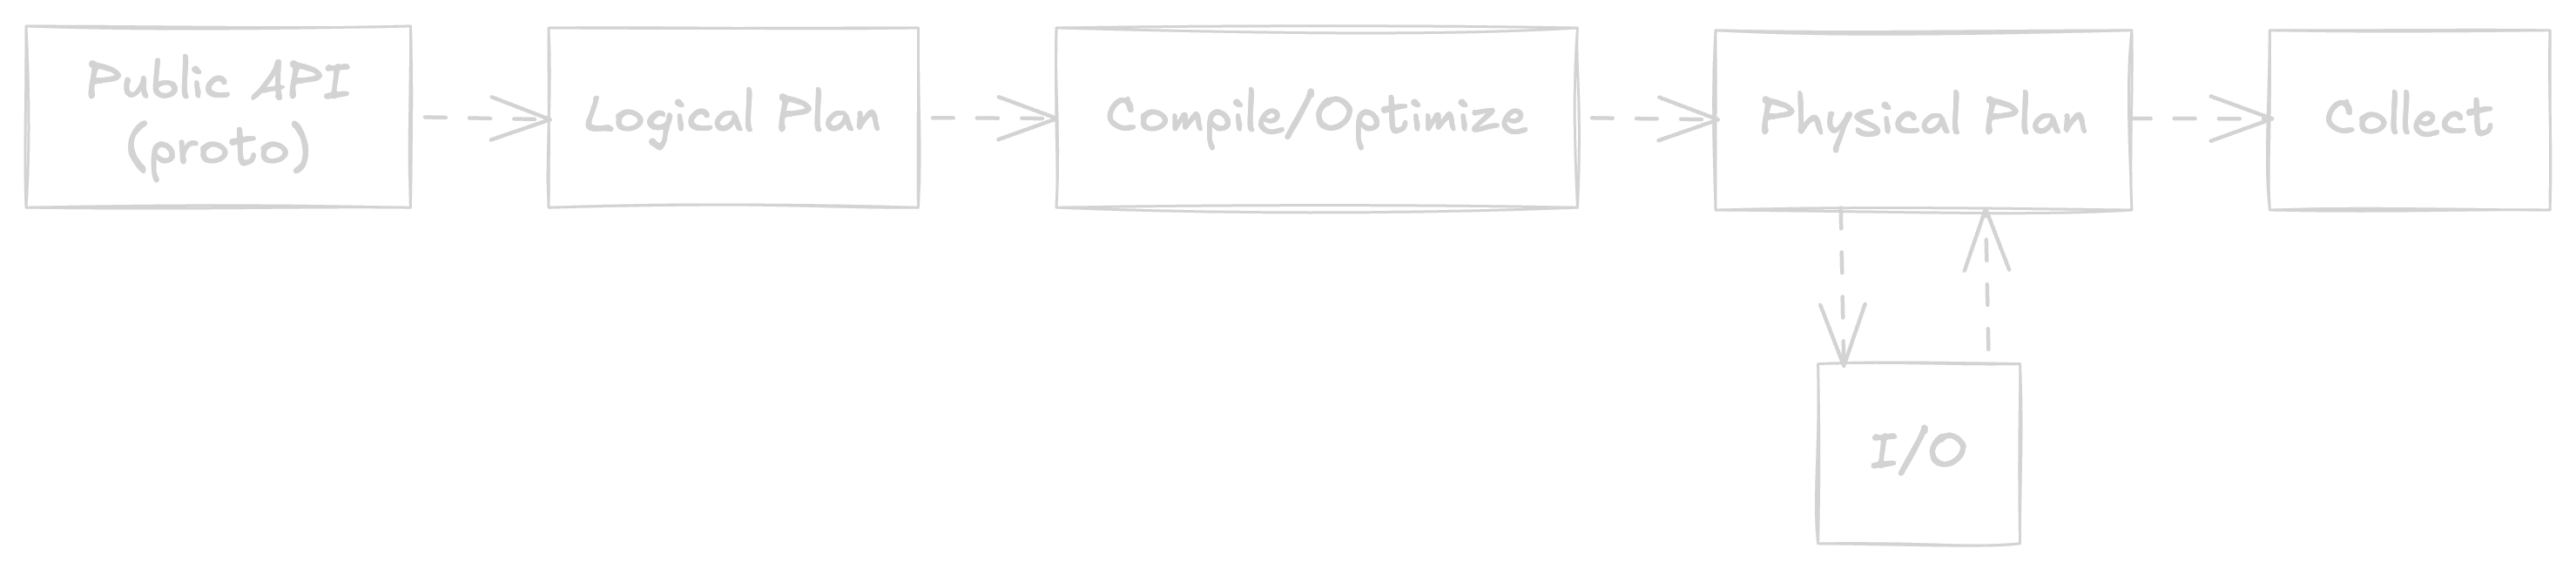 `reactor` is our proprietary query engine that enables us to combine different retrieval types, filter predicates, and scoring expressions in a single query. Conceptually, it's similar to other pull-based query engines (e.g. DataFusion) with heavy optimizations for zero-copy execution, search-specific SIMD kernels, quantization, vectorized filtering, pruning, and more. Additionally, it supports distributed query executions which allows us to reuse the same logical/physical operators in router and executor services.
#### File Format (`.bob`)
`.bob` is our proprietary columnar file format designed from the ground up for search on object storage. It supports zero-copy and zero-decode I/O with type-specific containers for compressed dense and sparse vectors, tensors, inverted indices, and more.
#### CMU DB: TopK Talk
Check out our talk at the Carnegie Mellon University Database Group where we dive deeper into the TopK architecture, `reactor`, `.bob`, and more.
### Concepts
URL: https://docs.topk.io/concepts
#### Collection
Collection is a low-level abstraction for storing JSON-like documents with indexed fields. Collections have an opt-in [schema](/collections/manage#schema) that defines required and optional fields, field data types, and field indexes. Every document stored in a collection must have an `_id` field as a unique primary key.
#### Indexes
Documents inside a collection can have multiple indexed fields defined in the collection schema. Field indexes enable efficient retrieval of documents based on [dense and sparse](/collections/manage#vector-index) vector embeddings, [multi-vector](/collections/manage#multi-vector-index) embeddings (late interaction), [keywords](/collections/manage#keyword-index) (BM25), [semantic similarity](/collections/manage#semantic-index), and their combinations.